vegeta pins nothing at build time, and versions itself twice
HTTP load testing tool and library. It's over 9000!
At a glance
- What is it?
- An HTTP load testing tool in Go, usable as a command and as a library, built around one idea: keep the request rate constant even when the target is slow, so the latencies you measure are the latencies a real user saw. The engineering behind that claim is careful. The packaging around it is not, in two specific and checkable ways that matter if you are putting this on a load generator or building from source.
- Who is it for?
- This fits someone measuring latency percentiles under load who has been told their previous tool's numbers were optimistic, and who wants a Unix pipeline rather than a report generator. It does not fit a team that needs a reproducible artefact from a known commit, because the build fetches its generators at their current version.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 51 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
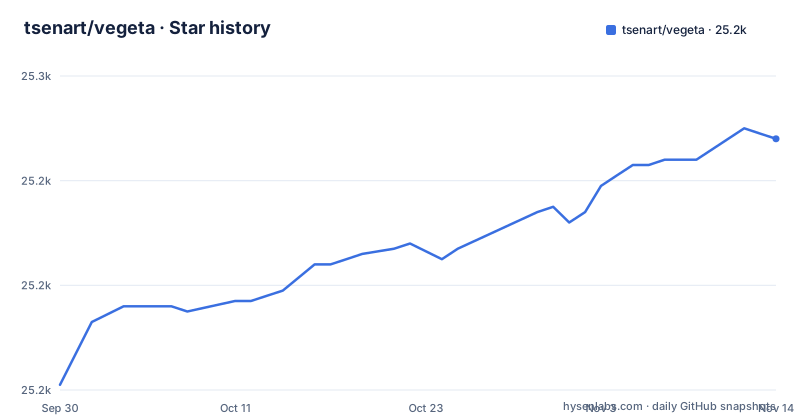
- tsenart/vegeta25,249 ★ · +48
| Repository | 2026-09-30 | 2026-11-13 |
|---|---|---|
| tsenart/vegeta | 25.2k | 25.2k |
48 Stars in the last 44 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Constant request rate is the whole idea, and the README argues it with a citation
The opening sentence states the problem the tool exists to solve: drilling an HTTP service at a constant request rate. Every feature follows from that.
The feature list's most important entry is not a feature at all. It is a link saying the tool avoids coordinated omission, and the link behind that phrase points at a well-known article arguing that most load generators report latencies better than any user experienced. The failure mode is simple once you see it. A generator that issues a request and waits for the response before issuing the next one reduces its own offered load the moment the target slows down, so the tail it measures is the tail of an unloaded system. The system was under less stress than the report suggests.
Holding the rate constant fixes that, because a slow target produces a growing queue rather than a shrinking request rate, and the measured latency includes the time a real user's request would have waited behind others. That is why the tool is built around a rate and a duration rather than around a concurrency setting, and why the duration flag's documentation warns that the actual run can take longer than the value you asked for because of response delays, and that zero means run forever.
The rest of the feature list is consistent with that: heavy reporting, composability designed for Unix pipelines, and a note about distributed testing that links a writeup of running a million requests per second across a cluster.
So the design decision is defensible and the reason is documented with a source rather than asserted. That is a good sign for the rest of the project, and it is worth holding in mind when you get to the packaging problems later, which are a different kind of carelessness.
A version number can mean two different builds, and the README says so
The versioning section is three paragraphs and it describes something unusual that has a direct consequence for you.
Both the library and the command are versioned under the second edition of the semantic versioning specification. That part is normal. Then it says that after version eight, the two components are versioned separately, in order to isolate breaking changes to each one.
The mechanics are specific. A command release is tagged with a prefix identifying the command line. A library release is tagged twice: once with a prefix identifying the library, and once with a bare version tag, and the README explains why the second one exists, because it is required for compatibility with the Go module tooling.
So one release produces up to three tags, and a version number in the twelve series is ambiguous by design. When you say you are running twelve thirteen point zero, you have not said whether you mean the binary or the library, and those two are cut from the same commit only sometimes. A command can gain a flag, a changed default, or removed behaviour without a library major version, because they are isolated from each other.
For a Go consumer that is genuinely good design. Isolation means a change to the command's output format does not force a library major bump, and a library API change does not make the binary a major version. For an operator it is a trap with no error message, because nothing stops you reading a tag, installing the command, and assuming the library you already have matches.
So the practical rule is to record both, and to treat the bare tag as the Go module's view of the world and the prefixed one as the operator's. The two will be equal more often than not, and the times they are not are exactly the times it matters.
The build installs its code generators at their current version
There is one line in the build file that should worry anyone who needs a reproducible artefact, and it is not a subtle one.
The binary target depends on a generation step, and the generation step does two installs before it generates anything. Both install commands name a tool and then say at its latest version. Then it runs the code generation directive across the module.
So every build reaches out and fetches whatever version of those two tools is current that day. Two builds of the same commit, a week apart, can run different generators. The output of code generation goes into the source tree, which means it is what gets compiled into your binary, which means two release binaries from one commit need not behave identically.
What makes this more than a theoretical complaint is that one of the two tools is already a pinned dependency of the module. So the same project is simultaneously exact about the version of that library as a dependency and completely open about the version of that same library as a build tool. There is no version constraint on the installed binary at all.
The container build inherits the problem, because it runs the generation target and the binary target in sequence. So the published image is not reproducible either, and neither is a binary you build yourself with the make target the README tells you to use.
None of this affects whether the tool measures latency correctly. It affects whether you can tell two runs apart, and for a tool whose entire purpose is producing numbers other people will make decisions from, that is the part you would want pinned.
The container's Go is older than the version the module requires
The container file pins a Go version and the module manifest declares a minimum, and the two do not agree.
The module requires a language version of one and twenty-two. The container's build stage is an image of Go one and twenty, on an Alpine release from 2023, and the runtime stage is that same Alpine release with nothing in it but the binary.
The gap matters because the Go toolchain only learned to download a newer toolchain on demand in a later release than one and twenty. In a one and twenty image, a module that asks for a later version is an error rather than a trigger, so a container build from this repository is relying on behaviour that toolchain version does not have.
It is plausible this is simply an unbuilt path. The README's own source instructions tell you to build with make, on your machine, after installing a current toolchain, and the pre-compiled release binaries are a separate route that skips all of this. So most people never touch the container file.
The runtime stage, though, is the part worth keeping. It copies a single statically linked binary into a plain alpine:3.18.0 image and sets it as the entry point, adding nothing else. The static linking is done deliberately in the build file, with the C library disabled and a net resolver tag, so the binary has no dynamic dependencies to satisfy on the target host.
That is a good design for the distribution, which makes the mismatch more noticeable rather than less. The packaging intent is clear and the version in the build file has simply drifted from the module.
The latency sketches come from the person who named the problem
Several libraries in the dependency list explain the reporting claims.
There is a t-digest library, which is an approximate quantile sketch. That is the algorithm you use when you cannot keep every latency measurement, because a load test at a meaningful rate produces more samples than you want to retain and you need percentiles rather than averages. The dependency list also carries other quantile estimators (bmizerany/perks, dgryski/go-gk and streadway/quantile), so the project has several sketching implementations rather than one.
The rest of the reporting stack is consistent with that. There is a library for downsampling a time series by keeping the largest triangles, which is the standard technique for drawing a latency-over-time plot that stays readable at a few hundred points, and the project has a plot command at the root of its source. There is a Prometheus client and the Prometheus server itself as direct dependencies, so results can be scraped as metrics rather than only read from a file.
There is also a property-based testing library among the module's dependencies, which for a tool whose correctness is statistical rather than deterministic is the right choice. You cannot assert that a percentile is exactly some number; you can assert properties of the sketch itself across generated inputs, and that is what this dependency is for.
Two shipped flags turn off the transport protections you would want on
The flag documentation is thorough, to the point of being a reference, and two of the flags deserve a second look before you script around them.
One specifies whether to ignore invalid server TLS certificates. That is a flag you need against a staging environment with a self-signed certificate, and it is a flag that silently accepts a man-in-the-middle if it is left on in a script that later runs against production. There is no environment-specific guard, because a load generator has no idea which environment it is pointed at.
The other specifies that HTTP/2 requests are to be sent over plain TCP without TLS encryption. That is a real requirement, because cleartext HTTP/2 exists and some service meshes and internal gateways expose it, but it is also a flag whose name is easy to misread as enabling HTTP/2 rather than disabling encryption on it. The wording in the documentation is unambiguous, which is at least something.
The rest of the flag set shows what a careful tool looks like. There is a flag for the number of processors to use, defaulting to the number available, and a flag to switch on processor or memory profiling during a run, defaulting to neither. There is a flag limiting idle open connections per target host and another limiting total connections per target, which are different controls and confusing to conflate. There is one for the local IP address to use, and one for a per-target address override that can be repeated, which is how you load test a cluster of replicas behind one hostname.
And the DNS cache duration flag is a small piece of interface design worth noting. It has three states, not two. A positive value caches for that long, a zero value caches forever, and a negative value disables caching altogether. That is a Go idiom, and it is exactly the kind of thing that surprises somebody who assumed a zero meant off.
Six install routes, none for Debian, and a target format that reads files
Two practical things to know before you install it.
The first is the install matrix, and the shortest route is one command on macOS:
brew update && brew install vegetaThere are pre-compiled executables from the release page, a macOS package manager formula, a MacPorts variant, an Arch Linux package, a FreeBSD port, and a source build. That is six routes, and the distribution list is conspicuous for what it lacks: there is no Debian or Ubuntu package and no Red Hat one in the README, so on those systems you take a pre-compiled binary or build it. Given that the binary is statically linked and single-file, that is a reasonable outcome rather than a gap, and it is the direct payoff of the build choices described earlier.
The second is the target format, which is where the composability claim becomes concrete.
There is a JSON format, designed for programs that generate targets dynamically. Each target is one JSON object on its own line, the method and URL are required, and a body must be base64 encoded. Crucially, the format is not described in prose: a schema file is generated and committed, and the documentation points at the schema as the definition. A machine-checkable contract for a tool's input format is the right call and almost nobody does it.
The other format is the hand-written one, and it is designed to look like a raw HTTP request. It supports custom headers, and bodies by file reference rather than inline, so a target can point at a JSON file on disk. Lines beginning with a comment character are ignored, so you can annotate a targets file. And the documentation says outright that this format was originally meant for people writing targets by hand for simple cases, which is an unusually honest thing for a tool to say about its own convenience path.
The example that shows the composability best is a three-stage pipeline where a JSON filter produces targets, the attack runs at a fixed rate, and a separate subcommand encodes the results:
vegeta attack -format=json -rate=100 | vegeta encodeThree commands, no intermediate file required, and the rate is a flag you can see.
Editorial conclusion
This fits someone measuring latency percentiles under load who has been told their previous tool's numbers were optimistic, and who wants a Unix pipeline rather than a report generator. It does not fit a team that needs a reproducible artefact from a known commit, because the build fetches its generators at their current version. Verify first which of the two version lines you actually need, since the library and the command are cut separately, then rebuild once and keep that binary rather than rebuilding per test run.
Frequently asked questions
how to install vegeta
Six routes are documented: pre-compiled executables from the repository's releases page, a macOS package manager formula, a MacPorts variant, an Arch Linux package, a FreeBSD port, and a source build that runs make and then moves the binary into a directory on your path. There is no Debian or Ubuntu package in the list, so on those systems you either take a pre-compiled binary or build it, which is workable because the binary is statically linked and has no runtime dependencies.
vegeta alternatives
The choice comes down to the design rather than a feature table. The distinguishing decision here is a constant request rate rather than a concurrency setting, with a documented argument for why concurrency-based generators under-report tail latency, and latency percentiles computed with quantile sketches rather than stored in full. Results can be read from a file, plotted, or scraped as metrics, and the pipeline style means each step is a separate command you can replace.
What is coordinated omission and why does vegeta mention it?
It is the case where a load generator issues a request and waits for the response before issuing the next, so when the target slows down the generator reduces its own offered load and reports latencies from a system that was under less stress than the report implies. Vegeta's feature list claims to avoid it and links an article about the problem. It holds the request rate constant instead, so a slow target builds a queue rather than reducing load.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tsenart-vegeta)Star history chart for your README
[](https://hysenlabs.com/projects/tsenart-vegeta)Was this useful?