tslearn: the getting started example prints NaN values and does not explain them
The machine learning toolkit for time series analysis in Python
At a glance
- What is it?
- A Python machine learning toolkit for time series that follows the scikit-learn estimator API, installs three ways including straight from the development branch, and carries a platform marker that pins the array library below its second major version on macOS because of an Intel build constraint. Its own first worked example pads two short series and then divides by an empty range, and prints the result.
- Who is it for?
- tslearn fits a Python project that has outgrown a hand written distance function and wants k-shape style machinery with the estimator interface its users already know. Four things to know.
- Can I use it commercially?
- Yes. BSD-2-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
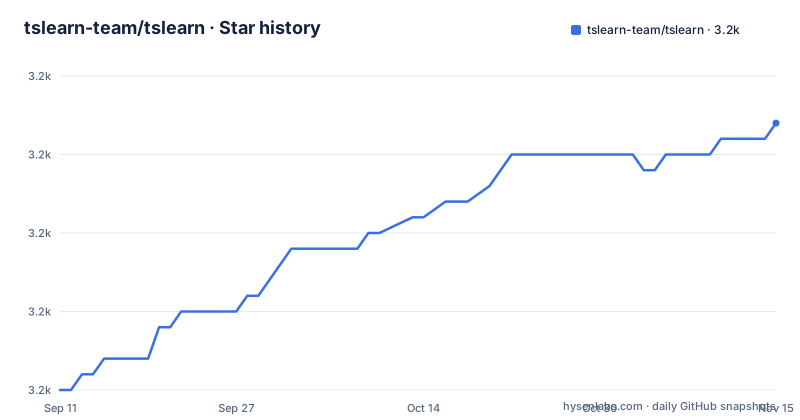
- tslearn-team/tslearn3,192 ★ · +17
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| tslearn-team/tslearn | 3.2k | 3.2k |
17 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The getting started example prints NaN values without explaining them
The most instructive thing in this README is an accident of the second worked example. Three series of different lengths are converted into the toolkit's three dimensional format, then passed through a min-max scaler, and the printed result is
[[[0.] [0.667] [1.] [0.333] [nan]]
 [[0.] [0.333] [1.] [0.333] [nan]]
 [[0.] [0.333] [1.] [0.333] [0.333]]]
Two of the three rows end in a not-a-number value, and the text around the example says nothing about it. The cause is structural rather than a bug in the scaler: the format pads every series to the length of the longest one, and those padded cells hold the toolkit's padding value, which the scaler then divides and subtracts like any other. The example is four lines long and it is the first thing a reader runs after formatting their data, so the first impression of the library is a result containing undefined values.
Padding to the longest series is why the scaler divides by an empty range
The data format section says the array has three dimensions: the number of series, the number of measurements per series, and the number of dimensions. The second dimension is the maximum across the set, which means a short series is padded and a long one is not. The preprocessing section then offers scaling to help different algorithms converge, resampling to shorten training, and piece-wise transformations. Nothing in that section says the padding participates in the statistics. For a per-series scaler the practical rule is that the padding has to be excluded, or the range of the padded tail becomes the denominator, and a reader has to work that out from the printed output. It also means the third series in the example is the only one without a trailing undefined value, which is a clue the README could have followed and did not.
One install route pulls the development branch archive
There are three installation routes and they are not equivalent. One installs from the Python package index, one installs from a conda channel, and the third installs from a zip archive of the main branch hosted on the forge. The third is a development route: it fetches whatever is on that branch at the moment you run it, which for a project whose last commit is recent and whose newest release is three months old is a materially different artefact from a release. The section also says, in a sentence worth pausing on, that the required dependencies must be installed for the installation to succeed. For a package that declares its dependencies, that is either a note about conflicts or a leftover from an era when the dependencies were not declared, and either way it sends a first-time installer looking for a problem that the packaging metadata already handles.
macOS gets an array library pin because of an Intel build constraint
The manifest's optional dependency groups are where the platform story shows. There is a group that adds the deep learning framework, one that adds it specifically for reusing pretrained models through a foundation module, one for tests and one for building the documentation, plus a combined group that pulls all of them. That combined group contains a comment explaining that the framework dropped support for Intel macOS after a version which itself does not support the second major version of the array library, followed by a dependency specifier that pins the array library below that major version only when the platform marker matches macOS. So on a Mac the effective array version is older than the base requirement suggests, by a rule that lives in an extras file and is invisible to someone reading the main dependency list.
The version lives in the package attribute while a source-control tool is a build requirement
The manifest does not contain a version number. The project table declares the version as dynamic, and the tool configuration points that at an attribute inside the package itself, so the published version is whatever the package says it is. At the same time the build requirements include a source-control versioning tool, which derives versions from tags when a project follows that convention. Two mechanisms for the same fact, and the manifest uses the first while carrying the second. The practical effect is on anyone building from a checkout: a tagged commit produces a sensible version, and an untagged one produces something derived from the commit rather than a release number, which is why the release list and the branch can disagree about what is current.
The documentation build pulls a forecasting model
The documentation dependency group is longer than a documentation group usually is. Alongside the documentation generator, a theme, a gallery extension, a copy button helper, a docstring processor, plotting, and a document conversion tool, it includes the deep learning framework, because the gallery's examples need it, and a time-series forecasting library at a stated minimum version, because an example needs that too. So building the documentation installs a foundation model package and runs whatever code in the examples touches it. That is a reasonable trade for a gallery that demonstrates pretrained models, and it is also why the docs group is not the group to install on a machine where model downloads are unwelcome.
The readme carries instructions to itself and one badge loads over plain http
The file is assembled from HTML blocks with comments left in place describing each part: a comment before the logo block, one before the badge row, one before a horizontal rule, one before the table of contents. It reads like a template that was filled in and shipped with its scaffolding notes, which is harmless and occasionally useful. Two details in the badge row are worth noting. The documentation badge's image address is written with a plain http scheme while the rest of the file is https, so a reader loading that badge does so without transport security. And the build badge points at a continuous integration project inside one person's account rather than an organisation, while the same person's name appears as the package author and in the contact address in the manifest.
Editorial conclusion
tslearn fits a Python project that has outgrown a hand written distance function and wants k-shape style machinery with the estimator interface its users already know. Four things to know. The documented input format pads every series to the longest one, which means per-series statistics over the padded values can be undefined, and the README's own example shows that happening without comment. One of the three install routes tracks the development branch, so it is not a release. The array library is version constrained differently on macOS than elsewhere, for a reason documented in the manifest. And the version number is read out of the package rather than declared, with a source-control versioning tool in the build requirements, so a build from an untagged checkout is not a release either.
Frequently asked questions
How do I install tslearn?
Three documented routes: install from the Python package index using the pip module, install from the conda-forge channel, or install directly from the main branch archive on the forge. The README also notes that the required dependencies must be present for the installation to succeed, and points at the documentation for a longer guide.
What input format does tslearn expect?
A three dimensional array whose dimensions are the number of series, the maximum length across the set and the number of features, with shorter series padded to the longest. Variable-length series are also supported. Utility functions convert a list of lists into that shape, and there are documented paths for other toolkits, public benchmark datasets and synthetic data.
Why does scaling a tslearn dataset produce NaN values?
Because the format pads shorter series to the length of the longest one, and a min-max scaler then divides by each series' range. The README's own printed example shows two of three series ending in a NaN at the padded position, without comment.
Does tslearn work with scikit-learn?
Yes. The README says the estimators follow the same API as scikit-learn's and are fully compatible with it, so utilities such as hyper-parameter tuning and pipelines can be used with them. The package depends on scikit-learn directly at a stated minimum version.
What tasks does tslearn support?
Classification, clustering and regression, plus analysis utilities including barycenters of a group of series and distances computed with a variety of metrics. The README's features table is organised into data, processing, clustering, classification, regression and metrics columns.
What are tslearn's optional dependency groups?
Four: one adding the deep learning framework, one adding it for reusing pretrained models through the foundation module, one for tests and one for building the documentation. The documentation group also pulls a forecasting library, and the combined group pins the array library below its second major version on macOS because of an Intel build constraint.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tslearn-team-tslearn)Star history chart for your README
[](https://hysenlabs.com/projects/tslearn-team-tslearn)Was this useful?