The linter version is duplicated in a workflow file, one lint target runs a different tool, and make test starts the API
Open source and extensible Platform as a Service (PaaS).
At a glance
- What is it?
- tsuru is a platform as a service that runs on Kubernetes, with a command line client shipped from a separate repository. Its readme is a local development guide rather than a product page, and it is unusually careful in two places: the credentials it prints are development defaults, and the integration tests are told not to touch your real cluster configuration.
- Who is it for?
- tsuru suits a team that wants to run its own application platform on Kubernetes rather than rent one, because the deployment model is a command line tool plus a provisioner and the language support is a plugin repository rather than a rewrite. Three things to know.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
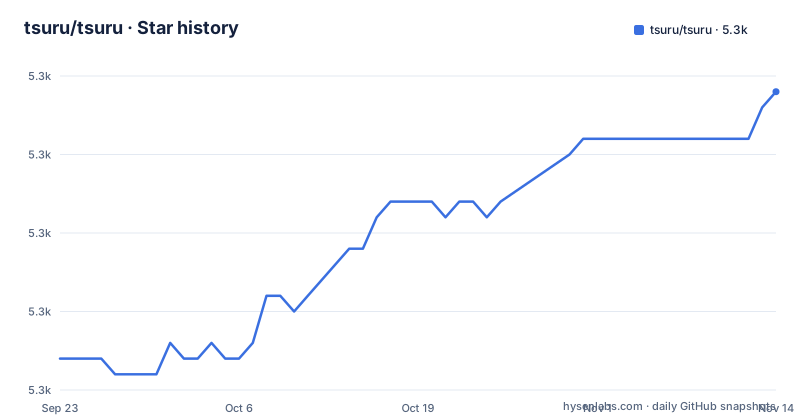
Star history
- tsuru/tsuru5,329 ★ · +17
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| tsuru/tsuru | 5.3k | 5.3k |
17 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository layout is the architecture
The top level of this repository is a list of concerns rather than a list of libraries, and reading it is the fastest way to understand the design. There is a package for applications, another for the API surface, and separate ones for authentication, logging, building, executing commands, provisioning clusters, permissions, quotas, tags, volumes and validation. A few names are more telling than the rest. There is a package called safe. There is one for event handling and another for jobs. There is a formatter for streamed output, which is what a log aggregator needs. And there is a directory whose name is an abbreviation rather than a word, which is the kind of thing you only find in a codebase old enough to have accreted its own vocabulary.
The linter version lives in two files and one lint target runs a different tool
The build file pins the version of the Go linter in a variable, and immediately above it carries a comment saying to keep it in sync with the version used by the linter action in a workflow file. That is a duplicated value with a human being responsible for it, which is a small but real fragility in a repository of this size. The same file has a formatting target and a linting target for YAML, and both install the same tool at the same pinned version if it is missing, which means a fresh machine fetches the tool twice or races itself. The more confusing detail is naming: the target called the YAML linter does not invoke a tool of that name at all, it invokes the formatter in lint mode, and the failure message tells you to run the other target to fix it. So the name you would reach for and the name you would run are different.
make test also boots the API in a dry mode and deletes the binary
The default target of the build file is its test target, and that target does two unrelated things. The first walks the package list, skips the integration package, and runs the suite once with a verbose flag that only one of its testing libraries understands, falling back to a plain run if that flag is rejected. The second builds the daemon, starts it against a configuration file in a mode that resolves everything and touches nothing, and then deletes the binary it just built. That second step is the interesting one, because it means the default build target validates that the service can parse its own configuration and initialise, rather than only that the unit tests pass. It also means a broken configuration file breaks the default target, which is a feature if you want it and a surprise if you were expecting only tests.
Five internal libraries are pinned by commit, the oldest from 2015
The dependency list reads like two projects stitched together. The current half is unremarkable and modern: a cloud SDK, a container runtime client, a command line client, JWT handling, a Prometheus client, tracing and metrics, a document store driver, an autoscaling framework, a cron parser. The other half is a set of libraries owned by the same organisation, pinned by commit rather than by version, and their dates are all over the place: a configuration library from 2020, a table formatter from 2019, a test helper from 2016, a flag-parsing library from 2015, and a deploy agent from 2024. Alongside them sit a mail server library pinned to a 2013 commit and a process-inspection library from 2018. So the effective surface is broad and partly frozen, which is worth knowing before you decide what to upgrade.
Five services, one privileged, one writing to a host path
The development compose file is the clearest description of what the system needs at runtime, and it is a longer list than you might expect. A document store with its file-descriptor limit raised to sixty-five thousand, with a comment explaining that the tests open connections faster than the default allows. A container image registry, published on a port, with its storage in an anonymous volume at /var/lib/registry rather than in a named volume. A deploy agent pinned to a specific version, talking to a build service over its own address. The build service itself, running privileged, with a configuration file mounted into it. And the API, built from the repository, with its configuration mounted read-only, and placed behind a compose profile so it does not start with the others. Two of those five have elevated privileges or host file mounts, which is fine for a development stack and worth noting before copying the file anywhere else.
The image bakes in two cloud authentication plugins at build time
The runtime image starts from a bare Linux distribution and installs ca-certificates and curl, then downloads two binaries from other projects and checks them by running their version commands. The first is a Google Kubernetes authentication plugin, whose download filename depends on the target architecture, selected by a conditional inside the shell command itself. The second is the AWS IAM authenticator, named with its own version twice in the URL. So an image build reaches out to two third-party release endpoints, and the base distribution version and the language toolchain version are both build arguments at the top of the file rather than hard-coded. One structural detail is unusual enough to notice if you read the file top to bottom: the exposed port, the entry point and the default command are all declared before the line that copies the built binary into place.
Two published development credentials and a hard rule about cluster configuration
The local walkthrough prints a login with its password in a trailing comment, and it is worth naming plainly that these are development defaults for a cluster on your own machine. The same walkthrough then does the two things that actually require care. To deploy anything you create a team, add a pool, and label the cluster nodes with the pool name, using the cluster command line tool directly, with a reminder to make sure you are pointed at the right configuration. And to run the integration tests you must create a separate configuration file, pass it in through an environment variable, and the readme states in bold that this file must not be the one in your home directory and must point only at the local cluster:
tsuru login [email protected] # password: admin@123That instruction is the most valuable line on the page.
Editorial conclusion
tsuru suits a team that wants to run its own application platform on Kubernetes rather than rent one, because the deployment model is a command line tool plus a provisioner and the language support is a plugin repository rather than a rewrite. Three things to know. The readme you are reading is a development guide: it walks through running the API against a local cluster and it prints development credentials on the way. The integration tests are the sharp edge, because they deploy into whichever cluster the configuration file you pass names, and the readme is explicit that the file must not be the one in your home directory. And the build tooling keeps some values in two places by hand, which is the kind of thing to check before trusting a release.
Frequently asked questions
what is tsuru
An open source and extensible Platform as a Service. You write applications in whichever language you like, attach databases and caches as add-on resources, and manage everything through a command line tool. It runs on Kubernetes, and the readme's own verification step is that listing apps returns a single dashboard app.
Which languages does tsuru support?
The readme lists eight platforms, each linking into a separate platform repository: Python, Node.js, Go, Ruby, PHP, Perl, Lua and Java. The framing is broader than the list, since the claim is that you can write apps in the language of your choice and the platforms are the popular ones rather than the only ones.
How do I install tsuru locally?
Install a container engine or Podman, minikube, Go and a YAML tool, then run the setup target followed by the run target, and point the command line tool at a target named for local development. On macOS the page recommends a particular minikube driver with a helper, and it notes that using Podman means passing the engine name to the make commands.
What are tsuru targets?
Named endpoints the command line tool talks to. The readme compares them to the configuration contexts in the cluster's own command line tool, which is the right mental model: you switch environments by name. The local development flow sets one named for local development so the tool talks to your local API instead of a remote server.
How do tsuru integration tests avoid deploying into my real cluster?
The readme requires a configuration file that must not be the one in your home directory and must point only at the local minikube cluster, and it is passed to the make target through an environment variable.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tsuru-tsuru)Star history chart for your README
[](https://hysenlabs.com/projects/tsuru-tsuru)Was this useful?