Personal use only, non-commercial weights, and an empty default JWT secret
DataInfra Series. Redact EVERYTHING with local llms and vlms.
At a glance
- What is it?
- RedactionEverything is a local redaction workbench that splits documents into a text path and a visual path, using HaS Text for semantic entity recognition and LocateAnything-3B for faces, seals and signatures. It is not open source under any standard licence, the vision weights it depends on cannot be used commercially even by a paying customer, and the shipped compose defaults enable authentication while leaving the signing secret empty.
- Who is it for?
- It fits an individual doing their own redaction on documents they are allowed to process, with a GPU workstation and patience for a six-service local stack.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 19 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
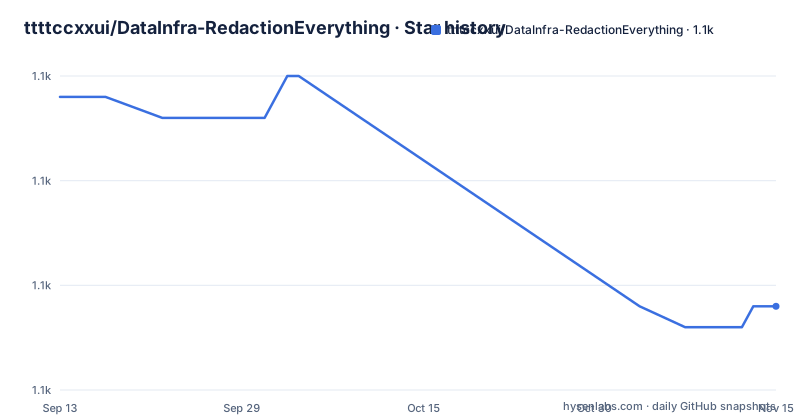
- ttttccxxui/DataInfra-RedactionEverything1,134 ★ · -10
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| ttttccxxui/DataInfra-RedactionEverything | 1.1k | 1.1k |
-10 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The licence reserves paid work, teams and production, and the weights reserve more
The repository is described as using a custom Personal Use License, where individuals may use it free for personal, non-commercial purposes, and where paid work, consulting delivery, companies, institutions, government agencies, teams, hosted services, production deployments, OEM redistribution and commercial integrations each require a separate commercial licence. So the word open source does not apply here in any licence sense, and the metadata field for the licence asserts nothing at all. The second paragraph is the harder constraint: a commercial deployment must clear third-party component licences on its own, and the table says the LocateAnything-3B weights are released under an NVIDIA non-commercial licence while PyMuPDF is AGPL-3.0, dual licensed commercially by Artifex. That means paying the author does not clear the vision path. A contact address is given for commercial licensing, support and procurement, and the full component table sits behind the License heading further down the file.
The build badges point at a different GitHub account
Two badges at the top of the README resolve to `TracyWang95/DataInfra-RedactionEverything`. The first is the CI badge, aimed at that account's `actions/workflows/ci.yml`, and the second is the star badge aimed at that account's stargazers page. The repository itself lives under a different owner. Nothing in the visible file corrects this, so the badge that tells you whether the tests are passing is reporting on another repository, and the star counter it displays is not this one's. It reads like a project that was moved or renamed without the README following. There is also a Chinese README at README_zh.md, so at least the translated copy is a sibling file here, while the badge URLs were left pointing outward.
Authentication defaults on and the signing secret defaults to empty
The compose file is more interesting than most. `AUTH_ENABLED` defaults to true, which is the right call, and `JWT_SECRET_KEY` defaults to an empty string, which undoes part of it, since a deployment that never sets it is signing tokens with a key that is in the source file. `VIRUS_SCAN_ENABLED` defaults to false, so uploads are not scanned unless you ask. The backend port is published as `"${BACKEND_PORT:-8000}:8000"` with no loopback prefix, so it binds on every interface, while `CORS_ORIGINS` does default to localhost and 127.0.0.1 on the frontend port. Concurrency is tuned conservatively, with `JOB_CONCURRENCY` at 3 and the batch page, NER and visual feature concurrency values all at 1, and `VISION_DUAL_PIPELINE_PARALLEL` false. Two deployment shapes are offered in the header comment: a CPU-only API and frontend with `docker compose up -d`, and the full GPU model stack with `docker compose --profile gpu up -d`.
Uncommenting three lines breaks local Windows development
The env template documents a specific trap in its own comments. The `DATA_DIR`, `UPLOAD_DIR` and `OUTPUT_DIR` lines are commented out, with a note that they are only needed for Docker because compose already sets the same values, and that on local Windows development you must not uncomment them, because `/app/data` would otherwise be parsed as a drive root. When the three are unset the backend falls back to in-project directories, so the default is safe and the documented helpful action breaks it. The same block carries an application name that is commented out and reads DataShield Redaction Infrastructure, a different product name from the one the project is published under. The template also flags that service endpoints come in two flavours, Docker internal hostnames for containers and 127.0.0.1 addresses for local runs without Docker.
The path without Docker is WSL, two venvs and a serving model runtime
The local development profile starts six things: the frontend, the backend, PaddleOCR-VL, PP-StructureV3, HaS Text and LocateAnything. To do that it needs a WSL virtual environment at `VENV_DIR`, shown as `/home/YOUR_USER/.cache/datainfra-redaction/.venv`, described as the environment running PP-StructureV3 and the OCR wrapper at `scripts/ocr_server.py`, plus a second WSL environment with vLLM installed to serve HaS Text. The comments state that these values are required when the dev command starts and that a missing one produces a configuration error rather than a fallback. So the Docker-free route is not the lightweight one; it presumes WSL, two prepared environments and a model server. The root manifest reflects that split by doing almost nothing itself: three scripts, no dependencies, and an engines constraint of `>=24 <25`, which admits Node 24 and nothing else.
Entity values are mapped back to glyphs so nearby labels survive the mask
The hardest technical claim is in the OCR row of the feature table. Images and scanned documents are converted into text blocks by PP-StructureV3 running on PP-OCRv6 engines, with an optional PaddleOCR-VL supplement, and then HaS Text performs the semantic recognition and maps the recognised values back to glyph-exact coordinates, so a label such as the Chinese characters for account name stay outside the mask. That is the difference between redacting a field and blacking out a whole line, and it is the part of the pipeline that matters most for a bilingual form. Two recovery passes sit alongside it. A red-ink suppression pass whitens seal ink and re-detects, recovering print the stamp was hiding, with party names under a company seal named as the case. A local OpenCV detector supplements LocateAnything on red binding and edge seals and is deduplicated against the seal boxes already found.
Regex is demoted to a fallback and two visual services became one
Text recognition runs through HaS Text semantic NER by default, straight from configured NER tags and without relying on built-in exhaustive rule mappings, and regex survives only as a user-defined fallback. Custom text and visual items are supported with exact tags and no family collapse, so a schema can name one label rather than a class of labels. On the visual side a single LocateAnything-3B service grounds the fixed presets, which include faces, fingerprints, IDs, bank cards, seals, screens, QR codes and barcodes, signatures, and any user-defined visual label. The env template records that this service replaced the older separate visual-region and checklist services and is now the only visual model entry point, which is a consolidation rather than an addition. The default text runtime is vLLM, at `HAS_TEXT_RUNTIME:-vllm`, serving a model named `HaS_Text_0209_0.6B`, so the text path is a served 0.6B model rather than an in-process classifier.
The positioning section names its own baseline and the hardware it needs
The README compares itself to OpenAI Privacy Filter and calls that project a valuable high-throughput baseline for token-level PII detection in text, then states the difference is scope rather than rhetoric. The claimed layer is messy Chinese and bilingual business documents, scanned PDFs, Word contracts, images, visual privacy regions, human review, batch delivery and local deployment, against the argument that production files include layout, OCR noise, tables, stamps, signatures, screenshots, photos and scanned pages. General schemas cover people, organisations, contact details, credentials, accounts, financial values, dates, addresses and identifiers, with legal, finance and healthcare presets on top. The hardware requirement is stated in the same spirit: an NVIDIA GPU, with 16 GB of VRAM recommended for the full vision pipeline. The CUDA line begins to describe a matching version and then stops.
Editorial conclusion
It fits an individual doing their own redaction on documents they are allowed to process, with a GPU workstation and patience for a six-service local stack. It does not fit a company, a vendor delivering this to clients, or anyone expecting an open source licence, because the licence itself reserves paid work, teams, institutions, hosted services and production deployments, and because the LocateAnything-3B weights carry an NVIDIA non-commercial term that a commercial licence from the author does not clear. Before anything else, read the LICENSE file and the component table it points to, then set a real JWT secret and turn on upload scanning, because both default the wrong way.
Frequently asked questions
Is RedactionEverything open source?
No. It uses a custom Personal Use License that is free for personal, non-commercial use and requires a separate commercial licence for paid work, companies, institutions, teams, hosted services and production deployments. The repository's licence field asserts nothing.
Can RedactionEverything be used commercially?
Not out of the box. The licence requires a separate commercial agreement, and the README also states that the LocateAnything-3B weights carry an NVIDIA non-commercial licence and that PyMuPDF is AGPL-3.0, dual licensed commercially by Artifex. A commercial licence has to be agreed separately.
What happens with the default docker compose settings?
AUTH_ENABLED defaults to true while JWT_SECRET_KEY defaults to empty, VIRUS_SCAN_ENABLED defaults to false, and the backend port is published as 8000:8000 with no loopback prefix. CORS_ORIGINS does default to localhost and 127.0.0.1 on the frontend port.
What hardware does RedactionEverything need?
An NVIDIA GPU, with 16 GB of VRAM recommended for the full vision pipeline. The recommendation table also names Node.js 24 LTS and Python 3.11, and the root manifest constrains engines to node >=24 <25.
How does RedactionEverything run without Docker?
Through npm run dev, which starts the frontend, backend, PaddleOCR-VL, PP-StructureV3, HaS Text and LocateAnything. It requires WSL and a venv at VENV_DIR plus a second environment with vLLM, and a missing value fails with a configuration error.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ttttccxxui-datainfra-redactioneverything)Star history chart for your README
[](https://hysenlabs.com/projects/ttttccxxui-datainfra-redactioneverything)Was this useful?