Orbit's installer deletes older Stan installs by comparing version strings
A Python package for Bayesian forecasting with object-oriented design and probabilistic models under the hood.
At a glance
- What is it?
- uber/orbit is a Bayesian time series package that compiles Stan models at install time, so a forecasting library depends on a probabilistic programming toolchain, a deep learning framework and a set of compiled binaries. Its installer walks your Stan directory and removes what it judges to be older.
- Who is it for?
- This suits a forecasting team that wants posterior intervals from a familiar fit-predict interface rather than a sampling loop of its own, and who already has a Stan toolchain available. Three things to know before installing.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 175 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
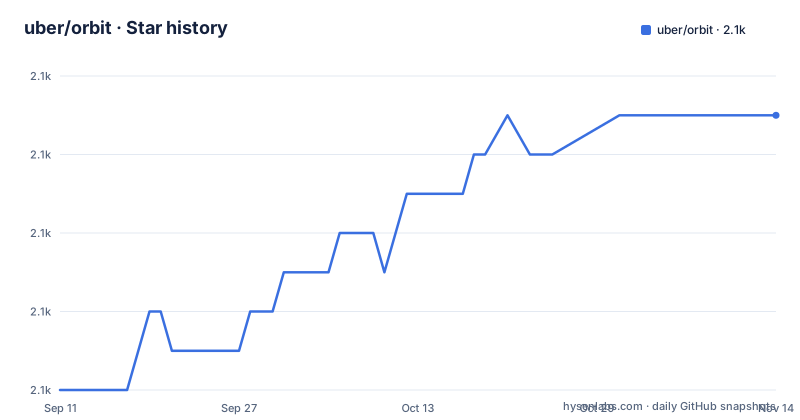
- uber/orbit2,083 ★ · +7
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| uber/orbit | 2.1k | 2.1k |
7 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The default branch is the development one and the badge points at the other
The repository opens with a user notice saying the default page is on the development branch, and that anyone wanting a stable version should look at the other branch. That is an unusual default for a package with a stable release line, and the file is honest about the consequence: installing from what you see when you land on the repository gives you development code. The split shows up elsewhere too. The licence badge links to the other branch, the documentation is published in two versions with one marked stable, and the installation section has a separate command for the development branch that installs straight from the branch reference rather than from an index:
pip install git+https://github.com/uber/orbit.git@devThe release history has its own small inconsistency: two tags are written with a plain version prefix and an older one puts a dot after it, and the version numbers themselves have four components.
The installer walks your home directory and removes what it thinks is old
The build script contains a function whose job is to tidy your Stan installations. It looks in the default Stan directory under your home folder, and for every entry whose name starts with the expected prefix it extracts the version portion, compares it with the version pinned in the project's own configuration file, and if the extracted string is considered smaller it deletes that directory recursively, printing a confirmation when it succeeds. The comparison is a plain string comparison, not a version comparison, which is where it becomes interesting: two-component versions compare correctly only sometimes, so a version that reads as larger numerically can be judged smaller as text. The code catches filesystem errors, so it will not delete something it cannot remove, but nothing asks it to be sure before it starts.
The container is built on an interpreter the package does not support
The package manifest requires Python 3.12 or newer and its classifiers name two versions, 3.12 and 3.13. The container definition starts from an image carrying Python 3.9. The two cannot both be right, and the container is the one you would run without noticing, because an image pins its own interpreter regardless of what the metadata says. The rest of that file compounds the gap. It installs the loose requirements file first, which pins far less than the manifest does and adds one interactive-widget library the manifest omits, then installs the test requirements, then installs the package itself in editable mode with verbose output. So the image's dependency set is not the one the manifest declares.
A forecasting package that requires torch, Stan and a sampling library
The runtime dependency list has twelve entries and three of them explain what this package is. A deep learning framework at a floor version is required rather than optional, which is a heavy floor for time series work. A probabilistic programming library is required at a floor version, and the disclaimer above the installation section names the Stan interface package as one of the core dependencies for Bayesian sampling. An inference and diagnostics library, plus a classical statistics package, a plotting pair and a numerical library with a lower bound, complete the set. The same Stan interface package appears again in the build requirements, so it is needed to build the package as well as to run it. That is a substantial toolchain for what the page describes as an intuitive initialise, fit and predict interface.
Four models, three estimation strategies, four compiled programs
The model list has four concrete implementations: exponential smoothing, a local global trend, a damped local trend, and kernel time-based regression. The estimation list has three strategies with distinct meanings, one that samples the full posterior, one that produces a point estimate by maximisation, and one that treats the posterior as an approximation. The connection between the two lists is in the build script: it declares a source directory of Stan models and a list of four model targets to compile, and separately lists the four command-line programs it expects the Stan toolchain to have provided. So the estimation strategies are not a backend you install later. They are chosen by which compiled model and which binary are present, which means the model and the inference strategy are coupled at build time.
The two headline demos live in somebody else's repository
The demo section links two notebooks that show nowcasting with regression and a backtest on a standard forecasting data set. Both links point into a different account's repository, not this one, and both are hosted notebooks rather than files here. The repository does carry its own material: a tutorials directory inside the documentation, and an examples directory with several notebooks including an exploratory analysis one, a daily forecast one, a simulation one, a backtest animation and an archive folder. The presentation section is a third pattern, with the project scope and roadmap living in an online slide deck and an older deck from a summer meet-up preserved beside it. Both are outside version control.
Version bookkeeping is spread across four files
The version number lives in the manifest as a four-component value, which matches the newest tag and is unusual enough to be worth noting. Everything else about releases is elsewhere. A release document sits at the repository root, the change log is inside the documentation tree rather than beside the manifest, and there is a separate test requirements file plus a task-runner configuration for running the suite across environments. The build configuration also pins a formatter with a line length and two target interpreter versions, and includes an example of an exclusion rule written as a regex in a comment, which is a small sign of how much iteration the file has accumulated. None of it is documented on the page, so the release process is reconstructable only by reading four files.
The licence is stated three ways and the citation is six years old
The licence appears in three forms and they do not agree. The project's licence metadata records nothing recognisable, the manifest declares the Apache licence by text, and a licence file sits at the repository root. For a package distributed through both an index and a conda channel, the metadata gap is the one that propagates furthest, because that is what tooling reads. The citation section points at a preprint from 2020 for a paper on probabilistic forecasting with exponential smoothing, gives the full author list and includes a Bibtex block in the page. The reference list underneath is four papers: the universal probabilistic programming library the package depends on, the sampler paper, the state-space exponential smoothing textbook, and a conference paper on fitting exponential smoothing models with Stan.
Editorial conclusion
This suits a forecasting team that wants posterior intervals from a familiar fit-predict interface rather than a sampling loop of its own, and who already has a Stan toolchain available. Three things to know before installing. The install step compiles Stan models and may remove existing Stan versions from your home directory based on a string comparison of version numbers, so read that script before letting it run on a machine with a toolchain you care about. The container definition is built on an older interpreter than the package declares support for. And the default branch is the development one, so the version you get depends on which branch you install from.
Frequently asked questions
What is uber/orbit?
It is a Python package for Bayesian time series forecasting and inference that presents an initialise, fit and predict interface while using probabilistic programming languages underneath. Its four concrete models are exponential smoothing, local global trend, damped local trend and kernel time-based regression, and it offers three estimation strategies: full posterior sampling, a point estimate by maximisation, and an approximate-distribution hybrid.
What do I need before installing Orbit?
Python 3.12 or newer, and the Stan interface package, which the documentation calls one of the core dependencies for Bayesian sampling and which is also listed among the build requirements. Twelve runtime dependencies are declared, including a deep learning framework at a minimum version and a probabilistic programming library at a minimum version, so the toolchain is larger than a classical forecasting package would need.
Which Orbit branch should I use?
The repository opens by stating that its default page is the development branch and that a stable version lives on the other branch. The manifest itself requires Python 3.12 or newer, and there is a separate install command that installs straight from the development branch reference rather than from a package index.
Does installing Orbit compile anything?
Yes. The build script declares a directory of Stan model sources and four model targets to build, and expects four command-line programs from the Stan toolchain to be present. It also contains a function that looks through your Stan directory under your home folder and removes any entry whose extracted version string compares smaller than the pinned one, using a plain string comparison rather than a version comparison.
How do I cite Orbit?
With the paper on probabilistic forecasting with exponential smoothing, first posted as a preprint in 2020, which the page lists with its full author list and a Bibtex entry. The reference list also includes the paper for the universal probabilistic programming library the package depends on, the adaptive path-length sampler paper, the state-space approach to exponential smoothing, and a conference paper on fitting and extending exponential smoothing models with Stan.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uber-orbit)Star history chart for your README
[](https://hysenlabs.com/projects/uber-orbit)Was this useful?