PolyglotPiranha only supports its owner's languages, and its grammars are patched forks
A tool for refactoring code related to feature flag APIs
At a glance
- What is it?
- A structural find-and-replace tool for cleaning up feature flags after an experiment has shipped, built as a Rust workspace with Python bindings and a vendored set of patched grammar repositories. The example on the page stops before the call it advertises, points at a directory that no longer exists, and the documentation carries a timestamp from 2022.
- Who is it for?
- PolyglotPiranha fits a team sitting on a large codebase where feature flags outlive their experiments and the cleanup is being done by hand, because that is exactly the workload it was built for and the one it is documented against. Three things to know before you plan a cleanup run.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 25 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
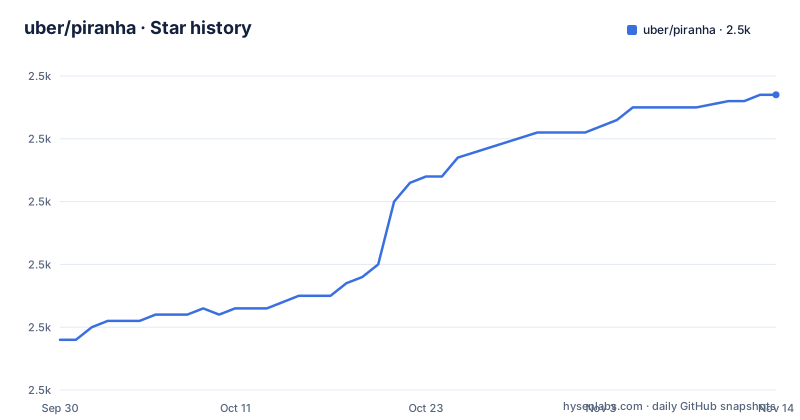
- uber/piranha2,527 ★ · +39
| Repository | 2026-09-30 | 2026-11-14 |
|---|---|---|
| uber/piranha | 2.5k | 2.5k |
39 Stars in the last 45 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The scope limit is stated before the feature list
The second paragraph of the readme is the most useful thing on the page.
We only support languages that are used at Uber.The sentence continues by saying new languages are unlikely to be added in this repository, and pointing at a list of forks that may provide more. That is an unusual thing to lead with, because most tools of this kind present universality and let the gaps show later. Here the boundary is the first thing a reader learns: this is a tool that grew out of one very large codebase, its grammar work is funded by one company's needs, and the extension path is forking rather than opening a pull request. A team evaluating it for a language that is not in the list has been told the answer up front, and can go and look at the forks instead of filing an issue. The tool's stated purpose is narrow too: at its owner it is mostly used to clean up stale feature flags.
The example imports the entry point and then never calls it
The usage example is the page's centrepiece and it stops one line early.
r1 = Rule(
    name="replace_method",
    query="cs :[x].isLocEnabled()", # cs indicates we are using concrete syntax
    replace_node="*",
    replace="true",
    is_seed_rule=True
)
The import line above it brings in the execute function, the arguments object, the rule type, the rule graph type and the edge type. The snippet then defines one rule, adds a comment noting that a boolean cleanup rule is already defined for one language elsewhere in the tree, and the code block ends. The function that was imported is never called, so the reader learns what a rule looks like but not how a rule is run. The query syntax does teach something useful in passing: the prefix before the pattern selects a matching mode, and this one is for concrete syntax rather than something semantic, which is the kind of distinction you only understand once you see it flagged in an example.
The example points at a directory the repository no longer has
That same trailing comment is where the paths go stale.
[see src/cleanup_rules]The repository has no top level source directory. The Rust workspace declares two members, a core crate and a crate for concrete syntax, and everything else sits beside them: a plugins directory, a playground directory, a demos directory, a tests directory, and a build script at the root. So the example is referring to a layout the project had before it moved its code into a workspace of crates, and the reference has not been updated. For a tool whose entire job is rewriting source code across languages, an example that points at the wrong place is more than cosmetic: it is a reader being sent to look for predefined cleanup rules and finding nothing. The deeper documentation is split across an extended readme file and the demos directory, so the fix is available elsewhere on the page, just not where the example is.
The grammars are forks, and the patches are not upstream yet
This is the fact that decides whether the tool works in your repository, and it is in the development section rather than the introduction.
Piranha uses several grammar repositories with custom patchesThe paragraph says the patches are being upstreamed and that until they are, the grammars in this repository may differ from the upstream ones. So the tool does not parse with stock parsers; it parses with local modifications of several grammar repositories, maintained in the same tree, and it expects those modifications. That is a real maintenance burden to inherit and it is not hidden, but it does mean a version skew between the tool and the grammar projects it was written against is possible. The response to that is a custom playground for the grammars, hosted as pages under the same organisation, for testing grammars and queries interactively. That is the right investment to make and its existence is a good sign about how the maintainers think about the problem.
The multi-language claim is stamped as of May 2022
One sentence carries a date that is four years old and reads as current.
PolyglotPiranha (as of May 2022) is a common refactoring tool to support multiple languagesThe same paragraph then points at a tag holding the legacy language specific implementations, which is the correct place to look if you want the older per-language tools, and it is also a sign that the project has reorganised itself once already. Anyone reading the page quickly will take the sentence as a current claim rather than a dated one, and the date is the only thing that tells you the claim was true when it was written. The release history gives a second signal: a patch in early October 2025, another three days later, then nothing until a patch in April 2026 whose tag carries the name of this release and whose timestamp is the same minute as the last recorded commit on the branch.
Two distributions, and the default build does not work on macOS
Installation comes in two shapes and each has a wrinkle.
pip install polyglot-piranhaThe package index route gives you the Python library, and its manifest requires an interpreter from 3.8 upwards and declares the bindings as a compiled extension built from the core crate, bundling the licence, the notice and a type stub file so editors get types. The command line route is a build from source, and the build line in the readme comes with a parenthetical: the default feature set does not build on macOS, so there is a flag to opt out of it. That is worth knowing before you start, because the failure is at compile time and the flag is easy to miss in a numbered list. The two distributions share a name with a hyphen on the index and an underscore on the import, which is the packaging system's doing and costs nothing.
Every demonstration exists twice, once directly and once through Python
The demos directory is the most maintained part of the repository and its structure is the interesting thing. The pattern is consistent: stale flag cleanup, feature flag cleanup, plain find and replace, a custom cleanup variant, and a match only variant, each of which appears as a direct demonstration and again as one that goes through the Python interface, plus a separate demonstration for a different interface definition language. So the library is exercised twice for every capability, which is a cheap and effective way to keep the bindings honest. The rest of the root is a similar story of things the project maintains around the core: a script for visualising the rule graph as an image, a template file holding the licence header that source files are expected to carry, a formatter configuration, a pre-commit configuration, a release process document, and the technical report as a committed document rather than a link.
Editorial conclusion
PolyglotPiranha fits a team sitting on a large codebase where feature flags outlive their experiments and the cleanup is being done by hand, because that is exactly the workload it was built for and the one it is documented against. Three things to know before you plan a cleanup run. The language list is closed by design, and the extension path is a fork rather than a pull request, so check your language first. The parsing depends on locally patched grammar repositories whose patches have not landed upstream, which means you inherit that skew. And the documentation carries a 2022 timestamp, an example that stops before showing the call it imports, and a path reference left over from a layout the project has since restructured, so plan to read the demos rather than the page.
Frequently asked questions
What does PolyglotPiranha actually do?
It performs structural find and replace with deep cleanup. Given a flag name, the behaviour you expect, and a properties file listing the flag related APIs, it rewrites code so the flag is gone, together with the code that existed only to serve it.
Which languages does PolyglotPiranha support?
Only the languages used at Uber, and the readme says new languages are unlikely to be added in this repository. It points to a list of forks that may provide additional features, so extension happens through forking rather than through the main project.
How do I install PolyglotPiranha?
Either as a Python library from the package index, which needs an interpreter from 3.8 upwards, or as a command line tool built from source with a Rust toolchain. The source build carries a note that the default feature set does not build on macOS and needs a flag to opt out.
Does PolyglotPiranha use standard language parsers?
Not unmodified ones. It uses several grammar repositories with custom patches to support its transformations, and the readme says those patches are still being upstreamed, so the grammars in this repository may differ from the upstream ones. A custom playground is provided for testing the grammars and queries.
Why would I remove a feature flag's code?
Because the flag's purpose is often outlived by the code around it. The readme lists the consequences: clutter that raises maintenance cost, interference with other experiments when flags nest, unused code left in both the source and the built binary, and outright bugs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uber-piranha)Star history chart for your README
[](https://hysenlabs.com/projects/uber-piranha)Was this useful?