UltraJSON in maintenance-only mode: the C JSON codec that stopped taking features
Ultra fast JSON decoder and encoder written in C with Python bindings
At a glance
- What is it?
- ujson encodes and decodes JSON in C with Python bindings, and its own maintainers have frozen everything except new Python support and security fixes. What the four encoder options, the build variables and the benchmark gaps mean for anyone still shipping it.
- Who is it for?
- ujson still decodes JSON correctly, still ships new Python version support, and still takes security fixes, so an existing dependency is not an emergency. New work should assume there is no feature branch to send a request to: check how your data uses non-ASCII text, forward slashes and pretty printing before adopting it fresh, and if you compare it against orjson, run the numbers on your own payloads rather than trusting a table built from a development build.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
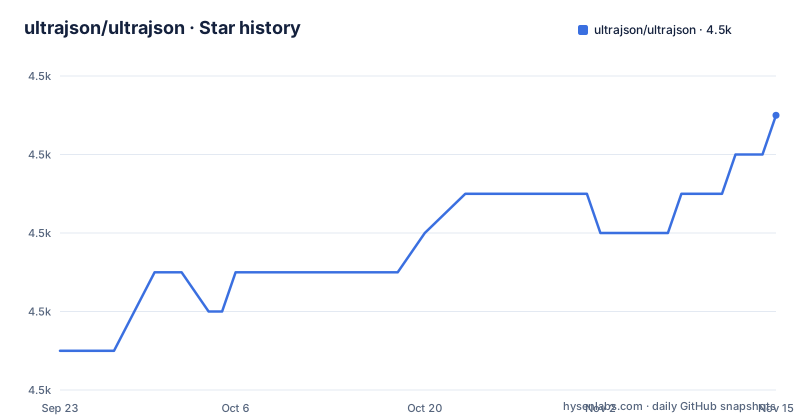
Star history
- ultrajson/ultrajson4,503 ★ · +6
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| ultrajson/ultrajson | 4.5k | 4.5k |
6 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The compiled extension, not the Python layer, is what pip installs
Installing ujson drops a compiled extension module into site-packages, so there is no Python file to open when a decode misbehaves. setup.py declares a single Extension named "ujson" and hands it the encoder and decoder C sources plus a double-conversion wrapper:
module1 = Extension(
    "ujson",
    sources=dconv_source_files
    + [
        "./src/ujson/ujson.c",
        "./src/ujson/encode.c",
        "./src/ujson/decode.c",
    ],
    include_dirs=["./src/ujson"] + dconv_includes,
    define_macros=[("UJSON_VERSION", f'"{version}"')],
    extra_compile_args=["-D_GNU_SOURCE"],
    extra_link_args=["-lstdc++", "-lm"] + dconv_libs + strip_flags,
)
Linking pulls in -lstdc++ and -lm, so a wheel build needs a C++ toolchain even though the project describes itself as pure C. The version number is not written into a source file either: setup.py calls get_version from setuptools_scm and passes the result in as the UJSON_VERSION macro, which is why pyproject.toml lists version under dynamic and requires setuptools-scm[simple]>=9.2 in the build system. The library ships typing information through a separate stub directory rather than inline annotations, and the repository root keeps the usual linting and test scaffolding (.flake8, tox.ini, .pre-commit-config.yaml, RELEASING.md, scripts/, tests/).
Three environment variables decide what gets compiled in
setup.py reads three environment variables before it builds anything, and they are the only knobs a distributor gets. UJSON_BUILD_DC_INCLUDES replaces the search path list for double-conversion headers, defaulting to the vendored copy at ./src/ujson/deps/double-conversion/double-conversion and split on the platform path separator. UJSON_BUILD_DC_LIBS, when set, skips the bundled double-conversion sources and links whatever libraries you name there instead, with the value run through shlex.split. The third one controls whether Linux binaries stay debuggable:
if platform.system() == "Linux" and environ.get("UJSON_BUILD_NO_STRIP", "0") not in (
    "1",
    "True",
):
    strip_flags = ["-Wl,--strip-all"]
else:
    strip_flags = []
Only the exact strings 1 and True switch stripping off. Anyone chasing a crash inside the decoder with a core dump will hit stripped symbols on Linux by default and need to rebuild with UJSON_BUILD_NO_STRIP=1 before a backtrace is worth reading. The same substitution trick that redirects double-conversion also applies to the whole dependency, so a distribution that links a system copy gets a different binary than one that compiles the vendored sources.
escape_forward_slashes rewrites every URL you encode
Four keyword arguments decide the exact bytes on the wire, and each one has a default that surprises somebody. escape_forward_slashes is True by default, so URLs come out with every slash escaped as \/, which is legal JSON and unfriendly to anything that pattern matches on raw text:
>>> ujson.dumps("https://example.com")
'"https:\\/\\/example.com"'
>>> ujson.dumps("https://example.com", escape_forward_slashes=False)
'"https://example.com"'
ensure_ascii is True as well, so every character above 127 is escaped unless you pass False, and the documentation recommends turning it off for any end format that speaks UTF-8. indent defaults to 0, which means no pretty output until you pass a number, and print around it if you want to see it. encode_html_chars defaults to False and, when enabled, rewrites angle brackets and ampersands as \u escapes instead of leaving them as raw characters. These are dump-time switches only, so a decoder never has to know which ones a producer used, but a consumer that compares hashes or signs the payload has to be configured identically on both ends.
Maintenance-only mode turns feature requests into rejections
The warning at the top of the project page is the single most consequential fact about ujson. It states that the architecture is fundamentally ill-suited to making changes without risking new security vulnerabilities, and puts the library into maintenance-only mode as a result. Support for new Python versions will still be added, critical bugs and security issues will still be fixed, and every other change will be rejected. The release dates line up with that narrow promise: 5.12.1 on 2026-05-05, 5.13.0 on 2026-06-14, and 6.0.0 on 2026-09-04, with the last push landing on 2026-11-01. The version range in the classifiers runs from Python 3.10 up to 3.15, so interpreter support is the part of the roadmap that is still moving. The README also recommends migrating to orjson, which it calls both faster and less likely to grow a surprise buffer overflow. For a reader, the practical meaning is that a bug you find which is neither critical nor security has nowhere to go, and a feature you want will never arrive.
Two benchmark rows leave the orjson column blank
The benchmark numbers were produced on one machine, Linux 5.15.0-1037-azure x86_64, against CPython 3.11.3 (main, Apr 6 2023, 07:55:46) [GCC 11.3.0], with ujson at 5.7.1.dev26, orjson at 3.9.0, simplejson at 3.19.1 and json at 2.0.9. Figures are calls per second, and larger is better.
| | ujson | orjson | simplejson | json | |-------------------------------------------------------------------------------|-----------:|-----------:|-----------:|-----------:| | Array with 256 doubles | | | | | | encode | 18,282 | 79,569 | 5,681 | 5,935 | | Array with 256 UTF-8 strings | | | | | | encode | 3,457 | 26,437 | 3,630 | 3,653 | | Dict with 256 arrays with 256 dict{string, int} pairs | | | | | | encode | 55 | 282 | 11 | 26 | | Complex object | | | | | | encode | 462 | | 397 | 444 |
Two things undercut this table. The ujson build measured is 5.7.1.dev26, a development snapshot rather than any of the numbered releases listed above, so the figures describe a tree that may not correspond to a version you can install. And the encode cells for the sorted-keys row and the complex object row have no orjson entry at all. Reading a missing cell as a loss would be convenient, and it is not what the table says.
Thread safe by construction, unsafe by caller mistake
The concurrency story rests on one property: ujson keeps no global state. Because of that, calling its functions from several threads is thread safe on its own and returns consistent results whether the interpreter holds the global interpreter lock or not. What is not supported is mutating an object in one thread while ujson is serialising that same object in another. In practice this means a dict shared between a request handler and a background writer is a caller bug: publish an immutable snapshot, or serialise outside the lock, or accept that a container can be mid-resize while the C code walks it. Sharing the module itself across threads costs nothing, and that is the case the project claims to handle.
Type stubs live in a hyphenated package directory
Typing support is a directory named ujson-stubs rather than a separate distribution, and pyproject.toml declares it in exactly one place: packages = [ "ujson-stubs" ]. The Typing :: Typed classifier says the same thing to tooling that reads metadata instead of source. Runtime metadata is otherwise plain: name ujson, license BSD-3-Clause AND TCL with LICENSE.txt as the licence file, author Jonas Tarnstrom, and requires-python set to >=3.10. The implementation list is broader than CPython alone, naming PyPy and GraalPy next to it. Test configuration is short as well: testpaths points at tests, minversion is 9.0, and one marker is registered, skip_leak_test, documented as not rerunning that test during a search for memory leaks.
Editorial conclusion
ujson still decodes JSON correctly, still ships new Python version support, and still takes security fixes, so an existing dependency is not an emergency. New work should assume there is no feature branch to send a request to: check how your data uses non-ASCII text, forward slashes and pretty printing before adopting it fresh, and if you compare it against orjson, run the numbers on your own payloads rather than trusting a table built from a development build.
Frequently asked questions
Is orjson faster than JSON?
In the table published with the project, yes: orjson records 79,569 calls per second encoding an array of 256 doubles against 5,935 for the standard library json module, and 26,437 against 3,653 for an array of 256 UTF-8 strings. ujson sits in between at 18,282 and 3,457. The figures come from a development build of ujson on one Linux machine running CPython 3.11.3, and two rows leave the orjson column empty.
What is ujson?
ujson is a JSON encoder and decoder written in pure C with bindings for Python, installed with python -m pip install ujson. It is presented as a drop in replacement for most other JSON parsers, offering dumps and loads plus four encoder options: encode_html_chars, ensure_ascii, escape_forward_slashes and indent.
Is ujson still accepting feature work?
No. The project is in maintenance-only mode: new Python versions are still supported and critical bugs and security issues are still fixed, but all other changes are rejected. The maintainers point users at orjson as the migration target.
Can I change ujson encoder output defaults without touching call sites?
Not from the configuration side, since these are keyword arguments on dumps with no global settings file. The defaults are ensure_ascii=True, escape_forward_slashes=True, encode_html_chars=False and indent=0, and each is passed per call.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ultrajson-ultrajson)Star history chart for your README
[](https://hysenlabs.com/projects/ultrajson-ultrajson)Was this useful?