Darts: one fit() and predict() API across ARIMA, N-BEATS and PyOD scorers
A python library for user-friendly forecasting and anomaly detection on time series.
At a glance
- What is it?
- Darts wraps statistical and deep forecasting models behind a scikit-learn shaped interface, and it separates anomaly scoring from anomaly decisioning so you can swap either half. The costs are a wide required dependency set and a hard Python 3.11 floor.
- Who is it for?
- Use Darts when you want one interface across classical and neural forecasters, need multivariate or multi-series training, and want anomaly detection assembled from parts you can see. Do not adopt it for a single ARIMA fit in a slim environment, since sixteen required packages including pyod, shap and statsmodels, plus numba and llvmlite, come with it, and note that Python 3.10 and older are out of reach.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
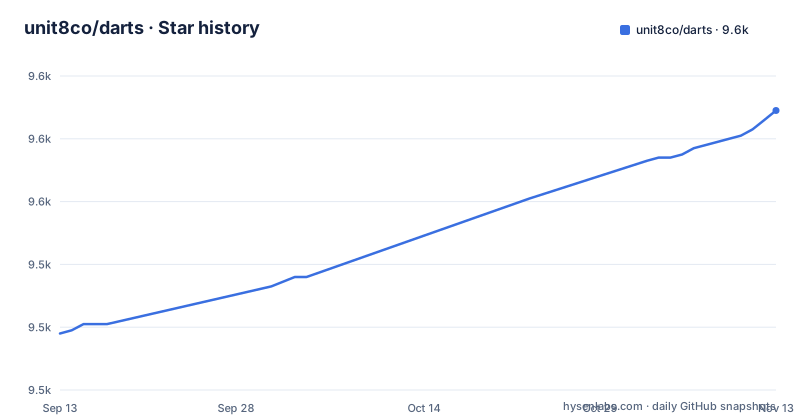
- unit8co/darts9,589 ★ · +71
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| unit8co/darts | 9.5k | 9.6k |
71 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every model takes fit() and predict(), which is the compatibility story
The design decision that defines this library is uniformity. The forecasting models all work the same way, through fit() and predict() functions, similar to scikit-learn, whether you pick a statistical model such as ARIMA or a deep network such as N-BEATS. The example makes that concrete:
from darts.models import ExponentialSmoothing

model = ExponentialSmoothing()
model.fit(train)
prediction = model.predict(len(val), num_samples=1000)
Because the call shape is fixed, switching families is a constructor change rather than a rewrite of your pipeline, and the library adds backtesting, combining predictions from several models, and accounting for external data on top of that. Both univariate and multivariate series are supported, and every machine learning model including the neural ones can be trained on multiple series, which is what the project calls global models. What uniformity does not buy you is identical hyperparameters: the same two methods still hide very different configuration behind each constructor.
Probabilistic output is a sample count you pass, not an interval flag
Uncertainty is handled by drawing samples rather than by asking for a confidence band. The prediction call in the example takes a num_samples argument, here 1000, and the plot call then chooses which quantiles to draw:
prediction.plot(label="forecast", low_quantile=0.05, high_quantile=0.95)A TimeSeries object can optionally represent a stochastic series, and that representation is what carries those samples, which is how a model that supports probabilistic forecasting reports confidence. Two consequences follow. First, the interval you show is your choice of quantiles rather than a default the library picked for you, so a 5 to 95 band and a 2 to 98 band come from the same prediction object with different arguments. Second, sampling count is a real parameter with a real cost, and the README notes only that some models offer rich support for probabilistic forecasting, so the coverage differs by model family.
Anomaly detection is a scorer and a detector fitted on different things
The anomaly module is assembled from parts rather than used as one object, and the split is the part worth internalizing. A scorer produces scores, a detector turns scores into decisions, and aggregators combine them:
from darts.ad import KMeansScorer

scorer = KMeansScorer(k=2, window=5)
scorer.fit(train)
anom_score = scorer.score(val)

from darts.ad import QuantileDetector

detector = QuantileDetector(high_quantile=0.99)
detector.fit(scorer.score(train))
binary_anom = detector.detect(anom_score)
Read the sequence carefully: the detector is fitted on scores computed over the training set, then applied to scores from the validation set. It never sees raw data. That means the threshold you get is a quantile of your own score distribution, so a high_quantile of 0.99 is a decision you are making, and a badly behaved scorer produces confident nonsense rather than an error. The same composability works in the other direction, since any forecasting or filtering model can be wrapped into a detector that compares predictions against actuals, and PyODScorer brings PyOD detectors to time series data.
Python 3.11 is the floor, and Intel Macs pin numba below 0.63
The packaging metadata requires Python 3.11 or newer and the classifiers name 3.11, 3.12, 3.13 and PyPy. Nothing below 3.11 is supported, which is worth checking before anything else if your environment is older. The more interesting part is in the dependency markers. numba and llvmlite carry two entries each: an upper bound of numba<0.63 and llvmlite<0.46 when the platform is macOS on x86_64, and the unbounded version otherwise. The comment explains why, since numba 0.63 dropped macOS x86_64 wheels, tracked upstream as numba/numba#10187. So on an Intel Mac your resolver pins two packages below their latest releases while on Apple silicon or Linux it takes the current ones. That is a deliberate compatibility shim, not a pin you can lift, and it means the same environment file resolves differently depending on the machine that installs it.
Fifteen required runtime packages, including pyod and shap
One dependency line in the front page hides a wide floor. The required set is holidays, joblib, matplotlib, narwhals, nfoursid, numpy, pandas, pyod, requests, scikit-learn, scipy, shap, statsmodels, tqdm, typing-extensions and xarray, each with a lower bound. Two of those deserve attention. pyod is a hard requirement even though the anomaly scorers built on it are optional in spirit, since PyODScorer is one choice among the scorers in darts.ad. shap is required too, which is a heavier commitment than a forecasting-only user would expect. The flip side is that the upper halves of the scientific stack arrive together, so numpy, pandas, scipy, scikit-learn and statsmodels are all present whether you use them or not. For anyone with a locked environment or a slim container, read this list before installing rather than after.
The container installs dev-all on purpose, so the image is bigger than the library
The Dockerfile is explicit about wanting the full environment. It starts from python:3.13-slim, copies the uv binary from a pinned image tag, ghcr.io/astral-sh/uv:0.11.7, and copies only the darts/ directory plus pyproject.toml and README.md, which is the minimum needed to install. The install step is a single line, and the comment above it explains the choice:
RUN uv sync --group dev-allThe note says that no-dev would install only core dependencies, and that dev-all is wanted for the full environment. So the image ships the development dependency groups, then copies examples/ in and puts the virtual environment on PATH. The build and run instructions are in the same file, including a Jupyter path that exposes port 8888 and runs jupyter lab against 0.0.0.0. Useful for the notebooks, and wrong for production, where you would want the core set.
INSTALL.md holds the real install matrix, and release titles say minor or patch
The quick install is deliberately thin, and it defers. A clean environment with Python 3.11 or newer is recommended using conda, venv or virtualenv, with or without virtualenvwrapper, and then one command:
pip install dartsAnything more specific is pointed at INSTALL.md in the repository. The rest of the repository explains how serious the packaging is: make_dists.sh for building distributions, CITATION.cff for citation metadata, a CHANGELOG.md, a Dockerfile and a .coveragerc. The release titles carry their own intent, with 0.48.1 published as Darts patch 0.48.1 on 2026-10-16 and 0.48.0 as Darts minor 0.48.0 on 2026-10-15, so you can tell at a glance whether a release added surface or fixed something. The examples directory is numbered from 00 through 24, and the sequence doubles as a reading order, ending with anomaly detection, conformal prediction and a scikit-learn classifier model.
Editorial conclusion
Use Darts when you want one interface across classical and neural forecasters, need multivariate or multi-series training, and want anomaly detection assembled from parts you can see. Do not adopt it for a single ARIMA fit in a slim environment, since sixteen required packages including pyod, shap and statsmodels, plus numba and llvmlite, come with it, and note that Python 3.10 and older are out of reach. Before you start, read INSTALL.md rather than the one-line pip command, and if you are on an Intel Mac, check the numba and llvmlite caps, which exist because numba 0.63 dropped macOS x86_64 wheels.
Frequently asked questions
How do you install Darts for Python?
Set up a clean Python 3.11 or newer environment first, using conda, venv or virtualenv, then run pip install darts. The README points to INSTALL.md for the detailed installation instructions.
How do I set up a first Darts forecasting run?
Read a pandas DataFrame into a TimeSeries with TimeSeries.from_dataframe(df, "Month", "#Passengers"), split it with series[:-36] and series[-36:], fit ExponentialSmoothing on the train part, then call model.predict(len(val), num_samples=1000) and plot with low_quantile and high_quantile.
How does anomaly detection work in Darts?
The darts.ad module holds scorers, detectors and aggregators that combine. The example fits KMeansScorer(k=2, window=5) on the training series, scores the validation series, then fits QuantileDetector(high_quantile=0.99) on the training scores and applies detect() to the validation scores to get a binary anomaly signal.
Which Python versions does Darts support?
The packaging metadata requires Python 3.11 or newer, with classifiers for 3.11, 3.12, 3.13 and PyPy. On macOS x86_64 it also pins numba below 0.63 and llvmlite below 0.46, because numba 0.63 dropped macOS x86_64 wheels.
Can I combine several Darts models in one forecast?
The library states it makes it easy to backtest models, combine the predictions of several models, and take external data into account. The numbered example notebooks cover ensembling, hierarchical forecast reconciliation, transfer learning and hyperparameter optimization.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/unit8co-darts)Star history chart for your README
[](https://hysenlabs.com/projects/unit8co-darts)Was this useful?