recon-skills: a markdown pack that ships its own quality gate
Recon & pentest skill pack. CORS, XSS, SQLi, SSRF, RCE, WordPress, MCP, cloud, subdomain takeover, and more. Field-tested. MIT. Full write-up at hiago.sh
At a glance
- What is it?
- recon-skills is a curated set of documents for authorized external security testing, organised into six directories and found with a filesystem search rather than loaded by a runtime. Its most interesting parts are procedural: a fixed structure for every skill, a validator that separates structural errors from style warnings, and a rule that validation material is added only after discovery produces a signal.
- Who is it for?
- recon-skills suits someone who already knows external web security testing and wants a documented procedure with stated prerequisites and stated verification criteria, rather than a tool that runs and reports. Three things to note.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
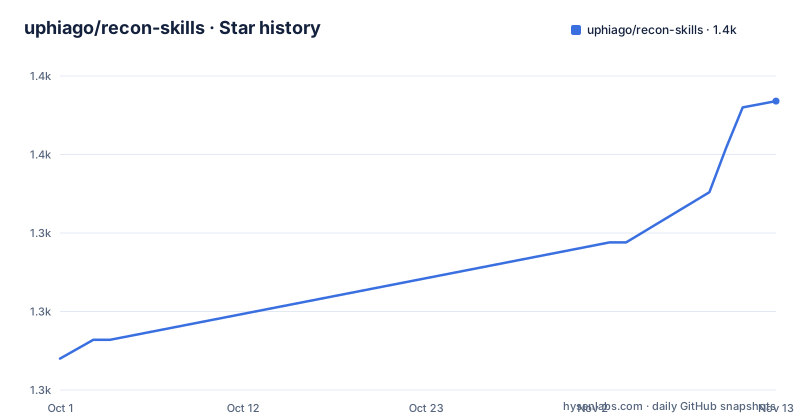
- uphiago/recon-skills1,367 ★ · +82
| Repository | 2026-10-01 | 2026-11-13 |
|---|---|---|
| uphiago/recon-skills | 1.3k | 1.4k |
82 Stars in the last 43 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The pack is markdown found with a filesystem search
There is no runtime here. The whole pack is a set of documents with a naming convention, and the documented way to navigate it uses standard tools:
git clone https://github.com/uphiago/recon-skills.git
cd recon-skills

find . -name SKILL.md -print | sort
rg -n "SSRF|OAuth|GraphQL|Kubernetes" --glob 'SKILL.md'
One search lists every skill. The other greps across all of them at once for a technique, which is the useful direction: you find out which procedures already cover the thing you are looking at before writing your own.
The catalogue is six directories, and the tree in the README states the purpose of each: authentication and single sign-on testing, multi-step attack-path analysis, infrastructure-focused techniques, engagement planning and cross-skill workflows, discovery and enumeration, and vulnerability-class and platform playbooks.
The last line says skills can be followed by hand or loaded as task context by an automation system. That second option is what connects this to the wider skills ecosystem, and it has a consequence worth stating: the files have to be legible as instructions to a reader who is not a human. That is why every skill carries the same set of headings, which is the next thing worth looking at.
The commands shown are organisational only. Nothing in the pack's own documentation runs an exploit.
Every skill has to state its own verification criteria
The README describes what each skill file must contain, and the fifth item is unusual for this kind of pack.
Each skill owns a focused objective, and documents five things: the prerequisites, the procedure, the pitfalls, the verification criteria, and the related techniques for that objective.
Four of those are conventional. Verification criteria are not. They mean a skill does not stop at telling you how to check something; it has to state what a correct result looks like before you accept it.
That matters because most of the failure in this kind of work is a false positive. A scanner that reports a finding has not established one. A skill that specifies the evidence required turns an output into something a reviewer can check, which is exactly what a report needs and what an automation system needs before it escalates something to a person.
Two related entries in the high-signal list reinforce the point. One is for finding validation before reporting, and one is for evidence capture that is reproducible and redacted. Both are about the stage after discovery, which is the stage most skill packs skip.
So the pack's structure has an opinion about where the hard part is. Discovery is treated as the automatable part, and confirmation and reporting as the part that needs a written standard.
The validator fails on structure and only warns on style
There is one command to run before reviewing a change:
python3 scripts/validate_skills.pyAnd the behaviour of that command is split in two on purpose. Structural errors fail it. Existing style debt is reported separately as warnings, so it can be improved incrementally.
That split is the engineering decision in this repository. A stricter design would fail on everything and force a single large cleanup before anyone could contribute. This one lets the repository raise its bar without stopping work, and the README is explicit that older skills are being migrated to the complete baseline gradually.
The consequence for a reader is that the pack is internally uneven by design. A skill written last week and one written a year ago will not look the same, and the older one may be missing headings the newer ones have. That is a fair trade for an active catalogue, and it is also the thing to check for yourself before relying on any single skill.
The baseline itself is not in the README. It lives in a file called STYLE.md, and the contributor rules in another called AGENTS.md, which is where you would go to find out what a complete skill actually looks like.
The sequencing rule is to add validation material only after a signal
The usage section gives four named entry points for a broad external web assessment and then attaches a condition to going further.
The entry points are a broad web attack-surface skill, subdomain enumeration, web enumeration, and a bug bounty methodology skill. Then: add vulnerability or platform skills only when discovery produces a relevant signal.
That is a scope discipline expressed as a workflow. The pack assumes a person or an agent will work through discovery first and then choose, rather than loading the whole catalogue and hoping.
It also shapes what the repository is for. The description lists vulnerability classes, including cross-origin policy, cross-site scripting, SQL injection, server-side request forgery, remote code execution, WordPress, model context protocol servers, cloud targets and subdomain takeover. Those are the subjects covered somewhere in the six directories. None of them is an entry point.
For an automation system, the same rule is the interesting part, because it is a gate rather than a filter. You cannot ask the pack which vulnerability skills to load for a target. You run discovery, look at what came back, and then ask. That is a design that resists firing every technique at every host, which is both an operational virtue and a legal one.
Twelve entry points, and three of them are about writing things down
The high-signal table names twelve skills and gives each a one-line purpose. Grouped by directory, they cover: an end-to-end recon workflow with escalation gates, bug bounty methodology and prioritisation, broad web attack-surface discovery, external intelligence and asset pivots, passive and active subdomain discovery, port and service classification, web path and technology enumeration, client-side bundle and secret analysis, evidence-based attack-path construction, finding validation before reporting, reproducible and redacted evidence capture, and client and bug bounty reporting.
Three of the twelve are about the output rather than the target. Validation before reporting, evidence capture, and report writing. Another two are about workflow rather than technique: the recon playbook with escalation gates, and the bug bounty methodology with prioritisation.
That leaves seven for actual discovery, which is where most of a security pack's content would normally go. The ratio is the interesting part: this one gives roughly a third of its entry list to the stages where a finding becomes defensible.
There is also a second naming convention the directory tree does not show. The README notes that skills prefixed `hunt-` cover individual vulnerability classes and platform surfaces, and none of the six directory descriptions mention where they live, so a reader looking for the hunt-prefixed material has to search for it.
One naming entry is worth reading as the pack's own summary of its scope: the catalogue is described as primarily focused on external web security.
Everything writes beneath one output directory and nothing is isolated
Two conventions govern where work goes and what the pack assumes about your environment.
The first is an output location. You set it before running anything:
export OUTPUT_DIR="${OUTPUT_DIR:-./output}"
mkdir -p "$OUTPUT_DIR"
and the README states that commands write persistent artifacts beneath that directory unless a skill documents a different input. So results accumulate in one place by default, which is what you want if you are running an engagement and need to reconstruct what was done.
The second is a single sentence that covers everything the pack does not do: commands assume standard Linux tooling unless a skill says otherwise, and tool availability, scope, network policy, concurrency, credentials and isolation all remain the operator's responsibility.
Read that list carefully. Tool availability, obviously. Scope, which is the legal boundary. Network policy. Concurrency, which is how a set of documents can turn into a load on a target. Credentials. And isolation.
There is no sandbox here, no credential store and no scope enforcement mechanism, because there is no code to enforce them in. The pack is a set of procedures, and procedures put the responsibility for those six things where the person running them can act on it.
For anything beyond a single-target exercise, that means the isolation has to come from somewhere else: a container, a separate account, or a network you control.
Three governing documents, one of them called SOUL.md
The quality section routes you to three files by describing what each one holds.
The quality baseline is in STYLE.md. Contributor guidance is in AGENTS.md. The operating principles are in SOUL.md.
That last name is unusual in a security repository. Everywhere else in this pack the naming is functional: hunt- prefixes for vulnerability classes, a playbook for end-to-end workflow, methodology for prioritisation, hygiene for evidence handling. A file called SOUL.md is the one piece of vocabulary borrowed from agent configuration rather than from security practice, and it points at who this pack is written for.
The rest of the top level matches the pattern. There is a change log and a licence, both resolved correctly by the README links, plus a banner image and the scripts directory holding the validator.
Two things are worth noting about the repository's shape as a whole. There are no GitHub releases, so there is no versioned artefact to install; the pack is consumed by reading whatever is on the default branch. And there is no runtime dependency list, no package manifest and no test framework, because a catalogue of documents has nothing to execute.
The prose lives elsewhere. The repository description points at a personal site for a pentest playbook, field notes and tooling, which is where the reasoning behind the skills is written rather than the skills themselves.
Editorial conclusion
recon-skills suits someone who already knows external web security testing and wants a documented procedure with stated prerequisites and stated verification criteria, rather than a tool that runs and reports. Three things to note. It is documents, not code, so there is nothing to install and nothing to load; an automation system can read the same files as context. The pack provides no isolation, no scope enforcement and no credential handling, and says so in one sentence, which means the operator owns all of that. And the quality baseline is being applied incrementally, so older skills will read differently from newer ones. Read STYLE.md before copying a skill into your own workflow, because the sections a skill is expected to contain are what make it reviewable.
Frequently asked questions
What is recon-skills and what is in it?
A curated pack of markdown documents for authorized external security testing, in six directories covering authentication and single sign-on, attack-path analysis, infrastructure, engagement planning, discovery and enumeration, and vulnerability-class playbooks. Each skill is a SKILL.md file.
How do I find the skills in recon-skills?
With filesystem tools rather than a runtime. `find . -name SKILL.md -print | sort` lists every skill, and ripgrep across SKILL.md files searches all of them at once for a technique name.
What does each recon-skills skill have to contain?
A focused objective plus the prerequisites, the procedure, the pitfalls, the verification criteria and the related techniques. The verification criteria are what distinguish a result from a suspected finding.
How does recon-skills handle quality?
A validator script, run with `python3 scripts/validate_skills.py`, fails on structural errors and reports existing style debt as warnings so the baseline can be raised incrementally. The baseline itself is defined in STYLE.md.
Does recon-skills provide any sandboxing or scope enforcement?
No. The documentation states that tool availability, scope, network policy, concurrency, credentials and isolation all remain the operator's responsibility. The pack is documents, with no runtime and no code to enforce boundaries with.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uphiago-recon-skills)Star history chart for your README
[](https://hysenlabs.com/projects/uphiago-recon-skills)Was this useful?