ai-goofish-monitor watches Xianyu with a real browser and a pasted cookie
A Playwright- and AI-powered multi-task real-time/scheduled monitoring and intelligent analysis system for Xianyu (Goofish), with a full-featured admin UI to help users find desired items among its vast listings.
At a glance
- What is it?
- ai-goofish-monitor is a Playwright and AI monitoring system for Xianyu, the second-hand marketplace, with a Web UI for tasks, accounts, logs and results. It works by driving a real browser and by rotating accounts and proxies when the site pushes back, and both of those facts shape everything else about running it.
- Who is it for?
- This is a competent tool for one specific job, watching a marketplace you are allowed to browse, and it suits a person who already knows what they are looking for and wants a phone ping when it appears.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 36 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
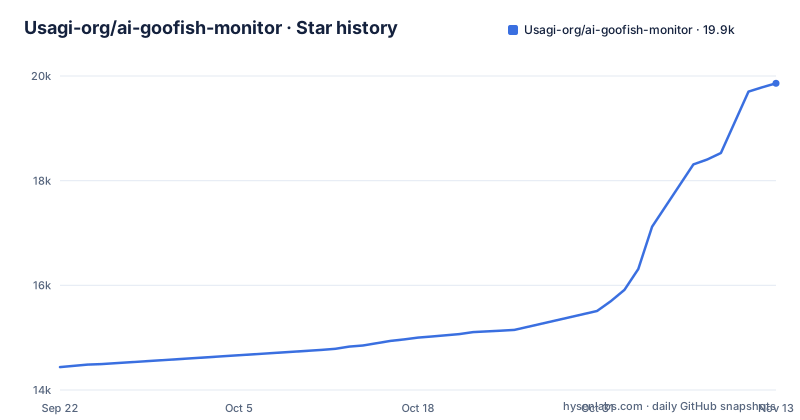
- Usagi-org/ai-goofish-monitor19,861 ★ · +5,424
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| Usagi-org/ai-goofish-monitor | 14.4k | 19.9k |
5,424 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The login state is a pasted cookie file, not a username and password
Nothing in this system types your credentials into the marketplace. You install a Chrome extension, export the Xianyu login state as JSON, and paste it into the account management screen, where it lands as a file such as state/acc_1.json. Each task can bind a specific account or leave the binding empty and let the system choose. That makes the cookie file the entire identity of the installation, and it explains the shape of the logs: the per-task log page exists specifically to help diagnose expired login state, risk control triggers, and AI call problems. The consequence is that session lifetime is your problem to manage. The README points to the per-task log page as the place where an expired login state shows up. It also means state/, like data/, is a mounted directory you cannot regenerate by re-running anything, so it deserves a real backup rather than a copy of the compose file.
Editing config.json changes nothing on the default path
spider_v2.py reads its task list from SQLite by default. The older JSON configuration mode only activates when you pass an explicit --config <path> argument, which means editing config.json and restarting changes nothing for an ordinary run. That surprise survives into containers, because docker-compose.yaml still bind mounts ./config.json to /app/config.json alongside data, state, prompts, jsonl, logs, images and price_history. The reason the file is still there is the migration path: on startup the app creates the database and tables if needed and makes one attempt to import history from the old config.json, jsonl and price_history locations, after which you can decide per deployment whether to keep those mounts. The consequence for a first-time user is a file that looks authoritative and is inert, so the task definitions you think you edited will never run unless you also pass the flag that selects them.
The container runs as root and hardcodes port 8000
The recommended install is the container path, and it is six lines:
git clone https://github.com/Usagi-org/ai-goofish-monitor && cd ai-goofish-monitor
cp .env.example .env
vim .env # 填写相关配置项
docker compose up -d
docker compose logs -f app
docker compose down
The final stage of the Dockerfile sets USER root, exposes 8000, and starts through tini with the command python -m src.app. The compose file maps "8000:8000" literally and reads configuration twice, once through env_file and once by mounting ./.env into the container. SERVER_PORT defaults to 8000, and the documentation is explicit that changing SERVER_PORT in .env means editing the port mapping in docker-compose.yaml yourself, because nothing derives one from the other. Those two facts together are the operational trap. The consequence for anyone exposing this beyond a laptop is that the default credentials and the root user arrive in the same container as your Xianyu login cookies, and the port you publish is the port the compose file hardcodes unless you remember the second edit. Updating the image is a separate manual step as well: docker compose pull followed by docker compose up -d, not a restart.
The default admin/admin123 password and a login state in browser storage
Web UI authentication works through a login page that posts to /auth/status, and once it succeeds the frontend keeps the login state in the browser's own local storage so route guards and the WebSocket connection can initialize. The shipped default is admin/admin123, and the documentation says plainly to change it in production. No hashing scheme, session store, or transport setting is described anywhere in the README, so the security model is exactly the login page. The consequence is a mismatch between where the identity lives and where the value lives: your Xianyu cookie sits in state/ on disk while the UI session sits in whichever browser you logged in from. On a shared machine, the browser profile is now as sensitive as the mounted state directory, and the first change to make on any reachable deployment is that default password.
The region filter is a frozen snapshot scraped from Xianyu pages
Area filtering moved to a three level picker for province, city and district, and its data comes from a snapshot of Xianyu pages that was scraped once and built into the project. There is no control in the system settings for refreshing that snapshot, and the UI guidance is to leave the region field empty by default because filtering on it sharply shrinks the result set. Both halves of that advice are consequences of the same design: a filter that reduces results is fine when you know the area, and dangerous when the area list itself is a copy of what the site looked like on one day. Administrative divisions get reorganized, and listings move. So a district in the picker can match nothing on the live site, and a district the site still serves can be missing from the picker entirely. If you filter by area and get silence, the stale list is the first thing to rule out, not your search terms.
Python 3.10 on your laptop, 3.11 and Node 22 inside the image
The documented local requirements are Python 3.10 or newer, Node.js with npm, where Node v20.18.3 is the version noted as completing a frontend build, plus the Playwright CLI and Chromium with the one line install step python3 -m pip install playwright && python3 -m playwright install chromium. The container does not match any of that exactly: the frontend is built on node:22-alpine, the runtime is python:3.11-slim-bookworm, pip pulls from a Tsinghua mirror index, and the image installs requirements-runtime.txt rather than requirements.txt, the file that lists pytest, pytest-asyncio and coverage. start.sh checks the Playwright and browser prerequisites first, then installs dependencies, builds the frontend, copies the output into a root dist directory and starts the backend. Chromium goes in with a no-shell install and PLAYWRIGHT_BROWSERS_PATH set. The consequence is that a local run and a container run are different environments on Python minor version, Node major, and package index. The newest release is 2.5 from 2026-10-09, and the last push to master is 2026-10-10.
AI task creation returns 202 and a job, not a finished task
The task creation API has two shapes behind one endpoint. POST /api/tasks/generate with decision_mode=ai returns a 202 plus a job identifier, because AI mode first generates the analysis criteria from a detailed description and only then creates the task, so progress is polled through GET /api/tasks/generate-jobs/{job_id}. With decision_mode=keyword the endpoint returns the created task directly, since keyword rules skip generation entirely. The Web UI mirrors this with a separate progress dialog for AI tasks. Three variables are mandatory before any of it works: OPENAI_API_KEY, OPENAI_BASE_URL for an OpenAI compatible endpoint, and OPENAI_MODEL_NAME, which must name a model that accepts image input. That last requirement comes from the runtime flow, which downloads product images into a per-task directory and then asks the model to judge them, and those images are cleaned up after the task by default. PROXY_URL applies to AI requests specifically, not to the browser traffic.
Risk control is answered with rotation, so a miss leaves no error
The processing loop the project publishes ends in a branch for risk control or exceptions that rotates the account or proxy and retries the search. The tuning surface is a block of variables: PROXY_ROTATION_ENABLED, PROXY_ROTATION_MODE, PROXY_POOL, PROXY_ROTATION_RETRY_LIMIT, PROXY_BLACKLIST_TTL, plus TASK_FAILURE_THRESHOLD, TASK_FAILURE_PAUSE_SECONDS and TASK_FAILURE_GUARD_PATH for pausing a task that keeps failing. Set up this way, rotation is a recovery path and a concealment at the same time. A blocked account or a burned proxy produces a retry rather than an alert, and the place it shows up is the per-task log page, which the README says helps diagnose risk control problems. The project states the other side of this plainly in its own notice: follow the marketplace user agreement and robots.txt, keep request frequency down, and understand that an account can still be restricted. Rotating faster raises your account count, not your safety.
Editorial conclusion
This is a competent tool for one specific job, watching a marketplace you are allowed to browse, and it suits a person who already knows what they are looking for and wants a phone ping when it appears. It is not a market research instrument and not something to run wide: the region filter data is a frozen scrape snapshot, results and history live in one SQLite file, and the answer to a risk control block is account and proxy rotation, so a block shows up in the task log rather than as an alert. Before you start, confirm three things. Change the default admin/admin123 Web UI credentials. Wire the three required variables to a model that accepts image input, since OPENAI_MODEL_NAME must take images. And if you change SERVER_PORT, edit the port mapping in docker-compose.yaml too, because the container hardcodes 8000 and runs as root. The project's own notice asks that you respect the site agreement and robots.txt, and that constraint outranks anything the rotation settings can buy you.
Frequently asked questions
What does ai-goofish-monitor actually watch?
It monitors Xianyu listings through Playwright, running multiple tasks either continuously or on a Cron schedule, with keywords, price ranges, new-listing windows and AI prompts configured per task. Discovered items are analyzed by the model, saved into SQLite at data/app.sqlite3 together with tasks and price history, and pushed out through ntfy.sh, WeCom, Bark, Telegram or webhook channels.
Why does ai-goofish-monitor need a model that takes images?
OPENAI_MODEL_NAME must name a model that supports image input, because the task flow downloads product images into images/task_images_<task_name>/ and hands them to the model for analysis before deciding whether to notify you. Those temporary images are cleaned up by default once the task finishes. All three of OPENAI_API_KEY, OPENAI_BASE_URL and OPENAI_MODEL_NAME are required.
Can I run ai-goofish-monitor without a local Python or Node setup?
Docker is the recommended path: clone the repository, copy .env.example to .env, fill in the values, then run docker compose up -d, following the logs with docker compose logs -f app. The image ghcr.io/usagi-org/ai-goofish:latest already contains Chromium, so no browser has to be installed on the host, and the Web UI comes up at http://127.0.0.1:8000.
How is the AI analysis task tested?
The pytest configuration marks live tests as real traffic smoke tests that require real credentials and external services, and adds a live_slow marker for slower optional runs such as AI task generation. The documented validation command is PYTEST_DISABLE_PLUGIN_AUTOLOAD=1 pytest, followed by cd web-ui && npm run build.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/usagi-org-ai-goofish-monitor)Star history chart for your README
[](https://hysenlabs.com/projects/usagi-org-ai-goofish-monitor)Was this useful?