stealth-browser-mcp claims to be the only automation that gets past anti-bot systems, then hedges it in the next paragraph
The only browser automation that bypasses anti-bot systems. AI writes network hooks, clones UIs pixel-perfect via simple chat.
At a glance
- What is it?
- vibheksoni/stealth-browser-mcp is an MCP server that drives real Chrome, Chromium and Edge instances over the DevTools Protocol and exposes 98 tools. Two of those tools, arbitrary code execution and synthesised key events, are restricted to trusted local clients, which sits awkwardly beside the hosted-directory configuration the repository also ships.
- Who is it for?
- Read this as a tool with a real trust boundary rather than as an evasion product, because that is what the code says. It drives a genuine browser on your own machine instead of emulating one, and the two capabilities that would make it dangerous to expose, running arbitrary script in the page and synthesising input events, are both restricted to local clients.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
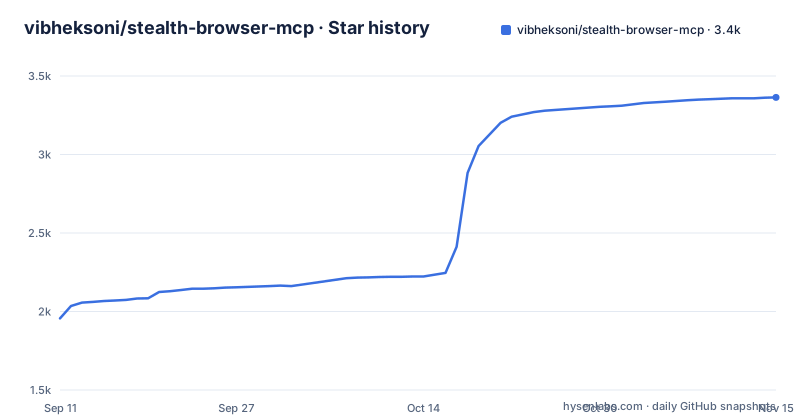
- vibheksoni/stealth-browser-mcp3,364 ★ · +1,408
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| vibheksoni/stealth-browser-mcp | 2k | 3.4k |
1,408 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two metadata claims and one honest hedge
The repository description claims this is the only browser automation that bypasses anti-bot systems, and the package description inside the project file claims an undetectable browser automation MCP server with protocol-level access. Both are superlatives that nothing in the repository supports.
The body of the readme is considerably more careful. The anti-bot feature entry says the tool has passed Cloudflare and Queue-It style challenges in testing, and then adds that results vary by site, region, browser version and detector version. That sentence is the accurate description of what this class of software can promise, and it contradicts the two metadata claims sitting above it.
The mechanism itself is not exotic. The server launches real Chrome-family browser instances using an existing driver library and talks to them over the DevTools Protocol. There is no fingerprint spoofing layer described, no header rotation and no captcha-solving service; what it has is a real browser instead of an emulated one, which is the honest version of the claim and also the part that actually does most of the work.
So read the feature list, not the description field. The rest of this article does the same, and it deliberately does not describe how any particular site's checks are negotiated.
One release in February, commits through September
There is a single release on the platform, tagged in February 2026, and its title names three things: a protocol fix, added support for Edge, and repository cleanup. The last commit on the default branch is dated 2026-09-25, which is about seven months later.
So the project has had no new tag since February while the branch kept moving. That is a normal pattern for a single-maintainer tool, and it has one practical consequence: there is no release to fall back to if a commit breaks your setup, and no changelog on the platform telling you what the seven months of commits contain.
The repository does carry its own version history in files rather than in tags. There is a changelog, a roadmap, a hall of fame, a document about its own stealth tests, and a comparison document against Playwright's MCP server. There is also an assistant instruction file, a code owners file, a security policy and a code of conduct, which is a heavier governance surface than most projects of this size carry.
The last push date is recent enough that nothing here reads as abandoned. It simply reads as a project whose release discipline and commit cadence have drifted apart.
The two dangerous tools are limited to local clients
The tool surface is large and the security design is concentrated in two places. Direct protocol execution, which covers running JavaScript, sending raw protocol commands and injecting pre-document scripts, is available only through trusted local MCP clients. So is instant text input, which covers pasting large content, typing with human-like keystrokes, and pressing real keys with trusted protocol key events.
Everything else is broader. Network inspection exposes requests, responses, headers, payloads and captured bodies. The dynamic hook system runs Python hooks that can intercept, block, redirect, fulfil or modify request and response flows, and it is described as restricted rather than open. Pixel-accurate element cloning pulls complete elements with their styles, document structure, event handlers, animations and assets. So an agent with a local connection can read traffic, rewrite responses, inject script before the page loads and synthesise input events, which is a very large surface for one tool to hold.
The boundary is therefore entirely about who is connected. A local MCP client launched by the person sitting at the machine is trusted. Anything else is not, and the two sharpest capabilities follow that rule.
Which is why the hosted-directory configuration file in the repository root sits oddly beside it. That file is for listing the server in a hosted MCP directory, and a hosted server is by definition not on your machine. The trust model and the deployment option pull in opposite directions, and the readme does not say which wins.
The transpiler that writes page script comes from a fork, pinned to one commit
The dependency list has twelve entries, and eleven of them are pinned to exact versions. The twelfth is not.
It is a Python-to-JavaScript transpiler, installed directly from a GitHub fork at a specific commit hash, authored by someone other than the maintainer. That is the component which turns Python into script the page can run, which makes it the load-bearing piece for the protocol-execution capability described above. The container build installs a version control client explicitly, with a comment saying it is needed for that package, so the install genuinely reaches out to a fork rather than to an index.
Pinning a fork to a commit is a defensible choice and it is what the project did. It is also the single decision in this file with the least conventional supply-chain shape, and the honest way to weigh it is to go read that commit before you depend on it.
The other eleven are ordinary: the server framework, the browser driver, a settings library, a dotenv loader, a JavaScript beautifier, two small string-building libraries at very low version numbers, a process utility, an imaging library, an HTTP client and an application server. The low version numbers on the two string libraries are worth a look, since a version of zero point zero four is a different risk conversation from a version of two.
One dependency list, written twice, and your install reads one of them
The project file and the requirements file contain the same twelve entries with the same pins, in a different order. The installation instructions tell you to run pip against the requirements file, not to install the project, so the dependency list inside the project metadata is not what ends up in your environment.
That duplication is the kind that rots quietly. Nothing in the build, in the documentation or in the visible configuration checks that the two files agree, and a contributor adding one library has two places to remember. The container build also reads the requirements file, so the runtime and the documented install agree with each other and disagree with the manifest.
Two smaller things are visible in the same file. The licence is declared in the older table form with the licence name as its value rather than using the modern single-string form, which is legal but is the form tooling handles least well. And four project URLs are declared, pointing at the repository, its documentation anchor and its issue tracker, while the platform's own metadata for the repository records no homepage at all.
For the toolchain: one formatter at a line length of a hundred targeting four Python versions, an import sorter on the black profile, and a type checker pinned to the lowest supported version with return-type warnings enabled.
Bearer auth off by default, listening on every interface
The container is the clearest statement of the deployment posture, and it has both good and awkward parts.
The good part is that it creates an unprivileged user with a fixed identifier, hands it the application directory, and switches to it before the server starts. It also installs Chrome properly, by fetching Google's signing key, dearmoring it into a keyring, adding Google's own package repository with a signature check, and installing the stable channel. A virtual framebuffer server is installed for the headless case. Package lists are cleaned after each install.
The awkward part is the last two lines of the file. The server starts with an explicit bind to all interfaces, and bearer authentication is switched on only if a token variable is set in the environment. The health check then branches on that same variable, calling the server without an authorization header when the token is absent and with one when it is present.
So the default image is an unauthenticated MCP server reachable on every network the container is attached to. That is a reasonable default for a server run locally and a poor one for a server run on a host with a routable address, and the file gives you no hint about which case it is assuming.
Port 8000 is exposed and set as an environment variable, with a comment noting the hosted directory will set it.
98 tools in 11 sections, or 21 in a core
The size of the surface is the headline number and the reason the project ships a smaller one. There are 98 tools across 11 sections, or a 21-tool core, and sections can be switched off individually. For an agent-facing server that is the difference between a model being handed a hundred choices and being handed twenty.
The categories follow from the architecture: navigation basics, the protocol execution and key event tools that carry the trust restriction, network inspection and hooks, element cloning, and post-processing. There is also a standalone skill file in the repository for clients that support repo-local skills, and what it teaches is telling: the recommended tool order, checks that browser state is what you think it is, how to use pre-document scripts, a network debugging flow, and rules for cleaning the browser up.
The stated purpose of the skill is diagnostic. It is for when a model picks the wrong tool or forgets to verify state after acting, which is an admission that the tool count is itself a failure mode.
The install itself is four steps, and note that the dependency step reads the requirements file rather than the project:
git clone https://github.com/vibheksoni/stealth-browser-mcp.git
cd stealth-browser-mcp
python -m venv venv

# Windows
venv\Scripts\activate

# macOS / Linux
source venv/bin/activate

pip install -r requirements.txt
Registration is then offered in four shapes: a command that adds the server as a stdio JSON entry, which the readme calls the recommended path; hand-written JSON for a desktop client and one other editor, with the per-platform config file locations given; a framework installer path that the readme labels experimental and says is for people who prefer it; and two launch scripts, one shell and one batch, at the repository root.
Editorial conclusion
Read this as a tool with a real trust boundary rather than as an evasion product, because that is what the code says. It drives a genuine browser on your own machine instead of emulating one, and the two capabilities that would make it dangerous to expose, running arbitrary script in the page and synthesising input events, are both restricted to local clients. Three things to settle before you use it. Treat the anti-bot claim as marketing, since the feature list itself says results vary by site, region, browser version and detector version. Decide where it runs, because the bearer token is off by default while the container listens on every interface. And check the dependency supply chain, because the piece that turns Python into page script arrives from a third-party fork pinned to a single commit, and the published dependency list is duplicated in two files of which your install reads only one.
Frequently asked questions
What is stealth-browser-mcp?
An MCP server that drives real Chrome, Chromium or Microsoft Edge instances over the DevTools Protocol using the nodriver library. It exposes 98 tools across 11 sections, or a 21-tool core, with sections that can be switched off individually.
Does stealth-browser-mcp get past anti-bot checks reliably?
The project does not claim that. Its repository description says it is the only automation that does, while the feature list says only that it has passed Cloudflare and Queue-It style challenges in testing and that results vary by site, region, browser version and detector version.
Which stealth-browser-mcp tools are restricted?
The two that execute code or synthesise input. Running JavaScript, sending raw protocol commands and injecting pre-document scripts are limited to trusted local MCP clients, as is instant text input with paste, keystrokes and real key events. The network hook system is described as restricted Python hooks.
What does stealth-browser-mcp need to run?
Python 3.10 or newer plus Chrome, Chromium or Microsoft Edge, with the executable found automatically. The container is built on Python 3.11 slim with Google Chrome installed from Google's own package repository and a virtual framebuffer server for the headless case.
How do I install stealth-browser-mcp?
Clone the repository, create and activate a virtual environment, then run pip install -r requirements.txt. Registration is a stdio JSON entry added to your MCP client, which the readme calls the recommended path. A framework installer path is also given and labelled experimental, and hand-written JSON is provided for a desktop client and another editor.
Does the stealth-browser-mcp container require authentication?
Not by default. Its command starts the HTTP transport bound to all interfaces, and bearer authentication is enabled only by setting an auth token environment variable, which the container's health check also branches on. The container does run as a non-root user created during the build.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vibheksoni-stealth-browser-mcp)Star history chart for your README
[](https://hysenlabs.com/projects/vibheksoni-stealth-browser-mcp)Was this useful?