Vulners Python SDK: typed bulletins, a branch-only prerelease, and a 100% coverage gate
Official Python SDK for the Vulners vulnerability-intelligence API — search CVEs, exploits and advisories (CVSS/EPSS/KEV), audit software, Linux/Windows hosts and SBOMs, and stream the whole graph. Typed sync + async clients, 100% v3-compatible, with a built-in MCP server for AI agents.
At a glance
- What is it?
- The official Python client for the Vulners vulnerability intelligence graph, wrapping HTTP/2 transport, three layers of typed bulletin models, audits over software, hosts and SBOMs, and lazy archive streaming. Its Makefile is unusually honest about what is measured: the new core is gated at full branch coverage and the legacy layer is exempt.
- Who is it for?
- vulners is the SDK to reach this data from Python, and its shape suits pipelines: typed models instead of dictionaries, an async client with the same surface, lazy archive streaming for datasets you cannot buffer, and an MCP server for agents that need live facts rather than a cached summary.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 17 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
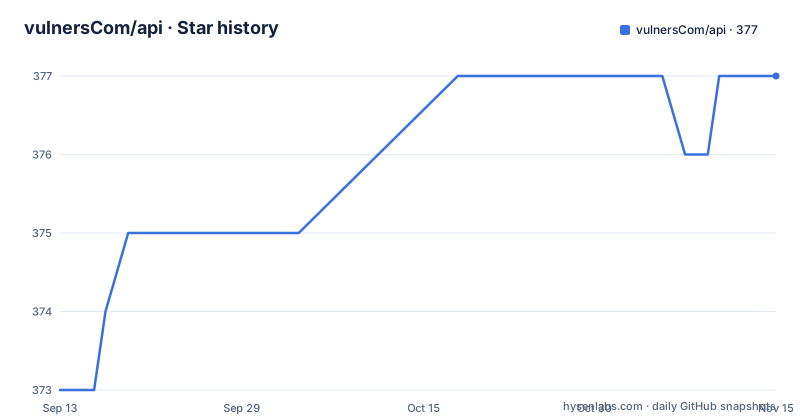
- vulnersCom/api377 ★ · +4
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| vulnersCom/api | 373 | 377 |
4 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One line installs it, and the prerelease does not
Installation from PyPI is a single command:
pip install -U vulnersPython 3.10 or newer is required, and the package metadata classifies support up to 3.14, carries a PEP 561 marker, and is marked Development Status 4, Beta.
The dependency list is worth reading because it describes what the client chooses to do. httpx is the transport, pydantic the model layer, orjson the parser. On top of those sit h2 for HTTP/2, brotli and zstandard for response compression, ISA-L accelerated gzip, and ijson with stream-unzip for streaming archive decode. The readme states that all of them have prebuilt wheels, so there is no build step on any supported platform.
The prerelease has a different home. The latest pre-release lives on the v4.0 branch and is not yet on PyPI, so it is installed from source, either by checking the branch out:
git clone -b v4.0 https://github.com/vulnersCom/api.git
cd api
pip install -e .        # editable install from the checkout
or directly without cloning, with pip install "git+https://github.com/vulnersCom/[email protected]".
The gap between a published 4.3.0 and a branch-only 4.0 prerelease is confusing on first reading, and the released versions are all in the four range.
Every dependency earns its place in the comment
The pyproject dependency list is annotated, which is unusual and turns out to be the clearest statement of intent in the repository.
One entry is kept explicit rather than transitive: typing-inspection, with a comment saying the legacy shim layer in base.py imports it directly, so a pydantic that drops the transitive dependency cannot break imports. That is a pin made for a shim, not for current code.
h2 is described as HTTP/2 transport, on by default, and pure Python so there is no wheel or build concern. stream-unzip is there for decoding streaming multi-member zip archives, also pure Python.
The compression pair has the clearest rationale. The comment says httpx advertises br and zstd and decompresses them transparently only when those decoders are importable, which is why they are named explicitly: without them installed, the transport quietly negotiates something weaker rather than failing.
Taken together, the list is a statement about failure modes. Each dependency removes a way the client could silently do less than it appears to. There is also a documented reason the archive decoder is a dependency at all: the datasets capability is meant to feed mirrors, and a mirror that has to hold an entire collection in memory to walk it is not a mirror.
Three typed layers, and the most specific model wins
Every document the API returns is a bulletin, and the SDK models that in three layers so a type checker knows the shape at whatever detail you need.
The base is Bulletin, carrying the fields every document has: id, title, cvss, published and the rest. Above it sit family models, one per bulletinFamily, so CveBulletin, ExploitBulletin and ScannerBulletin each add the fields that family shares. Above those sit collection models, one per collection type, adding what is specific to that source.
The search, archive and audit entry points return the most specific model that fits the document, rather than the base type. That is the difference between reaching for a field you know exists and checking whether it does.
The quickstart shows what that buys. A bulletin lookup returns a typed model or None if the identifier is not found, and the fields are attribute access rather than dictionary keys, including the nested cvss object with its score and vector.
Search accepts Lucene syntax, and the paging contract is stated in a comment rather than left to be discovered: limit is the page size, reading the first page is explicit, and iterating the page object auto-paginates.
Audits accept dicts, CPE strings and package lines
The audit entry points are the most practically useful part of the surface, and each takes the format an inventory system already has.
Software audit takes a list that mixes product and version dictionaries with raw CPE 2.3 strings, and reports the matched criteria against the number of vulnerabilities found:
for item in v.audit.software([{"product": "openssl", "version": "1.0.1"},
                              "cpe:2.3:a:apache:log4j:2.14.1"]):
    print(item["matched_criteria"], "->", len(item["vulnerabilities"]), "vulnerabilities")
A host audit takes an operating system name and version with a list of installed packages, and returns issues keyed by package, which is the shape a package manager query already produces.
Package metadata lookups carry the subtlety worth reading twice. The license field is always a list, never a bare string, so callers never have to branch on type. An empty license with found set to True means the package is known but has no recorded license. found set to False means the registry does not know the package name at all. Two very different facts, distinguished by a flag rather than by an empty response, and a caller that ignores it will treat a missing licence as a permissive one.
The note about Maven naming the groupId and artifactId coordinate continues past what is readable here.
The archive is streamed, never buffered
Datasets are the feature that changes how you would build a mirror, and the mechanism is a generator:
for record in v.archive.iter_collection("cve"):
    ...  # each record is yielded as it arrives (a lazily-streamed JSON array)
Each record is yielded as it arrives from a lazily streamed JSON array, so the memory cost is one record rather than one collection. For an archive whose size is measured in gigabytes, that is the difference between a download you can run and one you cannot.
The surrounding capability is described as streaming the full graph, and hourly updates, into your own pipelines and mirrors. Hourly matters as much as the streaming: a mirror that only syncs on demand is a snapshot, while one that takes the update feed stays current.
Exploits sit next to it as a separate capability, tracking active exploitation and pulling proof-of-concept code for a product or a CVE, and the intelligence search itself enriches bulletins with CVSS, EPSS, KEV and exploitation context. Alerts are the third: subscribe to new vulnerabilities matching a query and receive them by webhook.
So the data side is read-only and pull-based, which matches the stated design that the API is API-first and needs no agents or network access on your side to submit asset data.
Rate limits arrive as a typed error with a retry_after
Error handling is shown as a first-class example rather than left to the documentation site, and the shape is what makes retry logic easy.
from vulners import Vulners, APIError, RateLimitError

try:
    with Vulners(api_key="YOUR_API_KEY_HERE") as v:
        cve = v.search.get_bulletin("CVE-2021-44228")
except RateLimitError as err:
    print("slow down; retry after", err.retry_after, "s")
except APIError as err:
    print(err.status_code, err.error_code, err.message)   # the server's problem description
Two classes, ordered by specificity. RateLimitError carries retry_after in seconds, so a client does not have to invent a backoff when the server already told it. APIError carries the status code, the server's own error code, and a message described as the server's problem description rather than a library string.
That distinction is the point of raising the server's code instead of collapsing everything into a message string. A caller can branch on an error code without parsing English.
The context manager is used throughout the examples, and the async client mirrors the same surface, so the same error handling applies to AsyncVulners.
Coverage is gated at 100% for the core and skipped for the legacy layer
The Makefile is where this repository's engineering standards are written down, and the comments are more informative than the targets.
There is a full test target that runs pytest parallelized across cores with xdist, explicitly including the legacy compatibility tests, and a serial test-fast target described as easier debugging and accurate tracebacks. Type checking runs both mypy and basedpyright, which is a stronger claim than either alone. Linting runs ruff check and the format check together.
The coverage targets carry the most information. The cov target runs pytest with coverage after erasing the previous data, and the comment explains the gate: branch coverage for the new v4 core must stay at 100 percent, enforced by a fail_under setting, with the scope driven by configuration rather than by a hand-written list. Bare coverage measures the whole package, so any new module is inside the gate by default and only the legacy v3 layer is omitted.
The MCP server is measured separately, with a comment giving the reason: it lives behind an optional extra that cannot share the default environment.
Live tests are opt-in and skipped without a key or a local live configuration file, and they run serially so the SDK's per-key rate limiter stays coherent and subscription mutations stay ordered. There is also a backward-compatibility oracle target and an unasync pair for generating the async surface from the sync one. The environment has to be reproducible for any of that to mean much, which is why the Makefile drives everything through uv rather than calling pip directly, and why a lock file is committed.
A v3 and a v4 sample set sit side by side
Runnable examples live under samples/, and the arrangement is deliberate: a v4 set and a matching v3 legacy set, side by side. That is the clearest signal in the repository that this is a v4 rewrite with a compatibility obligation, and that the legacy path is being kept runnable rather than deprecated in place.
The repository layout supports a project with real documentation and real tooling. There is api.md, an llms.txt for agent consumption, an MkDocs configuration, a documentation/ directory, dev-tools/, scripts/, tests/, src/ and samples/, plus AGENTS.md and an .agents/ directory, a pre-commit configuration, an AUTHORS file, a CHANGELOG, CONTRIBUTING and SECURITY. A uv.lock sits at the top level, matching the Makefile's reliance on uv for every task.
The platform underneath is described as aggregating more than 230 sources, CVEs, exploits, vendor advisories, CISA KEV, EPSS and AI risk scores, into one queryable graph, with the stated purpose being to prioritize what to fix beyond raw CVSS.
The release trail is three versions in one week: v4.3.0 on 21 August 2026, v4.2.0 on 18 August and v4.1.0 on 17 August, with the package version at 4.3.0 and the licence MIT. The last push is dated 28 September 2026.
Editorial conclusion
vulners is the SDK to reach this data from Python, and its shape suits pipelines: typed models instead of dictionaries, an async client with the same surface, lazy archive streaming for datasets you cannot buffer, and an MCP server for agents that need live facts rather than a cached summary. Before you depend on it, note that the prerelease lives on the v4.0 branch rather than PyPI, that the package is marked Beta and its status says interfaces are moving, and that the coverage discipline covers the new core only. Read your API key from the environment, as the quickstart tip says, and keep the audit calls for inventory you actually own.
Frequently asked questions
How do I install the Vulners Python SDK, including the prerelease?
The released version installs with pip install -U vulners and needs Python 3.10 or newer. The prerelease is not on PyPI: it lives on the v4.0 branch and is installed either by cloning that branch and running pip install -e . or by pip install "git+https://github.com/vulnersCom/[email protected]".
What does the Vulners audit API accept as input?
Software audit takes a list mixing product and version dictionaries with raw CPE 2.3 strings, and host audit takes an operating system name and version with installed packages, for example openssl 1.1.1d-0+deb10u3 amd64.
How does the Vulners SDK handle rate limiting?
It raises RateLimitError carrying retry_after in seconds, alongside APIError with the status code, the server error code and its message. The examples catch RateLimitError first and print the retry delay rather than inventing a backoff.
Can I stream the Vulners archive without downloading it all?
Yes. archive.iter_collection("cve") yields each record as it arrives from a lazily streamed JSON array, so the memory cost is one record rather than the whole collection. Hourly updates are available for keeping a mirror current.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vulnerscom-api)Star history chart for your README
[](https://hysenlabs.com/projects/vulnerscom-api)Was this useful?