WAL-G's binary name carries the database and the OS in one string
Archival and Restoration for databases in the Cloud
At a glance
- What is it?
- WAL-G is a Go archival and restore tool for PostgreSQL, MySQL and MariaDB, MS SQL Server, and two databases it marks as beta. It is configured through environment variables or a config file, and the settings worth reading first are the encryption set: four key backends, one of them deprecated, one of them tied to a single cloud provider.
- Who is it for?
- WAL-G fits an operator who already has continuous archiving configured on a database and needs to move base backups and write-ahead logs into object storage, or restore them out of it. It does not fit someone who wants envelope encryption through any cloud's key service, because the envelope option is limited to Yandex Cloud KMS.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
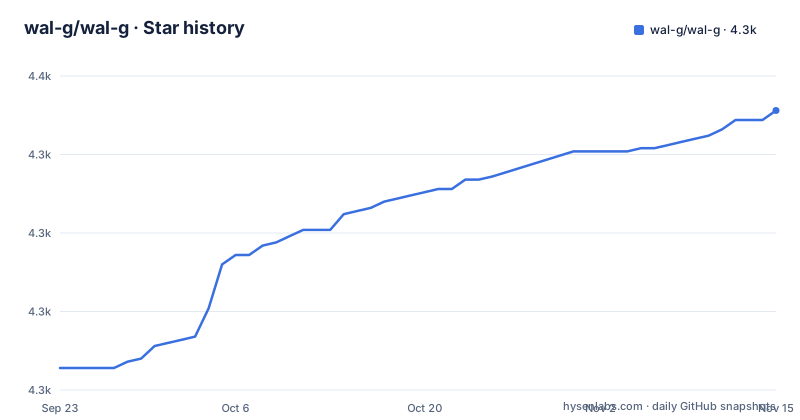
- wal-g/wal-g4,339 ★ · +82
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| wal-g/wal-g | 4.3k | 4.3k |
82 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The binary name carries the database and the OS
The install path starts with a filename format that packs three things into one string.
The format is the binary name, the database name, and the operating system name, where the database placeholder is something like the Postgres or MySQL abbreviation.
The two commands that install it follow the same template.
tar -zxvf wal-g-DBNAME-OSNAME-amd64.tar.gz
mv wal-g-DBNAME-OSNAME-amd64 /usr/local/bin/wal-g
The concrete example names a Postgres build on one Ubuntu release.
tar -zxvf wal-g-pg-24.04-amd64.tar.gz
mv wal-g-pg-24.04-amd64 /usr/local/bin/wal-g
Note the extra suffix the format does not describe: the archive is named with the architecture appended, and so is the extracted binary. And the OS placeholder holds something like a distribution version rather than an operating system name, which is why one number is doing duty as an OS identifier.
Only one platform is published this way, and the page says so: a precompiled binary for Linux on AMD 64. Everything else is pointed at the development section.
Nine variables configure encryption across four backends
Encryption is the largest block in the configuration, and it is worth taking as a list before taking as detail.
One pair configures a cloud key management service for client-side encryption, and one of that pair names a key file. When the file is not set, the tool falls back to a token from the instance metadata service, at the link-local address every cloud exposes.
Three more configure a symmetric scheme from a system library: the key itself, a path to a key file whose contents are trimmed of surrounding whitespace, and a transform that decides how your text becomes the 32 bytes the library requires. The transform options are hex, base64, or none, with none kept for backwards compatibility and defined as truncating or zero-padding whatever you give it.
Three more configure OpenPGP, for the key itself, a path to it, and a passphrase for an encrypted private key.
Envelope PGP keys stored in Yandex Cloud KMS add further variables, and by default no encryption is used.
One encryption variable is deprecated and keeps an older prefix
Among the OpenPGP settings there is a line marked deprecated, and it carries two names.
The current name is a GPG key identifier variable. The alternative form of that same variable uses the older WALE prefix, the one the predecessor tool used.
So a setting inherited from the predecessor's era still resolves, and the page marks it deprecated rather than removing it. That is a deliberate compatibility choice, and it is also a naming inconsistency: the same setting has two spellings with different prefixes.
The entry also says the public keyring is cached in a file at the root of the filesystem. That path is worth noticing on its own, because a cache written outside any data directory is the kind of thing that behaves differently on a read-only filesystem or inside a container with a different root.
If you are migrating from the predecessor tool, this is the variable you have already set.
Compression is described as multiples of the default
One variable picks the method and another tunes it.
The method options are four compression algorithms plus a value that disables compression entirely. The default is the fastest of the four, and the page is blunt about the trade: it is the fastest and its compression ratio is bad.
The numbers are given as multiples rather than as adjectives. The slowest method compresses backups about six times better than the default. The two middle options, one of which is zstd and the other Brotli, land at about three times better and are described as a reasonable trade between speed and ratio.
That framing is unusually concrete for a backup tool, because it converts a preference into arithmetic you can check against your own storage cost and CPU budget.
The zstd level variable has four named steps and its own default when unset. Higher levels compress better and cost more CPU, which is the same trade the method choice makes, one level down.
Configuration is environment variables or a file in any viper format
There are exactly two ways to configure the tool, and one of them saves you typing.
The direct way is environment variables. The other is a configuration file, located either by a command-line flag that takes a path or by an environment variable holding the path, which is the option to pick if you do not want to pass the flag every time.
The file format is not fixed. The page defers to a widely used configuration library and inherits everything it can read, naming JSON, YAML and envfiles among the formats, with a link for the rest.
That last point is the one that matters operationally. Because every documented variable can be either an environment variable or a field in that file, the same configuration works as a mounted secret, as a file rendered by an operator, or as a shell profile, with no per-setting translation.
Storage configuration is not covered here. It is delegated to a separate document, STORAGES.md.
Eight database entry points, and the default test server is version 10
The build file defines a main package path per database, and there are eight of them: Postgres, MySQL, SQL Server, Redis, MongoDB, FoundationDB, Greenplum and etcd.
The page's opening sentence names fewer than that. It lists PostgreSQL, MySQL and MariaDB, and MS SQL Server as supported, and marks MongoDB and Redis as beta.
So the binary targets extend past the sentence at the top of the page, and the two entries it does flag as beta are called out for a reason: they are the ones the page asks you to be careful with.
The test configuration has its own story, and it is an odd one. The default Postgres major version for the test services is 14, and the comment notes that PG 10 remains available for explicit compatibility runs using its bionic image with wal-e.
The build reads its own Go version out of go.mod
The Makefile has one line that is worth copying into any project that builds inside a container.
GO_VERSION := $(shell awk '/^go /{print $$2; exit}' go.mod)
export GO_VERSION
export GOEXPERIMENT=simd
The version is parsed out of the module file and exported, and the comment above it says the point is to keep the container image's toolchain in sync with go.mod instead of hardcoding it. One source of truth, so a toolchain bump cannot drift between the module and the build image.
An experiment flag is exported alongside it, which enables a set of optimisations the standard toolchain keeps behind a flag.
Elsewhere the same file pins a linter version, a MongoDB server version, a Redis version, and two different versions of the competing backup tool depending on which Postgres is being tested, because the newer release of that tool needs a build system the old base image does not have.
There is also a single line for the interface that mocks are generated from, with a comment telling you to list more paths there.
The test object store runs on the documented example credentials
The compose file for the integration environment is a list of services, and one of them is an object store standing in for a cloud bucket.
      AWS_ACCESS_KEY_ID: AKIAIOSFODNN7EXAMPLE
      AWS_SECRET_ACCESS_KEY: wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY
Those two values are the access key pair published in the cloud provider's own documentation as examples. They are not secrets, and they are not a mistake, and they are wired in so the test suite can talk to the store without any cloud account.
The rest of the file is a small cloud in miniature: an object store service, an OpenStack-style object store, a metrics pipeline with a graph server and a stats port, two Ubuntu images, and a build container. The object store image is pinned by digest as well as by tag.
The compose file also declares a volume named fdb_volume, and it uses shared dependency blocks through anchors so the throttling variant of the object store does not repeat the wiring.
The metrics service is why the module manifest contains a stats client: the tool reports to it when configured to.
Editorial conclusion
WAL-G fits an operator who already has continuous archiving configured on a database and needs to move base backups and write-ahead logs into object storage, or restore them out of it. It does not fit someone who wants envelope encryption through any cloud's key service, because the envelope option is limited to Yandex Cloud KMS. Before you rely on it, check three things. Whether your database is one of the two marked beta, because those are separated from the rest deliberately. Which compression method you picked, because the four options are stated as multiples of the default rather than as an abstract preference. And which key you generate, since the transform setting decides whether your 32-byte value is read as hex, base64 or a padded blob.
Frequently asked questions
What is WAL g?
WAL-G is an archival and restoration tool for PostgreSQL, MySQL and MariaDB, and MS SQL Server, with MongoDB and Redis marked as beta. It is the successor of WAL-E, and differs from it by using LZ4, LZMA, ZSTD or Brotli compression, multiple processors, and non-exclusive base backups for Postgres. It is written in Go and moves base backups and write-ahead logs to cloud storage.
How do I install WAL-G?
A precompiled binary is published for Linux on AMD 64 under the releases tab. The archive is named with the database, the operating system and the architecture, and you decompress it with tar and move the extracted binary into the local binary path as wal-g. Other systems have no published binary and are pointed at the development section.
Which compression methods can WAL-G use for backups?
Four algorithms plus an off switch, selected by one environment variable: lz4, which is the default and the fastest with the worst ratio, lzma, which is much slower and compresses about six times better, and zstd and brotli, which land at about three times better than the default. A second variable tunes the zstd level between four named steps.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wal-g-wal-g)Star history chart for your README
[](https://hysenlabs.com/projects/wal-g-wal-g)Was this useful?