PyPOTS marks the models that cannot accept missing values and adapts them with one technique
A Python toolkit/library for reality-centric machine/deep learning & data mining on partially-observed time series, with 50+ SOTA neural network models for scientific analysis tasks (imputation, classification, clustering, forecasting, anomaly detection, cleaning) on incomplete industrial irregularly-sampled multivariate TS with NaN missing values
At a glance
- What is it?
- A research toolbox for machine learning on time series with gaps, covering imputation, forecasting, classification, clustering and anomaly detection from one interface. Its most useful idea is also its most honest disclosure: many of the architectures it wraps never claimed to handle missing data, and it says so in the catalogue and then fixes it with a single embedding scheme.
- Who is it for?
- PyPOTS earns its place if your problem is gaps rather than noise, because five task types behind one interface with one consistent example layout per model is more than most single-paper codebases give you. Read the marks in the catalogue before you choose a model, because the ones that need the embedding workaround are the ones whose original papers said nothing about missing data, and that is a different claim from the ones built for it.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
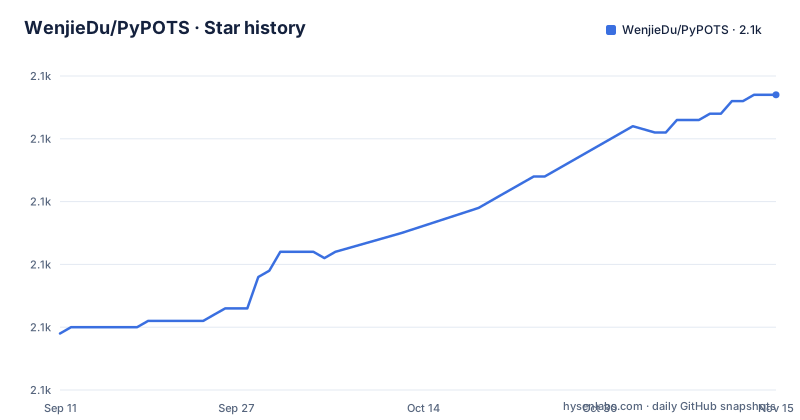
- WenjieDu/PyPOTS2,097 ★ · +38
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| WenjieDu/PyPOTS | 2.1k | 2.1k |
38 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One embedding scheme is what makes the borrowed architectures work on gaps
The catalogue is a table of about fifty models across five task types, and it carries a deliberate visual distinction. Models whose names are marked with a small figure were not originally proposed as algorithms for data with missing values. Their papers do not address it, and they cannot take a time series with gaps as input, let alone fill one in.
To make them usable, the project applies one specific embedding and training approach, the same pair it used in the SAITS paper: an orthogonal-embedding step with masked-interpolation training. That single pair is what lets an architecture designed for dense forecasting data be pointed at a series with holes.
So the distinction is not decoration. A model marked in that table is an architecture you would otherwise find in a forecasting paper, made applicable here by borrowed machinery rather than by anything in its original design. A model without the mark was proposed with missing data in mind. Both are legitimate, and the table is clear about which is which, which is more than most model collections manage.
The five task types are abbreviated in the table as imputation, forecasting, classification, clustering and anomaly detection. Beyond them the package also ships a representation-learning and vectorisation model.
The first row of the availability table is a product with a waitlist, not a paper
The table is sorted by year, newest at the top, and the newest row is not a paper.
It is an entry typed as a foundation-model category, linking to a commercial site, with all five task boxes checked, and its final column, where every other row carries a year and a venue, contains a link to a Google Form titled with the words join waitlist.
So the first thing a reader sees in a catalogue of research algorithms is a service you cannot evaluate from the table, cannot install with pip, and cannot read a paper for. It is placed in the same grid as HELIX from a 2026 machine learning conference, a segmentation recurrent network from an IoT journal, and a time-series mixer from a 2025 conference.
Below it the table becomes exactly what you would hope for: model, type, a link per supported task pointing straight at a runnable example file, and the venue it was published in. The examples are organised by task in the repository, one directory each for imputation, forecasting, classification, clustering and anomaly detection, so the links land somewhere coherent.
The waitlist row is the one to be aware of, and it is worth knowing which row you are looking at before you plan a dependency on it.
Hyperparameter tuning changes frameworks at the next major version
Since version 0.2, every neural-network model in the package has had hyperparameter optimisation through Microsoft's NNI. That sentence ends with a condition: until version 2.0.
In version 2 the functionality is reimplemented on the Optuna framework instead. So the project is in the middle of a swap, with the current release still on the older tool, and the configuration you write today is written against a framework that the next major version replaces.
The other half of that note is a pointer away from this repository. For how to configure and tune the hyperparameters, the reader is sent to a survey and benchmark repository maintained by the same author, a separate project with its own name and its own contents.
That is a reasonable division. A tuning guide that had to live in the same repository as fifty implementations would rot faster than the implementations do. But it does mean the package's headline capability, automatic tuning for every neural model, is documented somewhere you have to go and find, and implemented with a tool whose replacement is already scheduled.
The version and the dependency pins both come from files outside the packaging file
The packaging metadata is unusual in a way worth understanding before you install anything:
dynamic = ["version", "readme", "dependencies", "optional-dependencies"]
license = { file = "LICENSE" }
requires-python = ">=3.9"
Four of the project's fields are not written in that file at all. The version, the long description, the dependency list and the optional dependency list are all computed, which means they are read from somewhere else, and the tree has a directory whose name says where.
So the Python floor is 3.9, with classifiers for 3.9 through 3.13, and the dependencies that actually constrain it are in another file. The project is aware this is a problem for users, because one of the badges in the readme links to a documentation section whose anchor is a phrase about the reasons for version limitations on dependencies. It is a named page rather than a line in a changelog.
That is the right way to handle it, and it is also a sign of how much of the difficulty here comes from the machine-learning stack rather than from the missing-data problem the library exists to solve.
The coverage badge points at a branch that is not the default one
The badge row is long, and two entries in it are about the project's own quality gates rather than about the package. One links to a SonarCloud component page for a quality rating with a list view. Another links to a coveralls page with a query parameter setting the branch to something called full_test.
A coverage badge on a branch other than the default one is not an error. It is a deliberate choice to report the number from a run that is not the one most people see. But it does mean the percentage in the badge is not the percentage on the code you are reading, and if you are deciding whether to depend on a project you have to work out which one you are being shown.
The rest of the tooling is more conventional and tells you how the project is developed. A coverage configuration file, a pre-commit configuration, a development container definition, a workflow directory, a test directory, a scripts directory and a docker directory. The examples are the part that is unusual in scale, with one runnable file per model per task, all linked from the catalogue.
The package installs a command that the readme does not mention
There is a console entry point:
[project.scripts]
pypots-cli = "pypots.cli.pypots_cli:main"
So installing the package puts a command on your path. Nothing in the visible part of the readme refers to it. The readme has its own table of contents near the top, listing the available algorithms, an ecosystem section, installation, usage, citing, contribution and community, and none of those seven entries covers a command line.
It is a small thing, and small omissions in a long readme are normal. But this one is worth a line because it changes what you expect after installing. A console script implies a supported interface with arguments, output formats and an exit behaviour, and none of that is described anywhere the reader is pointed to.
If you want the library, use the import path and the example files. If you want the command, the entry point tells you it exists and nothing else does.
Releases are named after papers, so a two-year-old paper arrives as a version bump
The three most recent releases carry emoji and a subject in the title. Version 1.3, dated 2026-03-26, is titled as adding one model, TKAN. Version 1.4, dated 2026-04-27, is titled as a bug fix. Version 1.5, dated 2026-05-05, is titled as the release for a model called HELIX.
TKAN is a 2024 paper. It arrived in this package in March 2026. HELIX, which sits at the top of the catalogue as a 2026 conference paper, arrived in May 2026. So inclusion lags publication by anywhere from a few months to two years, and the release notes are the record of that lag, because they are named for the paper rather than for the change.
The project's own positioning is modest in a way worth noting. It says the area of machine learning on partially-observed time series still lacks a dedicated toolkit, and that this one exists to fill that gap, and it spells out the pronunciation because the name cannot be read aloud unambiguously. It also names four intended audiences in its classifiers, including the healthcare industry, which is the one that tells you what the real deployments look like.
None of which changes the fact that about fifty models in one interface is the point.
Editorial conclusion
PyPOTS earns its place if your problem is gaps rather than noise, because five task types behind one interface with one consistent example layout per model is more than most single-paper codebases give you. Read the marks in the catalogue before you choose a model, because the ones that need the embedding workaround are the ones whose original papers said nothing about missing data, and that is a different claim from the ones built for it. Two practical notes. Hyperparameter tuning changes frameworks at the next major version, so a script written against the current release will need editing. And the dependency floor is 3.9 with classifiers up to 3.13, which the project itself links to a page explaining why its dependencies force the limits, so read that before you pin an environment.
Frequently asked questions
What is PyPOTS used for?
Machine learning on multivariate partially-observed time series with missing values. It covers five task types, imputation, forecasting, classification, clustering and anomaly detection, and also provides a model for time series representation learning and vectorisation.
Why does the PyPOTS catalogue mark some models?
Because those models were not originally proposed for data with missing values, so they cannot accept a gapped series as input. To make them applicable, PyPOTS applies an embedding strategy and training approach, described as orthogonal embedding with masked interpolation training, the same pair used in the SAITS paper.
Which Python versions does PyPOTS support?
The packaging metadata requires Python 3.9 or newer, with classifiers for 3.9 through 3.13. The dependency list is not written in the packaging file but computed from another location, and the readme links to a documentation section about the reasons for version limitations on dependencies.
How does PyPOTS do hyperparameter optimisation?
Through Microsoft's NNI from version 0.2 onwards, with the feature scheduled to be reimplemented on Optuna in version 2.0. The current release is version 1.5, so a configuration written today targets the framework the next major version replaces. Guidance on tuning is in a separate survey and benchmark repository.
Does PyPOTS install a command line tool?
The package declares a console script, so installing it puts a command on your path. The readme's table of contents does not include a section on it, and no arguments or output format for it are described in the visible documentation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wenjiedu-pypots)Star history chart for your README
[](https://hysenlabs.com/projects/wenjiedu-pypots)Was this useful?