Yuxi puts RAG, Neo4j graphs and sandboxed agents in one self-hosted stack, and 0.8 starts from a clean slate
Yuxi: a self-hostable, multi-tenant knowledge agent platform unifying RAG, knowledge graphs, multi-agent workflows, MCP/Skills, sandboxing and permission management.
At a glance
- What is it?
- Yuxi is an MIT-licensed, multi-tenant knowledge agent platform from xerrors that runs on Docker Compose with Milvus, Neo4j, Postgres, Redis and MinIO behind it. The 0.8 line is a fresh-install-only beta, its default container sandbox shares the host kernel, and several compose defaults need changing before anyone else can reach the box.
- Who is it for?
- Yuxi suits teams that want to own their data, models and permissions and are willing to operate a multi-service Docker stack in exchange for RAG, knowledge graphs, sub-agents, Skills and MCP under one permission model. It is the wrong choice for anyone who needs to upgrade an existing 0.7 deployment in place, or who wants to run untrusted multi-tenant code on the default container sandbox.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
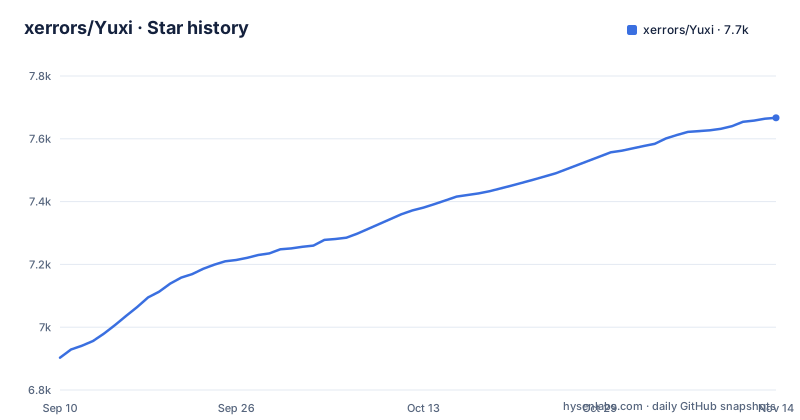
- xerrors/Yuxi7,664 ★ · +761
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| xerrors/Yuxi | 6.9k | 7.7k |
761 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One workspace for retrieval, graphs and agents, scoped by user and department
Yuxi describes itself as Cloud Agents plus Knowledge RAG: a privately deployable, multi-tenant platform where every user gets something like a cloud Codex. It pulls knowledge base retrieval, knowledge graphs, LangGraph multi-agent orchestration, MCP and Skills, sandboxed tools and permission management into a single workspace. Access is managed per user, per department and by sharing scope, and that scoping applies to knowledge bases, agents, Skills and models alike. The backend is Python, with backend/, frontend/ and packages/ directories in the repository and a docs/ tree that covers a CLI for logging in, chatting, sending attachments and querying knowledge bases, plus a public Agent API for external applications to create sessions, submit messages and read results. The main README is in Chinese, with README.en.md alongside it. The audience is explicit: teams that need a self-deployed multi-user agent product and want to control their own data, models and permissions.
Version 0.8 will not upgrade an existing installation
The most consequential line in the quick start is about upgrades. The 0.8 series is intended only for fresh deployments, and old databases, indexes and file layouts are not automatically upgraded. The advice is to trial it with a separate data directory, with details in docs/develop-guides/releases/0.8.0.md. The latest stable release is v0.7.2, published on 2026-09-02, while the newest entry on the releases page is v0.8.0.beta5 from 2026-10-28, and the quick start itself pins the tag v0.8.0.beta7. The last push to the repository was on 2026-11-02. For a team already running 0.7.2 with indexed knowledge bases, this means 0.8 is a parallel install, not an upgrade: plan to re-ingest documents and rebuild graphs, or stay on 0.7.2 until a migration path appears. The Makefile reinforces the separation, since make reset refuses to delete an external YUXI_STATE_DIR and asks you to remove that exact state directory yourself.
init.sh generates the secrets that docker-compose.yml refuses to start without
Setup needs Git, Docker Engine, Docker Compose v2 and a working LLM API. On macOS and Windows, Docker Desktop must run in Linux container mode with the project directory shared. The quick start clones the beta tag and runs the init script:
git clone --branch v0.8.0.beta7 --depth 1 https://github.com/xerrors/Yuxi.git
cd Yuxi
./scripts/init.sh
On Windows the equivalent is .\scripts\init.ps1 in PowerShell. The script prompts for a SiliconFlow API key, generates the application secret, the runner authentication key and an instance identifier, and prepares base images; other model providers are configured after login. This step is not optional. docker-compose.yml marks JWT_SECRET_KEY, YUXI_INSTANCE_ID and API_KEY_DERIVATION_SECRET as required and stops with a message telling you to rerun bash scripts/init.sh if any is missing. If an .env already exists, its keys are kept. Then start and verify:
docker compose --profile container config --quiet
docker compose --profile container up --build -ddocker compose --profile container ps
curl --fail http://localhost:5050/api/system/readyOnce status reads ready, the UI is at http://localhost:5173, where you initialize the super administrator, and API docs sit at http://localhost:5050/docs.
The default container sandbox shares the host kernel
Yuxi starts with the Container sandbox by default. Each agent execution runs in its own temporary container managed by a separate runner, working directory files persist, and no KVM node is needed. The container profile builds the sandbox image and starts that runner, and the sandbox has no network access by default, as covered in docs/advanced/container-sandbox.md. The limitation is stated plainly: Container mode suits local trials and trusted single-tenant code because it shares the host kernel. If you need VM isolation or persistent per-user environments, you have to choose Cube during setup and prepare Linux execution nodes with KVM. Switching to Container on an existing install means setting SANDBOX_BACKEND=container and rerunning initialization. The consequence for a multi-tenant deployment is direct: the platform is sold as multi-tenant, but the sandbox you get out of the box is not the one to hand to users whose code you do not trust. Budget for KVM-capable Linux hosts if that is your situation.
Compose defaults ship with known passwords for Neo4j, MinIO and Postgres
The shared environment block in docker-compose.yml fills in defaults for every backing service. Postgres falls back to user postgres and password postgres on database yuxi. Neo4j defaults to user neo4j with password 0123456789 at bolt://graph:7687. MinIO uses minioadmin for both access key and secret key. Milvus is at http://milvus:19530 with an empty token, and Redis at redis://redis:6379/0. These values are convenient for a laptop trial and dangerous anywhere else, because they are public in the repository. Before exposing a deployment beyond localhost, set POSTGRES_PASSWORD, NEO4J_PASSWORD, MINIO_ACCESS_KEY and MINIO_SECRET_KEY in .env. A docker-compose.prod.yml sits next to the development file, and the compose file sets YUXI_ENV to development, so read both before going to production. There is also a docker-compose.no-knowledge.yml, and the YUXI_KNOWLEDGE_ENABLED variable defaults to true, for deployments that do not need the knowledge stack.
Knowledge graphs are built on request, not when documents are parsed
The knowledge pipeline parses PDF, Word, PPT, Excel and Markdown files. It connects to MinerU and PaddleOCR cloud services and optionally a self-hosted MinerU, keeps the lightweight RapidOCR, and splits text, images and tables into chunks for vector indexing. Besides local vector knowledge bases, it can connect to external services such as Dify and Notion through a unified retriever. A retrieval test bench shows embedding scores, hybrid results and how rerank changes them. Graph construction is a separate step. An administrator submits a build job against already indexed Milvus chunks, and the system runs entity and relation extraction and writes the results to Neo4j. It does not trigger automatically when a document is parsed, so a freshly uploaded document is searchable but absent from the graph until someone runs that job. Evaluation has a similar boundary: retrieval and RAG answer quality can be evaluated in the product, while full agent evaluation has to be built yourself on the public API, per docs/agents/agent-evaluation.md.
Default approval mode only gates commands and writes outside the Project
Agents combine a model, prompts, mounted knowledge bases, tools, MCP servers and sub-agents. A main agent plans and hands parts of a task to multiple SubAgents that run asynchronously in parallel, then gathers their results. Skills can be installed online from skills.sh and from the ModelScope community, edited in the browser, and given permissions and dependencies, with tools loaded on demand through progressive disclosure. Human approval is the safety valve, and its scope is narrow. The default mode asks for confirmation before command execution and before file writes outside the current Project; writes inside the Project are approved automatically. Full trust mode asks for nothing. That means an agent can overwrite anything in its own Project without a prompt, so keep important source files outside it or under version control. Results land in a sandbox workspace where Markdown, HTML, charts, PDFs and code can be previewed in the browser and downloaded as a bundle.
Editorial conclusion
Yuxi suits teams that want to own their data, models and permissions and are willing to operate a multi-service Docker stack in exchange for RAG, knowledge graphs, sub-agents, Skills and MCP under one permission model. It is the wrong choice for anyone who needs to upgrade an existing 0.7 deployment in place, or who wants to run untrusted multi-tenant code on the default container sandbox. Before adopting it, decide between Container and Cube isolation, replace the default Neo4j, MinIO and Postgres credentials, and test 0.8 against a separate data directory.
Frequently asked questions
What do I need to run Yuxi locally?
Yuxi needs Git, Docker Engine, Docker Compose v2 and a working LLM API; the init script asks for a SiliconFlow API key. On macOS and Windows, Docker Desktop must use Linux container mode with the project directory shared.
Can I upgrade an existing Yuxi deployment to 0.8?
No. Yuxi 0.8 is for fresh deployments only, and old databases, indexes and file layouts are not upgraded automatically. Trial it with a separate data directory.
Does the Yuxi sandbox isolate untrusted agent code?
The default Container sandbox shares the host kernel and suits local trials and trusted single-tenant code, with networking disabled by default. For VM isolation, choose Cube and prepare Linux execution nodes with KVM.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xerrors-yuxi)Star history chart for your README
[](https://hysenlabs.com/projects/xerrors-yuxi)Was this useful?