xiaozhi-esp32-server: two deployment shapes, and a README that says not to use it in production
xiaozhi-esp32 ESP32 Backend service for xiaozhi-esp32, helps you quickly build an ESP32 device control server.
At a glance
- What is it?
- This is the backend for the xiaozhi-esp32 hardware project, written in Python, Java and Vue, with MQTT+UDP and WebSocket transports, voiceprint recognition, an MCP access point and a RAGFlow knowledge base. It ships a minimal install that needs no database and a full install that does, and its own documentation says the code is incomplete, untested for security, and not for production.
- Who is it for?
- Use it if you already own ESP32 hardware, have already connected a device once, and want your own control of the backend. Start with the minimal install and the all-free configuration to see whether the pipeline suits you before paying for streaming APIs.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
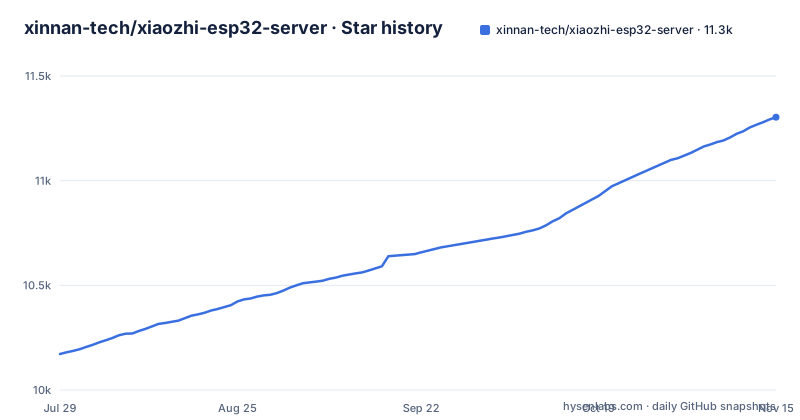
- xinnan-tech/xiaozhi-esp32-server11,303 ★ · +1,131
| Repository | 2026-07-29 | 2026-11-15 |
|---|---|---|
| xinnan-tech/xiaozhi-esp32-server | 10.2k | 11.3k |
1,131 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Minimal install keeps state in a config file, full install needs a database
The deployment choice is really a choice about persistence and hardware, and the documentation puts it in a table. The minimal path covers smart dialogue and single-agent management, stores its data in configuration files with no database at all, and is documented for both Docker and source deployment. The full module path adds multi-user management, multi-agent management and a console UI you operate from a browser, and moves the data into a database. The stated resource note for both installs is that running FunASR locally is memory-hungry, while routing everything through APIs keeps resource use low; the full install also needs database resources. That FunASR line is the one to notice. A third option exists for the full install only: source deployment with an automatic update tutorial. The audience is stated too. This is for people who have already bought ESP32 hardware, already connected a device successfully to the hosted backend, and now want to run their own. For the first-time hardware buyer, this repository is the wrong starting point.
The warning section says the code is unfinished and has no security assessment
Two warnings sit near the top of the documentation, and both are load bearing for anyone planning a deployment. The first is about money and third parties. The project states that it has no commercial relationship with any third-party API provider, naming speech recognition, large language models and speech synthesis among them, and that it offers no guarantee of their service quality or the safety of funds paid to them. It recommends choosing providers that hold the relevant business licences and reading their agreements and privacy policies, and states plainly that the software itself does not hold account keys, does not touch money, and does not carry the risk of top-up losses. The second warning is shorter and more direct: the project says its functionality is not complete, that it has not passed a cybersecurity assessment, that you should not use it in a production environment, and that anyone deploying it on a public network must take the necessary precautions. The practical reading for a reader is a separation of concerns: this repository handles device transport, agent orchestration and the console, while speech, models and synthesis sit behind keys you supply to third-party services whose behaviour it cannot vouch for.
Streaming swaps four components and buys about 2.5 seconds of latency
Two configuration plans are offered, and the table between them is the fastest way to understand the architecture. The free entry configuration targets personal home use with every component on a free option: FunASR for speech recognition running locally, glm-4-flash from Zhipu for the language model, glm-4v-flash for the vision model, and EdgeTTS from Microsoft for synthesis. The streaming configuration targets demos, training, and anything with more than two concurrent sessions, and swaps each of those for a streaming variant: XunfeiStreamASR, qwen-flash from Alibaba Bailian, qwen3.5-flash, and HuoshanDoubleStreamTTS from Volcano. Two rows do not change. Intent recognition is function calling in both, and memory is mem_local_short, local short-term memory, in both. Streaming arrived in version 0.5.2, and the stated improvement in response speed is about 2.5 seconds, which is the difference between a device that feels broken and one that answers. If you care where the time goes, the project points to a separate performance research repository with a methodology you can re-run in your own environment. The tradeoff is straightforward: streaming means paid API keys, the free plan means a local FunASR process eating your RAM.
Two test tools, and the model tester only measures the keys you supplied
Two diagnostic entry points ship with the project, both local, and the second one has a condition worth reading before you trust a number it prints. The audio interaction test tool lives at main/digital-human/index.html. You run start.py inside main/digital-human and then open the page:
python start.pyhttp://127.0.0.1:8006/index.htmlThat tool checks audio playback and capture, which is the point where a voice device usually fails: playback works but nothing is captured, or capture works but the device never hears the reply. The second tool is the model response tester at main/xiaozhi-server/performance_tester.py:
python performance_tester.pyIt measures response speed for the core modules, the ASR, the LLM, the vision model and the TTS. The condition: only models for which you have configured keys are tested. That is a small line with a large effect on interpretation, because an unconfigured module does not report as slow or fast, it simply does not appear, so a fast result across three rows tells you nothing about the fourth. Separately, the project publishes a shared test platform for people who want to try a build before flashing hardware, with concurrency of 6 and data cleared daily, plus console, H5 console, service test tool, OTA endpoint and WebSocket endpoint addresses.
make test runs pytest, maven and npm across three separate subprojects
The repository root is small and the whole build story is in the file list and one Makefile. You get three Dockerfiles, Dockerfile-server-base, Dockerfile-server and Dockerfile-web, a docker-setup.sh, a docs/ directory and main/, where the application actually lives. The main directory splits into three codebases, one per language, and the Makefile drives all three test suites:
test-python:
	cd main/xiaozhi-server && python -m pytest -x -q

test-java:
	cd main/manager-api && mvn -B -q test -DfailIfNoTests=false

test-web:
	cd main/manager-web && npm ci --no-audit --no-fund && npm test
main/xiaozhi-server is the Python side that talks to devices, main/manager-api is the Java management API built with Maven, and main/manager-web is the Vue console built with npm. make test is an alias for test-fast, which chains all three. Two details in those lines are practical. The Python run uses -x so it stops at the first failure, which is right for a local loop and wrong for a full report. The Maven run passes -DfailIfNoTests=false, so a module with no tests is not treated as a failure. For a contributor this Makefile is the fastest way to learn the layout, because the three directory names tell you which language owns which responsibility before you read a line of application code.
Tool calling arrives in five shapes, and memory has three backends
The feature list is where this project stops being a relay and starts being a platform, and two rows are worth reading closely. Tool calling supports the client IOT protocol, the client MCP protocol and the server MCP protocol, and the README header also lists an MCP access point. Memory has three backends, local short-term memory, a mem0ai interface, and PowerMem, plus summarization. The knowledge base row is the most interesting architecturally: it supports a RAGFlow knowledge base where the large language model itself decides whether the knowledge base needs to be consulted before answering, rather than retrieval running unconditionally on every turn. Voiceprint recognition runs in parallel with ASR and passes the identified speaker to the model for a personalized reply, which is why multi-user management is a feature of the full install rather than a detail.
Versions moved three times in a quarter, so pin one before you deploy
The release history is short and fast. Three tags appear in the recent list: v0.9.6 dated 2026-07-24, v0.9.7 dated 2026-09-29 and v0.9.8 dated 2026-10-23, and the last push to the default branch is dated 2026-11-02. The project is not archived, the license is MIT, and the homepage is xiaozhi.biz. Three releases inside three months on a 0.x version is a signal about stability rather than about neglect: features and breaking configuration changes are expected to arrive mid-stream, which is consistent with a documentation page that states the functionality is incomplete. The second thing to pin is not the code but your provider choices, because the two configuration plans name specific commercial models, glm-4-flash and qwen-flash among them, and vendors rename and retire model identifiers. A deployment that worked last month can fail today with an authentication or model-not-found error that has nothing to do with your server. Record the version tag and the model names you configured, and expect to revisit both. The documentation structure supports this: separate deployment guides for the minimal and full paths, an FAQ page, an MQTT gateway integration document and a dev-ops integration document for automated source updates.
Editorial conclusion
Use it if you already own ESP32 hardware, have already connected a device once, and want your own control of the backend. Start with the minimal install and the all-free configuration to see whether the pipeline suits you before paying for streaming APIs. Do not expose it to the internet as a production service, because the project itself states it is unfinished and has not passed a security assessment, and decide early who pays for the third-party ASR, LLM and TTS keys.
Frequently asked questions
How much server does xiaozhi-esp32-server need?
The minimal install stores data in config files and needs no database. Running FunASR locally is memory-hungry, while sending everything through external APIs keeps resource use low. The full module install, with multi-user management and a database, additionally needs database resources.
Can I run xiaozhi-esp32-server in production?
The project's own warning says not to. It states that the functionality is incomplete, that it has not passed a cybersecurity assessment, that it should not be used in a production environment, and that anyone deploying it on a public network must take the necessary precautions.
Which models does xiaozhi-esp32-server use for ASR, LLM and TTS?
The free entry configuration pairs FunASR locally with glm-4-flash, glm-4v-flash and EdgeTTS. The streaming configuration swaps in XunfeiStreamASR, qwen-flash, qwen3.5-flash and HuoshanDoubleStreamTTS, and streaming support arrived in version 0.5.2 with about 2.5 seconds of response speed gained over earlier versions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xinnan-tech-xiaozhi-esp32-server)Star history chart for your README
[](https://hysenlabs.com/projects/xinnan-tech-xiaozhi-esp32-server)Was this useful?