Hack-skills publishes its ZIP password next to the ZIP and ships no releases to audit against
Helping AI Agent become an awesome practical hacker!
At a glance
- What is it?
- An agent knowledge base of 102 security skills in 102 markdown files, layered as one master entry, six categories and on-demand deep topics, with a three-layer loader designed around context budget and a client-side search that can filter by line count.
- Who is it for?
- The structure here is the interesting part and it transfers to any agent knowledge base: route from one file, fetch topic files only when needed, and give the agent a way to find a file by how long it is. What to check before trusting it is provenance.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 62 days ago.
- What is it written in?
- Mainly CSS, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
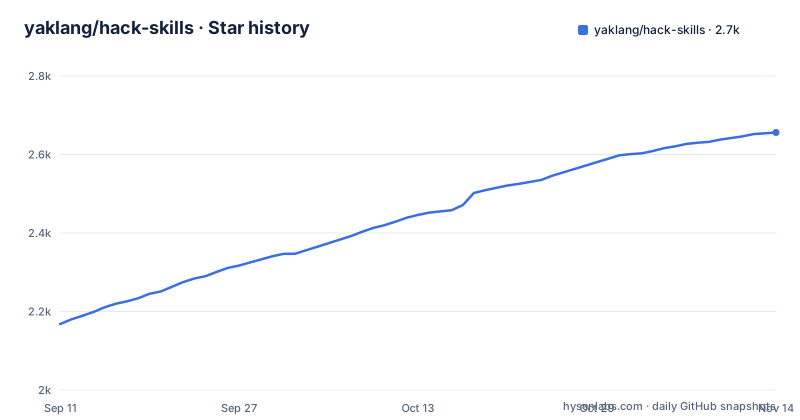
- yaklang/hack-skills2,656 ★ · +488
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| yaklang/hack-skills | 2.2k | 2.7k |
488 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A hundred markdown files the platform labels as CSS
The repository's language label says CSS. The repository is a hundred and two markdown files.
The reason is the second directory at the root. There is a static site, and the README says it is a fully client-side build with no backend and no tracking, deployed by a workflow in the repository's own automation directory. A client-side search interface is where the stylesheet count comes from, and it is the largest single component by language volume even though it is not what anyone installs.
The rest of the root is small and says what the project is. A skills directory holding the knowledge base, the site, an assets directory, a scripts directory that presumably builds whatever the site consumes, a licence, a gitignore, and two readmes, one English and one Chinese, with a language switch in the corner.
That is the whole thing. There is no package manifest for the skills, no build step described for them, and no code. Every skill is one markdown file in its own directory, named by a semantic identifier rather than by a number, following one uniform filename.
So a reader deciding whether to use this is really deciding about prose. The tooling is a viewer and a downloader, and the content is the product.
The offline bundle is encrypted and the password is printed beside it
The distribution section describes three channels, and the third one is the interesting one.
The web interface gives you fuzzy search, a category sidebar, a priority tier filter, copy-paste install commands and an encrypted archive download. The repository gives you the markdown. The archive gives you every markdown file in one shot, for what the README calls air-gapped use.
Now the reason it is encrypted, which the same table gives: the target environment may have no internet, and endpoint security tooling there strips plain markdown files. So the bundle is compressed and then encrypted with a standard cipher, and the password for it is printed in the diagram that describes the download, in the same diagram that shows the website.
That is worth understanding rather than judging. The threat being addressed is a scanner, not a reader. A scanner that flags or removes text files can be defeated by an opaque container, and a reader who has the password is not the adversary in that model. Publishing the password costs nothing because secrecy was never the property being bought.
What it does mean is that the encryption buys you nothing against anyone who can run the tool, and it adds a step: a password to distribute to the people who need the offline copy. If you are deploying this into an environment with endpoint security, you would need to know whether your tooling blocks the archive too, and the page does not say.
Seven sources with seven distillation claims and no upstream licence
This is the section that decides whether the project is usable, and it is the one most worth reading carefully.
There is a table with seven rows of sources. Six are named public security repositories, and the seventh is a category covering public research papers and advisories. For each one the table has two columns beyond the name: what the source provides, and how the project used it.
The transformations are specific. One source's sixty-four vulnerability categories and payload families become scenario-based indices and method matrices with sections broken out per engine and per database. A payload dictionary source becomes parameter naming patterns, endpoint frequency tables and middleware fingerprint matrices. A bypass-technique source becomes bypass pattern matrices, cloud metadata endpoint tables and web application firewall vendor sections. A CTF source becomes technique sections including handler bypass and a specific framework's PIN trick. A competitive write-up source becomes binary exploitation, cryptography attack, reverse engineering, steganography and traffic analysis skills. And the encyclopedia source becomes operating-system privilege escalation playbooks, directory service attack chains, mobile checklists, container escape techniques and pivoting strategies.
Below the table are four processing principles, and the first is that no large dictionaries or full payload lists are copied directly. The others say to prioritise routable, composable, auditable skills, to use small stable samples with cross-references so an agent behaves consistently, and to include no customer-specific information and no vendor-identifiable case detail.
What is not there is any licence or attribution for the six upstream repositories. The table names them and describes the distillation, which is more than most derived knowledge bases do, and it still does not tell you whether the terms of those sources permit redistribution of derivative work.
Three layers because a hundred and two files would not fit
The loader design is the part of this project worth copying, and the reason for it is stated plainly.
The design goal sentence says it directly: the goal is not to expose every minor tip as an entry point, but to compress what the loader truly needs to see into one master entry, six category entries, and deep topic skills that get pulled on demand.
So the hierarchy has three levels with different exposure rules, given in a table with a column for recommended exposure. The master entry is for global routing, operating doctrine, test sequencing and switching between categories, and it is marked expose first. The category entries route by attack surface to stable topic families, also marked expose first. The deep topic skills contain the complete playbooks and execution detail, and they are marked load on demand.
Read as a context-budget design, it is the obvious answer to a problem most agent knowledge bases have wrong. If an agent loads a hundred and two documents it either exceeds its window or silently drops most of them. Loading one routing file plus six category files, and fetching a playbook only when a topic comes up, keeps the always-on cost near seven files.
One wrinkle. The intro claims coverage across fourteen security domains, while the routing layer has six category entries, and the ones named are attack surfaces rather than topics: one for reconnaissance, one for API security, one for authentication. So the taxonomy has two independent axes, a domain list and a surface list, and the master entry is the only place they are reconciled. Which means the question of whether every domain is reachable through some category is answered by that one file rather than by the directory structure.
Search can filter by line count, which is the giveaway
The search interface takes field qualifiers, and three of them are the most informative thing on the page.
You can search and restrict results to a category, restrict to a depth tier, and restrict to files above a line count. That last one is not a text-search feature. It is a way to ask how much context a skill will cost before loading it.
Combined with the tier filter in the interface, which offers three priority levels, you have the two things an agent actually needs when it decides what to read: how relevant is this file, and how expensive will it be once I have it. A hundred words versus two thousand is a different decision from a different tier.
The index itself is described as weighted and fuzzy across four fields, name, identifier, category and description, which is a sensible weighting for a corpus where the identifier is the most precise field and the description the least.
So the site is not a documentation browser with a search box. It is a selection tool with a rendering mode. That is a small design decision with a large effect on whether an agent using this knowledge base is useful or thrashing, and it is the part of this project I would point at first.
Three channels kept in sync on every push, and no version to sync them to
The repository has no releases.
Not old ones and not none-yet: none. There is no changelog file in the tree either. The README says the three channels are kept in sync on every push to the default branch. A Git clone still has a commit identifier that can be recorded to identify the exact revision.
That statement is the whole versioning story, and it has a consequence for anyone trying to use this responsibly. If you clone, you get whatever the tip is. If you download the archive, you get whatever the tip was when the build ran. Without a release, a team can pin and compare Git commit hashes, but must separately record which commit produced a downloaded archive to compare that copy reliably.
The stated objective of the project is to organise security knowledge that is easy to audit and maintain. That objective and the absence of releases are in tension. An auditable corpus needs identifiable snapshots; commit hashes provide them for Git checkouts, while downloaded bundles need a recorded revision.
The fix is small and entirely conventional: tag a release when the content set changes materially, and put a note in the master entry saying which release it belongs to. Then the audit trail exists and the three channels have something to be synchronised against.
The install is an unpinned installer or one raw file URL
The quick start gives two ways in, and they are quite different in what they assume.
The preferred one is a package installer invoked against the repository name, with no version:
npx skills add yaklang/hack-skillsThat fetches the current default branch and installs it into whatever agent runtime is on the machine. The site offers the same command as a copy-paste button, which is a nice touch, and it also means the thing people paste is a program fetched from a repository at run time.
The alternative is for tooling that can pull a single file: the README gives the name declared in the master entry's front matter and a raw URL pointing directly at that one markdown file. That route is auditable, because you can read the file before you run it, and it is also the one that gives an agent exactly the routing file with none of the hundred other files.
That second route is arguably the better default and it is listed second. An agent that only needs the master entry plus six category entries does not need an installer at all; it needs six URLs.
The readme then gives the intended reading order after installation, which is simply the hierarchy again: start at the master entry, move into category entries, and drill into deep topics only then. Everything in the repository is consistent about that order, which is unusual and makes the structure easy to adopt.
Editorial conclusion
The structure here is the interesting part and it transfers to any agent knowledge base: route from one file, fetch topic files only when needed, and give the agent a way to find a file by how long it is. What to check before trusting it is provenance. Seven upstream sources are named with a distillation described for each, which is unusual and good, but no upstream licence is named and there is no release or changelog to audit a specific snapshot against.
Frequently asked questions
What is yaklang hack-skills?
An MIT-licensed knowledge base of 102 agent skills across 14 security domains, covering web, API, authentication, privilege escalation on three operating systems, directory service attacks, mobile, binary exploitation, reverse engineering, cryptography, blockchain, AI security, network protocols and digital forensics. It is intended for bug bounty work, penetration testing, competitions and authorized research.
How do I install hack-skills?
The preferred route is a package installer invoked against the repository name with no version pinned. The alternative, for tooling that can pull a single file, is to fetch the master entry's markdown by its raw URL, which lets you read the file before installing anything.
What is in the hack-skills archive download and why is it encrypted?
It is every markdown file in one download, for machines with no internet. It is encrypted with a standard cipher and the password is published in the same diagram, because the stated reason is that endpoint security tooling on the target strips plain markdown files, not that the content needs to be secret.
Where does hack-skills get its content from?
Six named public security repositories plus public research papers and advisories. A table gives the distillation applied to each source, and the stated principles say no large dictionaries or full payload lists are copied directly. No upstream licence or attribution is named in that table.
How is hack-skills organised for an agent to load?
In three layers with different exposure: one master entry for global routing, six category entries that route by attack surface, and deep topic skills containing full playbooks that are loaded on demand. The web search can filter by tier and by line count, so an agent can weigh relevance against context cost.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yaklang-hack-skills)Star history chart for your README
[](https://hysenlabs.com/projects/yaklang-hack-skills)Was this useful?