perforator: an eBPF profiler with a GPL agent, x86 only, and no build command in the readme
Perforator is a cluster-wide continuous profiling tool designed for large data centers
At a glance
- What is it?
- An eBPF profiler that samples kernel and user stacks across a fleet, stores the binaries centrally so it can unwind without frame pointers on the host, and feeds profile-guided optimisation builds. It is Apache-2.0 with GPL-2.0 parts, x86 64-bit Linux only, and it needs an organisation-specific build system to compile.
- Who is it for?
- Use it if your fleet is large enough that sampling one process at a time is not an option, and if you have somewhere to keep the binaries that the collector reads symbols from, because that is the design, not an implementation detail. Three things to check first.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
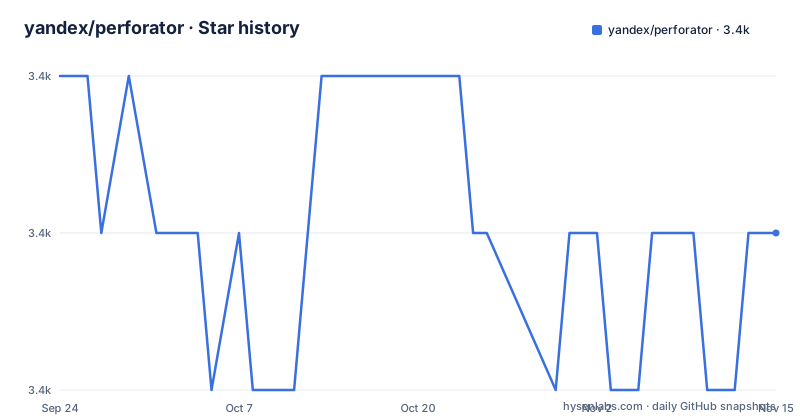
- yandex/perforator3,436 ★ · -1
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| yandex/perforator | 3.4k | 3.4k |
-1 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The same samples feed a compiler, not just a flamegraph
Most profilers answer one question, which is where the time went. This one has a second output that is worth understanding before you deploy it. One of the six listed features is the generation of optimised-profile data for building applications with profile-guided optimisation, using a compiler tool that automates the process. That means the same collection that produces a flamegraph can be turned into an input to a build. The mechanism is the interesting part: profile-guided optimisation changes what the compiler inlines and how it lays out code based on observed execution, and the observed execution here comes from production rather than from a benchmark run, so the compiler is optimising for the traffic you actually serve. The generator is named in the readme as a separate project, so the profiler produces the artifact and another tool consumes it.
Three different licence statements, one of which is in the metadata
The licence paragraph is precise, and the metadata disagrees with it. The readme says the project is licensed under Apache 2.0, then immediately carves out parts under GPL 2.0 and names them: the eBPF program source under the collector's unwinder directory, and the portions of the OpenJDK profiling support inside the language bindings. Two separate licence files are linked to back this up, one at the root and one inside the unwinder directory. What the repository's own metadata records is not a licence at all but an unresolved value, so a tool reading the repository rather than the readme gets nothing. Three sources, one of which names two licences and one of which says nothing, is the arrangement a distributor has to reconcile before packaging.
The GPL portion is the part that runs on your machines
The carve-out is not decorative, because of where the two licences sit. The GPL-2.0 parts are the eBPF programs that do the sampling and the Java profiling support, and the eBPF programs are the collector that loads onto every host you profile. The Apache-2.0 remainder is the storage, the query language and the interface, which are the parts that run centrally. So for an operator the licence that matters operationally is the copyleft one, sitting on the component with kernel-level access to the machine, while the component you interact with is permissively licensed. Nothing in the readme draws that distinction or explains why the two were split, and for anyone building an internal distribution of the collector that omission is the gap that matters.
Building it requires a build system the readme never invokes
The source build instructions are a link, and the tree shows what is on the other side of it. The root carries a file marking the directory as a root for a monorepo build, a build configuration file, a driver script for that build tool, and two metadata files whose names belong to internal tooling rather than to anything documented. There is also a committed vendor directory, so third-party code is in the tree rather than resolved. The project is also not one language: the primary language is recorded as C++, and there is a Go module at the root with its own statement and its own long dependency list. So a source build is a multi-language build driven by an organisation-specific tool, and the one piece of information a newcomer would want, the actual command, is the thing the readme does not contain.
Two kilobytes of hard numbers next to four adjectives
The resource requirements are the most concrete paragraph in the file, and they are worth quoting exactly because they contrast with the sentence above them. The tool runs on 64-bit x86 Linux, consumes 512 megabytes of memory, more than that on very large hosts with many processors, and less than one percent of host processors. Those are the kind of numbers an operator can plan against. The paragraph above them says production-ready, without affecting performance, and that it is deployed on tens of thousands of servers and has already helped many developers fix performance problems. None of that carries a measurement, a percentage, or a date. Both statements can be true at once, but only one of them can be checked by you before you install it.
There is no ARM build, and there are two Telegram channels
The architecture is stated once and it is the only architecture. Sixty-four bit x86 Linux is the entire supported platform, with no mention of ARM64, which excludes the processor-based instances that a growing share of fleets now run, and it excludes every developer on an Apple Silicon laptop from the server path. That constraint is not hidden, and it is not hedged either, which makes it easy to miss if you assume a profiler is portable. Elsewhere the same short file spends its links on two Telegram channels, one Russian and one English, a documentation site with a tutorial on profiling a laptop, a Helm chart for Kubernetes, and posts on two publishing platforms. The community surface is real; the platform surface is one.
The Go module requires a lint rule, a template engine and a full cloud client set
The module file is worth reading for what it implies about the deployment. It requires dozens of separate cloud client modules, one per service, covering compute, storage, big query, big table, artefact registry, asset inventory, batch, cloud build, binary authorisation, certificate manager and dozens more, plus a hosted protobuf module from a registry whose publisher name does not correspond to a public project. It also requires a TUI toolkit with several components, a YAML templating engine from a Kubernetes-adjacent project, and a library whose only purpose is checking for global variables in Go source, which is a lint rule. None of these can be doing kernel-level sampling. Read together, they say the central service has a console interface, is templated at deploy time, is linted through a dependency, and speaks to a managed cloud.
Version 0.1.0 shipped in February and nothing has been tagged since
The release list tells a short story. A 0.0.6 in July 2025, a 0.0.7 in November 2025, and a 0.1.0 in February 2026, which is the point where a pre-one project declares itself usable. The default branch was then pushed on 2026-10-04, roughly seven months after that release. So the readme's claim of production readiness and the repository's release history are describing different things: the branch a developer clones today is seven months of work past the newest tag, and the newest tag is itself a 0.1. Whatever the documentation says about stability, the versioning has not caught up with the deployment claim. Prebuilt binaries are offered alongside the source route, so which one you get is a choice about whether you are pinning a release or tracking a branch.
Editorial conclusion
Use it if your fleet is large enough that sampling one process at a time is not an option, and if you have somewhere to keep the binaries that the collector reads symbols from, because that is the design, not an implementation detail. Three things to check first. The licence is genuinely mixed, and the GPL-2.0 portion is the collector that runs on your hosts rather than some auxiliary tool, so the licence question attaches to the thing you deploy rather than to a library you link. The architecture is x86 64-bit Linux only, which excludes the ARM hosts that a growing share of fleets run on. And the source build depends on the build system this organisation uses internally, which the readme does not show you invoking, so read the build guide before budgeting an afternoon.
Frequently asked questions
what is perforator
Perforator is an open-source continuous profiling application for large data centres, built by Yandex and inspired by a published continuous-profiling infrastructure design. It collects kernel and user space stack samples with eBPF, stores profiles and binaries, and presents CPU usage through flamegraphs with a query language and a UI. It can also generate profiles for profile-guided optimisation builds.
What are the system requirements for Perforator?
64-bit x86 Linux only, consuming 512 megabytes of RAM, more on very large hosts with many CPUs, and under one percent of host CPUs. There is no ARM build listed. For anything beyond a laptop trial the documentation points at a Helm chart for deploying to a Kubernetes cluster, and the tree also carries a certificates directory and a committed vendor directory.
Which languages can Perforator profile?
C++, C, Go and Rust are supported, with Java and Python described as experimental. The Java support is also one of the two parts licensed under GPL 2.0 rather than Apache 2.0, alongside the eBPF program source in the collector's unwinder directory.
How does Perforator unwind stacks without debug symbols on the host?
It collects on the host and stores centrally: one of the listed features is scalable storage for both profiles and binaries, and another is unwinding without frame pointers or debug symbols present on the host. That combination is what allows sampling to happen on machines where the symbols are not, since the binaries are kept where the analysis runs instead.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yandex-perforator)Star history chart for your README
[](https://hysenlabs.com/projects/yandex-perforator)Was this useful?