kubeconform: the speed comparison skips 46 percent of the resources it validated
A FAST Kubernetes manifests validator, with support for Custom Resources!
At a glance
- What is it?
- A fast Kubernetes manifest validator whose documentation is unusually candid about its own limits, listing the server-side checks it cannot perform and pointing at the server-side dry run to fill the gap. Its headline benchmark shows nearly half the resources skipped, its default schema source is the maintainer's own fork of a community registry, and its release target hands a container both a publish token and the Docker socket.
- Who is it for?
- kubeconform fits a pipeline that wants a fast schema check on every commit and can run the server-side dry run alongside it. Four things to know.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 155 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
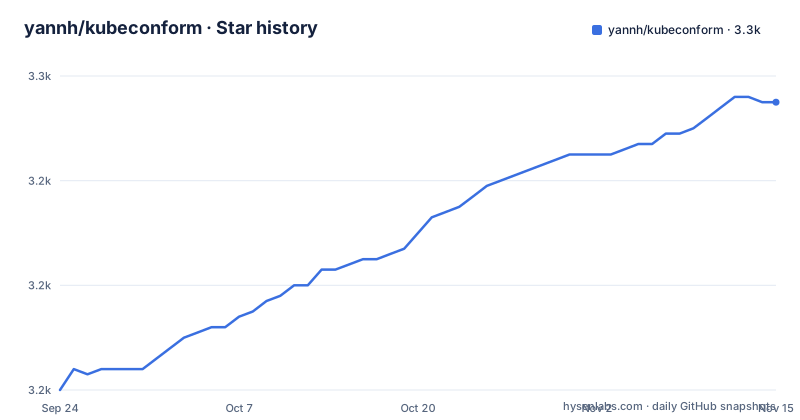
- yannh/kubeconform3,255 ★ · +55
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| yannh/kubeconform | 3.2k | 3.3k |
55 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The speed comparison skips 46 percent of the resources it validated
The performance claim is a pair of timed runs inside a collapsed section, and the numbers are worth reading rather than quoting. Kubeconform, run with eight workers over three directories of manifests on a four core laptop, reports 50714 resources in 35139 files, of which 27334 are valid, none invalid, none erroring and 23380 skipped. The skip is not incidental: the command carries the flag that turns a missing schema into a skip instead of a failure, and it is the same flag in kubeval's command line. So the headline of a clean run is a clean run over roughly 54 percent of the input, and the remaining 46 percent was not checked against anything. The wall time comparison is still real, six point seven seconds against thirty five, but the coverage difference is the part a reader has to notice. The tool also says in its own description that it was inspired by the validator it forked from, contains code from it and stays close to it, which is the honest framing for a project that replaced a slower tool rather than starting from nothing.
The default schema source is the maintainer's own fork of a community registry
The tool's answers depend on where its schemas come from, and the README is explicit that the default is a fork maintained by the tool's author, self-updating, described as more meticulously kept current than the upstream registry it forks. The context is a chain of conversions: Kubernetes describes its own API in an OpenAPI file checked into the main repository, tooling converts that into JSON schemas, and the converted schemas are what a validator actually checks against. The locations are configurable to remote or local addresses, which is what makes custom resource definitions and fully offline runs possible. The trade is plain: out of the box the tool is only as current as one person's fork, and in exchange it covers recent versions without waiting for the upstream publication pipeline.
The limits section names what the tool cannot check
There is a subsection titled the limits of validation, and it is the most useful paragraph in the documentation. It says the tool, like the validator it descends from, only validates manifests against the official Kubernetes OpenAPI specifications, and that the controllers still perform additional server-side validations which are not part of those specifications. It gives three issue numbers as examples, and then says you can use a third-party tool or the server-side dry run command to fill the missing gap. That is a precise statement of a boundary rather than a disclaimer, and it tells a pipeline author exactly what the tool will and will not catch before they wire it into a gate. It also frames the speed comparison honestly: fast schema validation is one layer, and the other layer costs more.
The version tag in the install example is four minor versions behind
Four install routes are documented: a Homebrew formula, a Windows package manager entry, a download from the release page, and Go's package manager. The Windows entry uses a publisher name that does not match the repository owner, which is the sort of detail that matters when a package manager refuses to find a package. The install routes are three lines of shell plus one release page:
brew install kubeconform
winget install YannHamon.kubeconform
The Go route shows two lines, one described as installing a specific version tag and one installing the latest, and the specific line pins a tag from the 0.4 series while the newest release is in the 0.8 series. Nothing is wrong with either line, but the example that teaches you how to pin teaches it with a version four minor releases back, so a reader who copies it lands on an older validator than the documentation describes in every other section.
A scratch image carrying two binaries and one certificate bundle
The container build is two stages and the final one has no operating system in it at all. The first stage is an Alpine image that installs the certificate authority bundle; the second starts from an empty base, copies that bundle across by hand, copies the validator, and copies a second binary, then declares the validator as the entry point. The empty base is why the bundle is copied explicitly, and it is coherent with a tool whose default mode fetches schemas over TLS. Seven image labels describe the author, source, description, documentation, licence, title and project address, with the licence declared as Apache 2.0. The second binary in the image is the schema conversion tool, kept in tree rather than taken from the third-party project the original validator depends on.
The release target hands a container a publish token and the Docker socket
The build file runs almost everything in containers, including the two steps most people would not. A local build target runs a command that adds the working directory to the global git safe directory list before compiling, so building modifies your global git configuration. The release target then starts a container with two environment variables passed through from the host, one of which is the publishing token, mounts the Docker socket from the host into that container, and invokes the release tool. A publish token and control of the Docker daemon in the same short-lived container is the combination to think about before forking the release process, and it is documented plainly in the build file rather than hidden in a pipeline definition.
Acceptance tests run twice, once with the network switched off
The acceptance suite is written in a shell testing framework and lives in two files: one that exercises the tool normally and one named for the case where it cannot reach anything. The build file builds a small image for that framework, runs the first file, and then runs the second with networking disabled. That second run is the interesting one, because this tool's default behaviour is to fetch schemas over the network, so an acceptance suite that runs with no network at all is asserting the offline path rather than merely claiming it. The same file also has targets that build and test inside a pinned Go container image with the working tree mounted at the module path, and a static build target that disables the C compiler, forces the vendored dependency mode, trims paths and passes external linker flags for a static binary.
Editorial conclusion
kubeconform fits a pipeline that wants a fast schema check on every commit and can run the server-side dry run alongside it. Four things to know. Its correctness depends on schemas fetched from the network by default, from a fork the maintainer keeps, so a network-isolated run needs the schema locations pointed somewhere local. Its benchmark skipped 23380 of 50714 resources because of the flag that makes missing schemas non-fatal, so the zero-invalid figure covers about half the input. It documents precisely what it cannot check, which makes it usable rather than merely fast. And the release machinery expects a container with a publish token and control of the Docker daemon, which is worth knowing before you fork the process.
Frequently asked questions
What does kubeconform do?
It validates Kubernetes manifests against the official OpenAPI specification converted to JSON schema, reading manifests from files, folders or standard input, and reporting a per-resource status plus a summary, with a non-zero exit code when anything is invalid.
What can kubeconform not validate?
The server-side validations that Kubernetes controllers perform and that are not part of the OpenAPI specification. The README says so directly, links three issue numbers as examples, and suggests filling the gap with a third-party tool or the server-side dry run command.
Where does kubeconform get its schemas?
By default from a self-updating fork of a community-maintained schema registry, credited with covering recent Kubernetes versions. The schema locations are configurable to remote or local addresses, which is what enables custom resource definitions and offline validation.
How do I install kubeconform?
Four documented ways: the Homebrew formula, the Windows package manager using a publisher name that differs from the repository owner, a download from the release page, or Go's package manager, where one example pins a tag from the 0.4 series and a second installs the latest.
Does kubeconform work without a network?
Yes, by pointing the schema locations at a local directory. Its acceptance suite is run twice, once normally and once with networking disabled, so the offline path is tested rather than asserted.
What does the ignore-missing-schemas flag do?
It skips files whose schemas cannot be found instead of failing on them. It is also the flag used in the README's own speed comparison, where the summary reports 23380 of 50714 resources skipped.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yannh-kubeconform)Star history chart for your README
[](https://hysenlabs.com/projects/yannh-kubeconform)Was this useful?