Gemini Nexus reaches Gemini Web with tokens scraped from the page, and says so in its own file
Gemini Nexus is a browser-focused AI assistant extension that integrates Gemini Web, the Gemini API, and OpenAI-compatible interfaces, supporting webpage context, image processing, tool calling, and MCP browser control.
At a glance
- What is it?
- A Chrome extension that puts nine model providers behind one side panel, with DevTools Protocol browser control and an MCP bridge. Its disclosure section comes before the feature list, and it is the most useful thing in the repository.
- Who is it for?
- Read the disclosure section first and decide before you install anything, because the web provider is not an API integration: it drives the consumer site with your own session, and the project states in its own words that this probably breaches Google's terms and may count as unauthorized access. If your use is your own Google account and a research context, that is a risk you can weigh.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
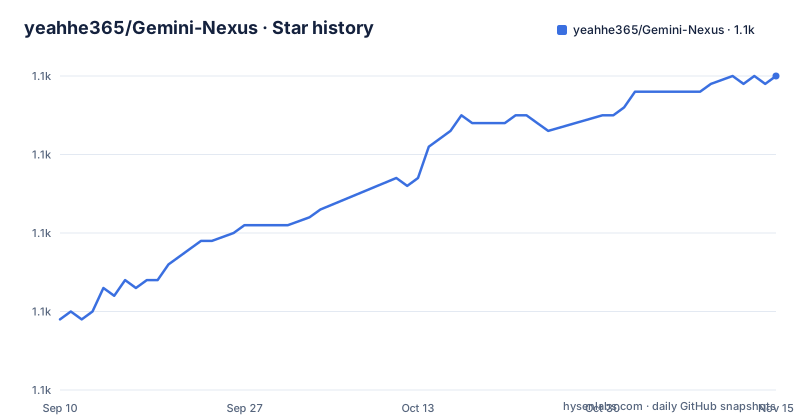
- yeahhe365/Gemini-Nexus1,130 ★ · +31
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| yeahhe365/Gemini-Nexus | 1.1k | 1.1k |
31 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The web provider runs on tokens read out of the page
Before the feature list, the file has a section called Reverse Engineering and Data Flow Disclosure, and the first paragraph is about how the web provider works.
The extension reaches gemini.google.com by reverse-engineering the site's internal RPC endpoints and extracting authentication tokens from the page HTML. Three token names are given, and they are stored locally and used to mimic browser requests, which is what allows access without an official API key. Requests go to Google's servers, two hostnames are named, carrying your own session credentials.
The project does not leave the reader to work out the implications. The file says in plain terms that this approach probably violates Google's terms of service and may be considered unauthorized access, and the last paragraph of the section says to use it at your own risk, that using the web or watermark features acknowledges potential terms violations, and that the authors provide the features for research and experimental purposes and disclaim liability.
Putting that disclosure at the top, in the same weight as the feature list, is unusual and it changes how the rest of the product should be read. This is not a wrapper around a documented interface with the legal edges filed somewhere else.
It also means the security surface is your Google session, held in extension storage, used to call an endpoint the vendor did not intend third parties to call.
Nine provider rows and four driver files
The provider table is the widest surface in the project file and the most compressed. Nine rows, each with a driver file, a set of models, a stated strength and a stated requirement.
Count the driver column and the shape changes. One row points at web.js, one at official.js, one at anthropic.js, and the remaining six all point at the same file, openai_compatible.js: OpenAI compatible, OpenAI official, DeepSeek, OpenRouter, Qwen on DashScope, and Zhipu. So the nine providers are four adapters, one of which is deliberately generic.
What the rows differ on is configuration and presentation. OpenRouter fetches its model list from the API, supports provider routing JSON and sends native reasoning fields. Qwen gets a dedicated compatible endpoint with a thinking toggle and vision image input. Zhipu gets a profile with native thinking toggles in the payload. Anthropic has its own adapter for the native Messages API with image input and a streaming display for extended thinking.
Then look at the dependency list and the story gets sharper. The runtime dependencies are a rendering stack: a graph rendering library, a syntax highlighter, a maths typesetter, a Markdown parser and a diagram renderer. There is no Google client, no OpenAI client and no Anthropic client. Every provider call in this extension is hand-rolled, which is why the differences between providers are all expressed in one generic driver rather than in per-vendor libraries.
Watermark removal is disclosed as attribution stripping
The second paragraph of the disclosure section is a shorter one and says something the feature list would not.
For images generated by Gemini, the extension removes embedded watermarks, described as metadata markers, so the image can be downloaded directly. The file then says plainly that this strips attribution and signature from AI-generated content, and that users should be aware of the copyright implications and of Google's policies on generated content usage.
The word watermark suggests an image artefact, and the file's own correction is that it is metadata. That difference matters in practice: a visible overlay is a presentation choice, while an embedded marker is provenance, and removing it is removing the record of what produced the file.
Notice where this sits. It is not in the feature list, not near the image input feature, and not in a separate legal section. It is in the same paragraph sequence as the token extraction, under the heading that says reverse engineering and data flow, which suggests the author treats both as things a user must be told before using the extension rather than as settings to discover.
Both disclosures are repeated in the closing risk paragraph, so the file states twice that using either feature acknowledges potential terms violations.
A drift check exists because the web endpoints move
Reverse engineering an undocumented interface creates a maintenance job that nobody signs up for, and the scripts show that this project addressed it.
There is a script named for checking Gemini Web drift, wired as an npm script that runs a Node file called gemini-web-drift-check.mjs. In other words, the repository contains an automated check for whether the reverse-engineered contract still matches reality, and it runs in the same script list as the formatter, the unused-export linter and the test suite.
That is the single most important engineering fact about the web provider. The failure mode is silent: if Google changes an internal endpoint or a token format, the extension keeps loading and the requests start failing, or worse, start returning something nobody checked. A drift check turns that into a test failure.
The rest of the script list is conventional and shows a real release process. Dev and build are Vite, formatting is Prettier, unused exports are caught with a dedicated tool that also has its own configuration file at the root, tests run under Vitest with jsdom for the browser-shaped parts, and there are scripts to package the extension, package a local build, and publish to the Chrome Web Store.
One number is out of step: the manifest version is 5.4.0 while the newest release tag is v5.3.0, published three days before the last commit. So the version in the working tree is one ahead of anything a user can download.
Temporary chats keep web requests out of your account history
The capability list is where the extension's care shows, and two entries are about what it does not leave behind.
The first is temporary chats for the web provider, enabled so that web requests are not added to Gemini's recent chats. In other words, the extension will drive your session, and it can also drive it without the conversation appearing in the account's own history. That is a privacy choice in one direction and an evasion affordance in the other, and the file presents it as the former without commentary.
The second is scope control. The side panel can be limited by tab so it does not sit over pages where you do not need it, and browser-control tasks are marked with native Chrome tab groups, with the page listing and page selection commands kept inside the controlled scope.
Other entries are about capability differences between providers, and they are worth reading carefully. Re-editing a historical user message and continuing from that point is enabled for API providers only, so the web client cannot do it. Context is managed by summary compression and trimming of recent turns to reduce the risk of exceeding a model's context window. Google Search grounding is available on the official Gemini API with sources shown, and web search on OpenAI-compatible endpoints goes through the Responses API or through the chat completions search options, depending on the endpoint.
There is also a promise about settings surviving extension identity changes and local upgrade paths, which is the kind of unglamorous continuity most extensions lose.
Browser control is a local tool loop over the DevTools Protocol
The extension is not only a chat panel. The browser control section is built on a background directory and the Chrome DevTools Protocol, and it lets the model perform agentic tasks in the browser through a local tool loop, meaning the calls run on the machine rather than through a remote service.
The navigation category is fully enumerated: page navigation, opening a new page, closing a page, listing pages and selecting a page, implemented by managing the page lifecycle through the browser's own tabs API rather than through synthetic input.
The interaction category is not. The table's second row lists click, hover, and then stops mid-token, with the rest of the command list and its implementation column absent from the file. So the category that matters most for anything beyond navigation is exactly the part a reader cannot check.
What the visible part does establish is the shape: named commands rather than free-form instructions, an explicit page lifecycle, and a scope kept deliberately narrow, with the page listing and selection commands focused on the pages being controlled. It also explains the tab group feature in the capability list, since marking which tabs are under control is how a person can tell what the extension is doing while it does it.
That combination, a real scope indicator and a visible scope list, is the difference between a tool you can supervise and one you cannot.
A native logger gets installed by an npm script
Two entries in the script list deserve a second look in a project that describes itself as a browser extension.
One installs a native logger, and the other uninstalls it, both running a Node script with an install flag as the only difference. A Chrome extension with a native component is no longer something that lives in the browser, and the file does not explain what the component is, where it lands, or what it logs.
The other is a publish script for the Chrome Web Store, and the root of the repository contains an example environment file for exactly that. So the release path is a first-class part of the project: build, package the extension, sync a local package, publish, with each step a named script.
The directory layout matches a Manifest V3 extension with more than the usual parts: a background directory for the service worker and the control loop, a content directory for what runs in the page, a side panel directory, a settings directory, a shared directory, a services directory holding the provider drivers, a sandbox directory, a vendor directory, a test directory, and a scripts directory.
Two of those are worth a question. A sandbox directory at the top level of a browser extension is presumably where untrusted or generated content is contained, and a vendor directory implies code carried in-tree rather than pulled from a registry. Neither is explained anywhere in the visible file, and both are the kind of detail you want to read before installing.
Five gates run before anything is released
There is one script that looks like a release gate, and it chains five checks in a fixed order.
The first is a formatting check across the repository. The second is a production build. The third is a TypeScript type check with no output. The fourth is the unused-export linter. The fifth is the test suite.
Every one of them is a category a project can skip and usually does. Formatting and types are cheap and catch the two classes of error that are embarrassing in review. The unused-export check is the unusual one, and it is the check that keeps a project with nine provider drivers from accumulating dead configuration paths as providers are added and removed.
The test setup is worth noting for what it implies. Tests run under Vitest with jsdom, so there is a DOM without a browser, which is the right level for testing a side panel and content script without launching Chrome. And the drift check from the earlier section is not in this chain, which means it is run separately, and probably on a schedule, since the thing it checks changes on Google's side rather than on yours.
For a project of this size, five gates is a reasonable amount of ceremony. The notable thing is not the number but that the one check which exists specifically because of a reverse-engineered interface is the one not in the default chain.
Editorial conclusion
Read the disclosure section first and decide before you install anything, because the web provider is not an API integration: it drives the consumer site with your own session, and the project states in its own words that this probably breaches Google's terms and may count as unauthorized access. If your use is your own Google account and a research context, that is a risk you can weigh. If you need this in a product or on someone else's account, the answer is different. Two smaller things to check. The provider list is nine rows wide and four driver files deep, so the widest part of the surface is configuration rather than code, which also means less of it is exercised. And the second disclosed feature removes watermarks from generated images, which the project itself calls stripping attribution, so that is a separate decision from the first one.
Frequently asked questions
What is Gemini Nexus?
A Chrome extension that gives the browser an AI layer, combining Gemini Web, the Google Gemini API, OpenAI-compatible interfaces and several third-party providers in one place. Beyond the side panel it includes an injected floating toolbar, image and screenshot input, browser control over the Chrome DevTools Protocol, and optional external MCP tools.
How does the Gemini Nexus extension use Gemini Web without an API key?
It accesses gemini.google.com by reverse-engineering internal RPC endpoints and extracting authentication tokens from the page HTML, storing them locally and using them to mimic browser requests with your session credentials. The project states this approach probably violates Google's terms of service and may be considered unauthorized access.
Which model providers does Gemini Nexus support?
Gemini Web, the official Gemini API, an OpenAI-compatible API, the OpenAI official API, DeepSeek, OpenRouter, Qwen on DashScope, Anthropic and Zhipu, each with its own base URL, API key and model IDs. The provider table has nine rows but only four driver files, with one OpenAI-compatible driver serving six rows.
What data does Gemini Nexus send to Google?
User text, images and uploaded files go to whichever provider is configured, and for the web provider that means Google's servers. API keys are kept in Chrome extension storage and are not transmitted to any third party beyond the chosen provider.
What does the browser control in Gemini Nexus do?
It runs a local tool loop over the Chrome DevTools Protocol from a background directory, with page lifecycle commands for navigating, opening, closing, listing and selecting pages implemented through the browser tabs API. Tasks are marked in native tab groups and kept inside the controlled scope.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yeahhe365-gemini-nexus)Star history chart for your README
[](https://hysenlabs.com/projects/yeahhe365-gemini-nexus)Was this useful?