reNgine: the database is the product, not the scanner
reNgine is an automated reconnaissance framework for web applications with a focus on highly configurable streamlined recon process via Engines, recon data correlation and organization, continuous monitoring, backed by a database, and simple yet intuitive User Interface. reNgine makes it easy for penetration testers to gather reconnaissance with minimal configuration and with the help of reNgine's correlation, it just makes recon effortless.
At a glance
- What is it?
- A web reconnaissance suite aimed at authorised testers, where the differentiator is a persistent datastore with a query language rather than the scanning tools it wraps, plus subscans that let an operator branch into a focused scan mid-pipeline, running on Django, Celery, Redis and Postgres with the schedule held in the database.
- Who is it for?
- reNgine suits an authorised tester who runs reconnaissance repeatedly against the same scope and wants findings kept in a queryable store rather than in a folder of output files, and who benefits from pivoting into a focused scan the moment a subdomain looks interesting. It does not suit a one-off scan, where the Postgres, Redis and Celery stack is more machinery than the job needs.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
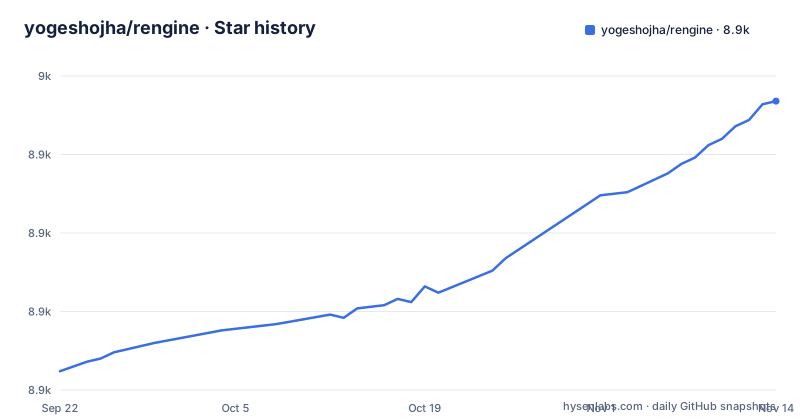
- yogeshojha/rengine8,942 ★ · +86
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| yogeshojha/rengine | 8.9k | 8.9k |
86 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Findings live in a database, not in a folder of output files
The stated pitch is about what happens to reconnaissance data after the tools have run. Rather than grepping through json, text or csv files, the suite integrates with a database and puts correlation and organisation on top of it. The part with real substance is the query language, which filters results using operator syntax: one example filters all alive subdomains by their HTTP status code, and another filters subdomains that are both alive and have a keyword in the name. Consequence: findings persist between runs and can be asked questions about, which is the difference between running a list of tools and running a process. It also means the datastore is part of the product, so its backup and retention decisions are yours to make.
The filter syntax looks like this:
http_status=200&name=adminSubscans exist because a long pipeline cannot be steered
One feature is presented as the thing that sets this suite apart from other open source tools: subscans. The argument is about waiting. Rather than waiting for an entire pipeline to finish, you can respond to something you discover while it is still running, whether that is running a focused port scan against a subdomain that just appeared or escalating to a vulnerability assessment of it. The claim is that this makes iterative reconnaissance possible rather than batch. Consequence: the workflow changes shape. An operator who spots an interesting host mid-scan does not have to abort and start again, which matters on large scopes where a full pass is expensive in time and in requests against someone else's infrastructure.
Four engines ship ready, and everything else is a YAML file
Scan engines are described as highly configurable and based on YAML configuration, with customisation running from thread management through timeout settings to rate limits, described as entirely adjustable. Four engines are provided pre-configured so the common case needs no setup: a full scan, a passive scan, screenshot gathering, and an OSINT engine. The repository root carries a default YAML configuration file, which is the reference for what a custom engine looks like. Consequence: the ready-made engines cover the straightforward case and the YAML file is the extension point, so anything beyond them is configuration work rather than code work. That is also why rate limiting matters here: the configuration is where you throttle requests to a target you do not own.
The repository root holds the reference configuration in a single file:
make certswhich is the same target the setup flow calls once before the rest of the stack is started.
The stack is Django, Celery, Redis and Postgres
The compose file is more informative than the feature list about how this works. There is a Postgres service with a persistent volume, published only on the loopback interface rather than on all interfaces. There is a Redis service, used as the Celery broker and result backend at the same address. There is a Celery worker whose entrypoint comes from the web image and whose volumes include shared directories for wordlists, saved results, pattern sets and template sets, so scanning material can be mounted in rather than baked in. There is also a Celery beat service whose command explicitly selects a database-backed scheduler. Consequence: the periodic schedule lives in the database rather than in a container's memory, which is what makes continuous monitoring survive a restart.
The database service itself is deliberately narrow:
db:
    restart: always
    image: "postgres:12.3-alpine"
with its port published only on the loopback interface:
- "127.0.0.1:5432:5432"so the datastore holding your reconnaissance data is not reachable from another host unless you change that binding yourself.
Certificates are a separate first step, and the database stays local
Two operational details stand out in the build file. The first is that certificate generation is its own target, running a dedicated setup compose file to produce certificates, and the general setup target depends on it, so TLS for the interface is expected rather than something you bolt on afterwards. The second is the makefile's service list, which includes a local model service alongside the database, web, proxy, cache, worker and scheduler, which suggests the report generation feature has a local option rather than requiring a remote API for every run. There is also a batch entry point for Windows alongside the shell script. Consequence: the install is a multi-step process with a generated-certificate prerequisite, and the datasource is not reachable from other hosts by default, which is the right default for something holding reconnaissance data.
The services the makefile starts are enumerated in one line:
SERVICES := db web proxy redis celery celery-beat ollamaand the certificate step is a separate target that delegates to the setup compose file rather than to the main one, which is why it is safe to run before anything is up.
The advertised version is about two years behind the tree
The release list runs through three versions in quick succession in the middle of 2024, ending with 2.2.0 in September 2024, and that release is still the headline on the front page today. The features it added are listed there too, including a hub for syncing bug bounty programs, in-app notifications, an extra subdomain enumeration tool, the ability to upload multiple template and pattern sets, regex support in out-of-scope subdomain configuration, and an additional PDF report template. The repository itself was last pushed on 31 October 2026. Consequence: there is roughly two years of commits behind the newest tag, so a deployment pinned to that release and a fresh clone of the default branch are not the same software.
The audience is stated three times, and it is authorised testing
The description names penetration testers, and the explanatory section names security professionals, penetration testers and bug bounty hunters. That is worth stating plainly rather than leaving implied, because what the suite does is reconnaissance against domains, covering subdomain discovery, IP and open port identification, endpoint collection, directory and file fuzzing, screenshot capture, vulnerability scanning, registration data lookup, web application firewall detection and checks for misconfigured object storage buckets. None of that is self-defence. It is the reconnaissance half of an assessment, and it is only legitimate against a scope you have been authorised to test, which is why the out-of-scope subdomain configuration is a first-class feature rather than an afterthought.
Editorial conclusion
reNgine suits an authorised tester who runs reconnaissance repeatedly against the same scope and wants findings kept in a queryable store rather than in a folder of output files, and who benefits from pivoting into a focused scan the moment a subdomain looks interesting. It does not suit a one-off scan, where the Postgres, Redis and Celery stack is more machinery than the job needs. Before installing, read the engagement scope out loud, plan the storage and certificate steps, and check whether the version you are running is the one the documentation describes, since the last tag predates the current tree by about two years.
Frequently asked questions
How do I install reNgine?
Through containers, using the compose files in the repository. The build file generates certificates from a separate setup compose file as its first step, then builds and starts the service list, which includes the database, web, proxy, cache, worker and scheduler services. There are separate compose files for development and for the certificate setup, plus a shell installer and a Windows batch entry point.
How do you use reNgine?
You pick a scan engine and a target. Engines are configured in YAML and are customisable from thread counts through timeouts to rate limits, with four provided pre-configured, including a full scan, a passive scan, screenshot gathering and an OSINT engine. Results are stored in a database rather than files, so you query them with operator syntax such as filtering alive subdomains by status code.
Is reNgine free?
Yes, the project is open source under the GNU General Public License version 3. It is aimed at security professionals, penetration testers and bug bounty hunters, and the documentation is published separately on a project wiki.
What is Recon-ng used for?
Recon-ng is a separate, older project, so it is worth separating the two names. This repository is reNgine, which uses configurable YAML scan engines, stores reconnaissance results in a database with a query language, supports continuous monitoring through a database-backed scheduler, and offers subscans that let you branch into a focused port or vulnerability scan before the main pipeline finishes.
What is the purpose of reconnaissance?
In this suite's terms it is building a picture of a target web application before testing it: subdomain discovery, IP and open port identification, endpoint collection, directory and file fuzzing, screenshots, vulnerability scanning, registration data, firewall detection and misconfigured bucket checks, with findings kept in a database so the same scope can be queried and re-checked later.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yogeshojha-rengine)Star history chart for your README
[](https://hysenlabs.com/projects/yogeshojha-rengine)Was this useful?