The Postgres Operator's Go module is v2 and its custom resource group is not
Postgres operator creates and manages PostgreSQL clusters running in Kubernetes
At a glance
- What is it?
- A Kubernetes operator for Patroni-managed database clusters: eighteen direct dependencies and three of them archived, deprecated or pinned to a 2016 commit, a make clean target that fails on a second run, a floating latest base image for a database, a Python linter config beside a Go one, and six release lines in a table that all claim the same Kubernetes floor.
- Who is it for?
- The Postgres Operator fits a team running PostgreSQL on Kubernetes who want the cluster lifecycle described in manifests rather than in imperative calls, and who want the replication layer to be Patroni rather than something assembled in-house. Three things to know before you adopt it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
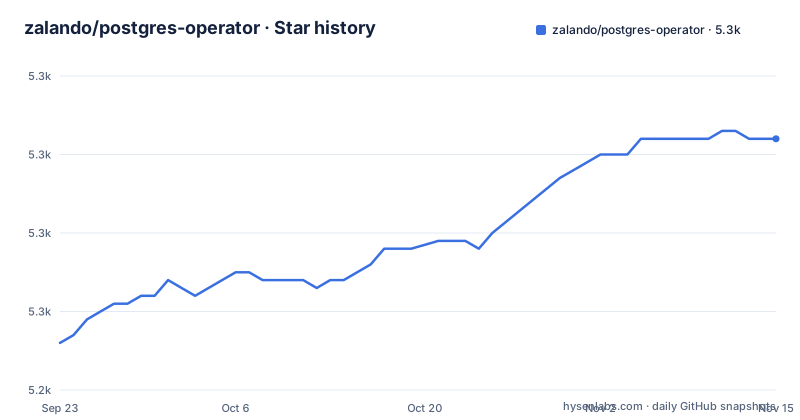
- zalando/postgres-operator5,272 ★ · +26
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| zalando/postgres-operator | 5.2k | 5.3k |
26 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The module path moved to a major version and the resource group did not
A Go library or binary that changes its public API in a breaking way has to change its module path, and this one did. The path in its module file ends in a second major version segment.
Its custom resource definitions did not move with it. The build configuration generates resource definitions from two separate API group directories, one under a name derived from the sponsoring company and one under the older, differently spelled name the project has carried for years. And the generated manifests include a resource for a postgresql cluster and a resource for something called a team, in two group paths.
So one binary serves two resource groups, and the Go module it was built from has already been through a major version. That combination is normal for a long-lived Kubernetes operator and it is also the thing a reader has to hold in their head: the thing that has not changed is the identifier you put in a manifest, and the thing that has changed is the import path of the code.
The README treats the migration as a precondition rather than a note. It says that if you have been using the operator since the first major line, make sure you have read the migration document before deploying a second major. That is the correct framing for a component whose identifiers survive its own major version, because the risk is not a compile error but a resource the controller no longer reconciles.
Every release line in the table is pinned to the Go version it was built with
The support table has four columns and six rows, and the third column is the one that explains the second.
Each row is a release line, the PostgreSQL versions it covers, the Kubernetes versions it needs, and the Go version it was built against. The current line covers five PostgreSQL majors on Kubernetes 1.27 and newer, built with the newest Go. The five older lines cover progressively older database ranges and were built with progressively older Go versions, going back four Go releases.
The table records which Go version each release line was built with.
The Kubernetes column is the interesting one, because it says 1.27 and newer for all six rows. Either the floor was raised across the whole table at some point, or the older rows are out of date on that axis. Nothing in the table distinguishes the two, and for a component that runs a database, a Kubernetes floor that is identical across every row is worth confirming against the release notes rather than assuming.
The database ranges step down across the table, from 14 to 18 for v2.0.3 to 11 to 16 for v1.11.0, so the oldest line still covers six PostgreSQL majors and the support story is a set of parallel images rather than a single supported version.
make clean fails the second time, because two of its three deletions have no force flag
The build file has a clean target, and two of the three things it removes are removed without the flag that makes removal tolerate a missing file.
clean:
	rm -rf build
	rm $(GENERATED)
	rm $(GENERATED_CRDS)
The first line is fine. The second and third list the generated source files and the generated resource manifests, and both use a plain removal. A plain removal of a file that is not there is an error, so `make clean` on a tree where the generated files have not been produced fails, and running `make clean` twice fails the second time by construction.
That is a small bug with an outsized annoyance value, because clean is the target a person reaches for when something has gone wrong and when the tree is already in the state they want. The two variable lists above it are correct and specific, which makes the omission look like an oversight rather than a decision.
The same file is otherwise careful in a way that makes this stand out. cgo is off by default and switched on only together with the race detector, which is the correct pairing. The version is read from the source-control description, so a local build from a modified tree gets a marker in its name that says so. A separate variable resolves to whichever of two implementations of the stream editor is installed, which is how one makefile serves two development platforms. And when a pull request number is set, image tags gain a suffix composed from the CDP build version, with the same suffix applied to a second image published from the same repository for the connection pooler.
All of that is careful, and then clean forgets a flag.
A database operator whose own base image floats
The build file has one variable for the base image of the container it produces, and its default is the latest Alpine tag.
That is a common and usually harmless default. In this case the artefact is the component that decides when your database fails over, and the base is the layer everything else sits on.
The variable is overridable, so the fix is one line, and the image reference is otherwise careful: it lives under the sponsoring organisation's registry, and its tag is composed from the same source-controlled version as everything else. The tag can also gain three separate suffixes, one for a pull request, one for a debug build and one for a fresh build, and the second image published from the same repository for the connection pooler gets the same three.
The debug path is a different thing again. A variable switches the build to a separate Dockerfile, adds flags that disable optimisation and inlining, and stamps the resulting image with a time of day. So there are two container builds, one of which is optimised and one of which is instrumented, and the DEBUG variable set by the person running it decides between them.
The base image reference is a tag, and it is the floating one at the bottom of the stack.
Three of nineteen direct dependencies are archived, deprecated or pinned to 2016
Eighteen direct dependencies is a small list for a Kubernetes operator, and three entries in it date the project.
One is an error-wrapping package, github.com/pkg/errors v0.9.1. One is a mocking library, github.com/golang/mock v1.6.0. And one, github.com/motomux/pretty, is pinned not to a version but to a commit, in a pseudo-version form, and that commit's date is in 2016.
Two of those three are cosmetic in the sense that they still work. The third is the interesting one, because it is pinned to a commit rather than a tagged version.
The mocking library explains an entry in the repository root: a directory of generated mocks, committed, which is the output of that generator. So the archived dependency is not a leftover, it is the tool that produces part of the tree.
The rest of the list is a good sign about the project's discipline. The Kubernetes client libraries are at one consistent version across four packages. The AWS SDK is the second generation, pinned across the core, the config package and the EC2 service. The database driver is the pure-Go one rather than a cgo binding, which is what lets the binary be built with cgo disabled by default. And a semver library and a YAML library are there because the operator has to compare image tags and read manifests.
Eighteen dependencies, one of them from 2016, for a component that owns a database's high availability is a defensible dependency budget.
A Python linter config sits in the root of a Go project
The repository root carries two lint configurations, one for each of two languages, and only one of them matches the project.
The recorded primary language is Go, and the Go linter configuration sits beside a second file whose extension and whose name belong to a different toolchain entirely.
That is a two-line curiosity, and it is worth noting because the rest of the root is a model of how a project like this is organised. There is a codeowners file and a separate maintainers file, which is a distinction between who reviews and who owns. There is a security policy. There is a delivery configuration named after the way this project ships things. There is a configuration for a pull-request approval service, which is a hosted product. And there is a contributing guide.
The code itself is arranged by role rather than by layer. A command directory, a packages directory, manifests, a charts directory for the Helm chart, a pooler directory for the connection pooler, a logical-backup directory, a user interface directory, a mocks directory, an end-to-end directory, a hack directory for build scripts, a documentation directory, and a Docker directory.
So the operator, its connection pooler, its user interface, its backup tooling and its end-to-end tests are one repository with one build, one lint configuration that applies and one that does not, and one test suite with generated mock files committed alongside the code they stand in for.
The stated promise is that you never touch the Kubernetes API, and that is about you
The second sentence of this README is the design argument, and it is easy to misread.
It says the operator is configured only through its resource manifests, in order to ease integration into automated pipelines with no access to the Kubernetes API directly, promoting infrastructure as code over manual operations.
The no-access clause is about the person deploying the cluster, not about the operator. An operator is a controller running inside the cluster; it talks to the Kubernetes API constantly. What the sentence means is that a human or a pipeline never needs to call that API to change a cluster, because the cluster's desired state is a manifest and the controller reconciles toward it.
That is the right framing for the audience, and it is a real advantage over imperative administration. A cluster becomes a reviewable object, a change is a pull request, and a promotion is the same manifest applied somewhere else.
The feature list that follows is where the project is most concrete, and several entries are specific enough to be checked rather than admired. Rolling updates on cluster changes including quick minor version updates. Live volume resize without pod restarts, naming two volume types. In-place major version upgrade, with a note that it can be applied globally across all clusters. Pod protection during the bootstrap phase and configurable maintenance windows. Restore and cloning on three named clouds, plus logical backups to object storage. A standby cluster from a write-ahead log archive or a remote host. And a UI for creating and editing manifests.
The list also claims compatibility with one managed Kubernetes distribution and multi-architecture support, which are the two entries a reader should verify against their own platform rather than take on trust.
Editorial conclusion
The Postgres Operator fits a team running PostgreSQL on Kubernetes who want the cluster lifecycle described in manifests rather than in imperative calls, and who want the replication layer to be Patroni rather than something assembled in-house. Three things to know before you adopt it. The major version bump is in the Go module path, not in the resource group, and the project requires you to read a migration document before deploying a v2 operator. The base image of the operator's own container is a floating latest tag, which for a component that owns your database's failover is a choice worth overriding. And the support table records the Go version each release line was built with.
Frequently asked questions
what is postgres operator
A Kubernetes operator that runs highly available PostgreSQL clusters using Patroni for replication, configured entirely through custom resource manifests rather than direct calls to the Kubernetes API, so a cluster can be described as code and applied through a pipeline.
What is CNPG?
This repository does not explain it. That acronym belongs to another project and is not mentioned anywhere in the readme, the module file or the documentation links it provides.
How does this compare with other Kubernetes Postgres operators?
Nothing in this repository makes that comparison. The readme lists its own features, names the replication layer it uses and the backup tools it supports, and links to its own documentation. It names no alternative and claims no difference from one.
Which PostgreSQL and Kubernetes versions are supported?
A table gives one row per release line. The current line covers PostgreSQL 14 through 18 on Kubernetes 1.27 and newer; five older lines are listed with older database ranges, and all six rows state the same Kubernetes floor. Each row also records the Go version the line was built against.
Do I need to change anything to move from the first major version to the second?
The readme treats it as a precondition, telling anyone who has used the operator since the first major line to read the migration document before deploying a second major one. Note that the Go module path carries the second major version while the custom resource group did not change.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zalando-postgres-operator)Star history chart for your README
[](https://hysenlabs.com/projects/zalando-postgres-operator)Was this useful?