Concrete ML: running scikit-learn style models on encrypted data with Zama's FHE stack
Concrete ML: Privacy Preserving ML framework using Fully Homomorphic Encryption (FHE), built on top of Concrete, with bindings to traditional ML frameworks.
At a glance
- What is it?
- zama-ai/concrete-ml wraps Zama's Concrete compiler so data scientists can turn scikit-learn, XGBoost and PyTorch models into fully homomorphic equivalents. This look covers the quantize-encrypt-run-decrypt flow, the install matrix and the version constraints.
- Who is it for?
- Use Concrete ML when you want to evaluate a scikit-learn style or quantization-aware model on encrypted inputs and can live with Python 3.8 to 3.12, Linux or macOS pip installs and an older release line. Look elsewhere if you need Windows pip installs or a recent tagged release.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 11 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
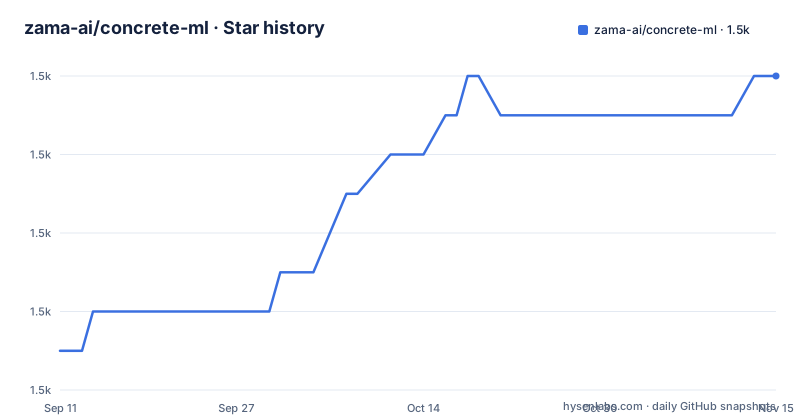
- zama-ai/concrete-ml1,458 ★ · +7
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| zama-ai/concrete-ml | 1.5k | 1.5k |
7 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The model is trained in the clear and quantized before anything is encrypted
Concrete ML does not hide the training step in its basic flow. The introductory example builds a synthetic dataset with make_classification, splits it, and trains a LogisticRegression imported from concrete.ml.sklearn. The comment in the code says it directly: train in the clear and quantize the weights. The constructor argument n_bits=8 sets that quantization.
from sklearn.datasets import make_classification
from sklearn.model_selection import train_test_split
from concrete.ml.sklearn import LogisticRegression# Now we train in the clear and quantize the weights
model = LogisticRegression(n_bits=8)
model.fit(X_train, y_train)The class name and the fit call match scikit-learn, which is the project's ease-of-use argument: data scientists keep APIs they already know. The project also says additional options on these models allow inference or training on encrypted data. The cost of the design is that FHE works on integers, so a float model has to be quantized, and the n_bits value is a choice you make that affects what the encrypted model computes. The README does not give accuracy figures for different bit widths in the part visible here, so measure on your own data.
Encrypt, run and decrypt are three separate calls on the fhe_circuit
Calling predict_proba with fhe set to execute does the whole encrypted round trip in one line. The README also spells out the individual steps, and says that running them separately is equivalent to calling predict_proba on the model instance. That matters if the party holding the data and the party holding the model are different machines.
# Predict probability for a single example
y_proba_fhe = model.predict_proba(X_test[[0]], fhe="execute")

# Quantize an original float input
q_input = model.quantize_input(X_test[[0]])

# Encrypt the input
q_input_enc = model.fhe_circuit.encrypt(q_input)

# Execute the linear product in FHE
q_y_enc = model.fhe_circuit.run(q_input_enc)

# Decrypt the result (integer)
q_y = model.fhe_circuit.decrypt(q_y_enc)
The sequence is quantize the float input, encrypt, run on the encrypted value, decrypt to an integer, then de-quantize and post-process with dequantize_output and post_processing. The result of the run step is still an integer in quantized form, so anyone who stops after decrypt has a quantized score, not a probability. The example operates on a single row, X_test[[0]], so the sample shows one encrypted prediction rather than batch throughput.
Built-in models mirror scikit-learn and XGBoost, custom models must arrive through ONNX
There are two ways to get a model into Concrete ML. Built-in models are ready-to-use FHE-friendly classes whose interface is equivalent to their scikit-learn and XGBoost counterparts. Custom models are for people who want their own architecture: they must support quantization-aware training, are developed in PyTorch or keras and tensorflow, and are imported into Concrete ML through ONNX. The README also says PyTorch models can be converted to FHE.
The boundary is worth stating from the reader's side. You do not hand Concrete ML an arbitrary trained network. A custom model has to be built for quantization-aware training before it is imported, and the entry point is ONNX. If you already have a float model from another pipeline with no quantization-aware training behind it, the project's description of custom models does not cover that case, and you would start from the documentation at docs.zama.ai/concrete-ml. The listed use cases range from healthcare and financial analysis to ad campaign tracking, biometrics and government services, and the repository has a use_case_examples directory alongside benchmarks.
pip does not work on native Windows, and Apple Silicon has no Docker image yet
The install matrix is the first thing to check. Linux, Windows Subsystem for Linux and macOS 11 or newer on Intel are available through both Docker and pip. Native Windows is Docker only, with pip marked No. Apple Silicon (M1, M2 and later) is the reverse: pip is available, and Docker is listed as coming soon.
The Docker route is a single pull:
docker pull zamafhe/concrete-ml:latestThe pip route first upgrades the packaging tools and then installs the package:
pip install -U pip wheel setuptools
pip install concrete-ml
The consequence is that a Windows user without WSL has to run the container, and an Apple Silicon user cannot use the container at all, going through pip instead. The README says Concrete ML can also be installed on Kaggle and on Google Colab, with a community thread linked for Kaggle. Detailed pip instructions are in the documentation under getting-started/pip_installing.
Three different statements of which Python versions work
A reader checking Python compatibility finds three answers in the repository. The README note says Concrete ML only supports Python 3.8, 3.9, 3.10, 3.11 and 3.12. The pyproject.toml dependency line says python is at least 3.8.1 and below 3.13, which agrees with that range. But the trove classifiers in the same file list only 3.8, 3.9 and 3.10.
The practical reading is that the dependency constraint is what pip enforces, so 3.8.1 through 3.12 should resolve, while the classifiers are metadata that was not extended to 3.11 and 3.12. Python 3.13 is excluded by the upper bound, so a fresh environment on the newest interpreter will not install. The Makefile also hints at which interpreters the maintainers develop against: DEV_DOCKER_PYTHON defaults to py38, and the py312 choice switches the Ubuntu base from 20.04 to 24.10. If you pick an interpreter for a new project, use one inside the README range and pin it, since the repository itself is not consistent about the list.
The install is tied to concrete-python 2.10.0 from a Zama package index
Concrete ML sits on top of the Concrete compiler, and pyproject.toml pins that relationship tightly. concrete-python is fixed at exactly 2.10.0 and read from a source named zama-pypi-cpu. concrete-ml-extensions is fixed at 0.1.9 and setuptools at 75.3.0. A commented line shows an earlier pin of concrete-python at 2.7.0, and a comment nearby explains that naming a source makes Poetry look only at that source, which is why it is meant for Concrete Python's non-public releases.
The consequence for an environment is that Concrete ML moves in lockstep with one compiler build. You cannot freely upgrade concrete-python on its own, and any other package that wants a different setuptools can conflict with the exact pin. A FIXME in the same file links an internal issue about whether to fix specific versions or use lower and upper bounds, so the maintainers themselves mark the strict pinning as unsettled.
The development workflow is built on Poetry (the Makefile pins POETRY_VERSION to 1.8.4) and Docker, and the setup target forces an import of skorch to avoid an obscure bug that made pytest commands fail with Poetry 1.3 or newer. That matters only if you contribute, but it shows how sensitive the dependency set is.
The newest tagged release is from April 2025 and the license is reported inconsistently
The recent tagged releases are v1.9.0 on 2025-04-10, v1.8.0 on 2025-01-08 and v1.7.0 on 2024-09-30. The last push to the repository was on 2026-08-04, which is later than the newest tag, so work continues on main without a newer release. The repository is not archived. pyproject.toml still says version 1.9.0. If you need a pinned, tagged version, v1.9.0 is the one to cite, and anything you install from main is ahead of it.
The license field needs a manual check. GitHub reports NOASSERTION, meaning it could not determine a license from the repository. The pyproject.toml declares BSD-3-Clause-Clear, and the repository contains a LICENSE file and a deps_licenses directory. Read the LICENSE file before using the library in a product, because a tool that reports no license is not something legal review will accept on trust.
Support channels named are the documentation, a community page, the awesome-zama resource list and a bounty program. The repository also carries an UPGRADING.md, which is the place to look when moving between release lines.
Editorial conclusion
Use Concrete ML when you want to evaluate a scikit-learn style or quantization-aware model on encrypted inputs and can live with Python 3.8 to 3.12, Linux or macOS pip installs and an older release line. Look elsewhere if you need Windows pip installs or a recent tagged release. Check the license text yourself, because GitHub reports none.
Frequently asked questions
What is Concrete ML?
Concrete ML is Zama's open-source privacy-preserving machine learning toolkit built on Concrete. It turns models into fully homomorphic equivalents so data scientists can use FHE without cryptography knowledge.
Can Concrete ML predict concrete strength, as in building materials?
Concrete ML is not about construction concrete. It is a fully homomorphic encryption framework from Zama, built on the Concrete compiler, for running machine learning on encrypted data.
Does Concrete ML install with pip on Windows?
No. The install table marks pip as unavailable on Windows and Docker as available. Windows Subsystem for Linux supports both pip and Docker.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zama-ai-concrete-ml)Star history chart for your README
[](https://hysenlabs.com/projects/zama-ai-concrete-ml)Was this useful?