pugixml gives you a DOM, XPath 1.0 and automatic Unicode conversion, and makes you check the parse result
Light-weight, simple and fast XML parser for C++ with XPath support
At a glance
- What is it?
- A small C++ XML library that parses a document into a modifiable tree, queries it with XPath 1.0, and converts encodings on the way in and out. It is widely embedded in other products, MIT licensed, and its own build system is unusually honest about which warnings and sanitizers you want.
- Who is it for?
- pugixml fits a C++ codebase that already has a DOM mindset and wants XPath without taking on a schema aware parser, and it fits commercial code because the licence is MIT. It does not fit a project that needs validation against a schema or DTD processing, since nothing in the repository claims either.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 26 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
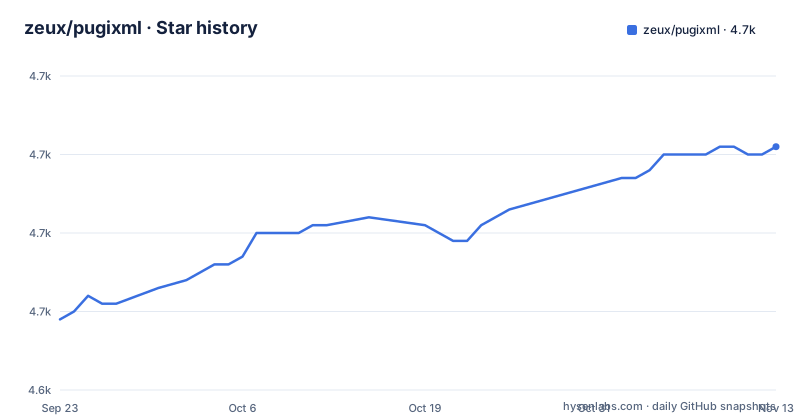
- zeux/pugixml4,671 ★ · +22
| Repository | 2026-09-23 | 2026-11-13 |
|---|---|---|
| zeux/pugixml | 4.6k | 4.7k |
22 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three things in one library: a parser, a tree, and XPath 1.0
The design is a compact stack rather than one feature. There is a parser described as extremely fast, which constructs the DOM tree from an XML file or buffer. On top of that sits a DOM-like interface with what the project calls rich traversal and modification capabilities. On top of that sits an XPath 1.0 implementation for data driven tree queries. The examples show what that layering buys you. The first program opens a file, walks Profile, then Tools, then iterates every Tool child by name and reads attributes; the second does the same filtering in a single select_nodes call with the predicate `[@Timeout > 0]`. Nothing else is needed for either style, which is why the library ends up embedded in other people's products. The homepage is pugixml.org, the default branch is master, and the licence is MIT.
load_file hands back a result object, and the example checks it first
Look at how the examples open a document. Both declare a parse result, load the file into it, and bail out when the result is false:
#include "pugixml.hpp"
#include <iostream>

int main()
{
    pugi::xml_document doc;
    pugi::xml_parse_result result = doc.load_file("xgconsole.xml");
    if (!result)
        return -1;
That shape is the API's opinion about failure. Parsing does not throw by default; it returns something you can test, which suits code that has to survive a malformed file from somewhere else. Exception support itself is a build-time setting: the Makefile adds -fno-exceptions when PUGIXML_NO_EXCEPTIONS is among the defines:
ifneq ($(findstring PUGIXML_NO_EXCEPTIONS,$(defines)),)
	CXXFLAGS+=-fno-exceptions
endif
So the exception story is decided once, for the whole build, and a project that mixes pugixml with code that relies on exceptions has to make that choice deliberately rather than discovering it later.
Unicode conversion happens inside parse and save
Full Unicode support is not a separate library you link; it comes as interface variants plus conversions between encodings, and those conversions happen automatically during parsing and saving. That single sentence carries most of the design weight for real files. In practice it means the encoding handling is not something each call site has to remember: you load a document and save it, and the encoding bookkeeping happens underneath. The practical consequence is that the common path stays short, while anyone who needs to control the encoding explicitly has to go to the reference manual, because the README text gives the guarantee rather than the API for it. The same pattern shows up elsewhere in this project: the headline capabilities are stated plainly and the surface for them lives in the documentation rather than in the summary.
Four config values decide what binary you get
The Makefile is small enough to read in one pass and it is the best description of the project's attitude. Three variables have defaults: config is debug, defines is standard, cxxstd is any, and the build directory name is composed from all of them plus your compiler. The baseline flags are aggressive:
CXXFLAGS=-g -Wall -Wextra -Werror -pedantic -Wundef -Wshadow -Wcast-align -Wcast-qual -Wold-style-cast -Wdouble-promotion`-Werror` next to `-Wold-style-cast` means the library does not tolerate a C style cast or a shadowed variable in its own source. Four more config values add to that list: release appends `-O3 -DNDEBUG`, coverage appends coverage flags, sanitize appends `-fsanitize=address,undefined -fno-sanitize-recover=all`, and analyze appends `--analyze`. So switching to release is a one word change, and turning on the sanitizers is the same kind of change. There is also a CMakeLists.txt at the top level for projects that do not want make at all.
A fuzz target per test file, with a dictionary and a fork count
The tests directory feeds two very different build targets. The ordinary path compiles src/pugixml.cpp together with every tests/*.cpp file except the fuzz ones, links a single executable named test, and the test target just runs it. The fuzzing path is a pattern rule, so each fuzz source becomes its own binary and its own run:
fuzz_%: $(BUILD)/fuzz_%
	@mkdir -p build/$@
	$< build/$@ tests/data_fuzz_$* -max_len=1024 -dict=tests/fuzz_$*.dict -fork=16
Read the arguments and the testing philosophy is visible: a 1024 byte cap on input length, a dictionary per target supplying tokens the parser expects, and sixteen forked workers per run. The repository also carries a .codecov.yml and a codecov badge, plus appveyor.yml for Windows builds, so the same sources are compiled under more than one toolchain. For a parser, this is the part of the setup that matters most, because a malformed document is the normal case rather than the exception.
The quick start is described as incomplete, so budget for the manual
There are two documents and the project tells you which to read first and when to stop trusting it. The quick-start guide is meant to be enough to begin using the library. The complete reference manual describes all features in detail. Between them sits an honest warning: many important library features are either not described in the quick start at all or only mentioned briefly, and if you need more information you should read the manual. That warning is the practical planning input for an adopter. A feature list on the front page tells you the library does Unicode, XPath and traversal, and it does not tell you which of the encoding options, the parse flags or the XPath behaviours you are allowed to rely on. Expect to budget a second sitting for the manual, and note that the README has no comparison table against other XML libraries, so the feature list is the whole basis for a choice.
v1.16 shipped on the same day as the last commit
The release cadence is easy to read from the tags. v1.14 is dated 2023-10-01, v1.15 is dated 2025-01-10, and v1.16 is dated 2026-06-16, and the last push was on 2026-10-20. Gaps of a year and a half are normal here, which tells you two things about upgrading: patch level churn is not the pattern, and the release you pin is a considered one rather than a frequent one. Licence is MIT in LICENSE.md, and the library also carries heritage worth knowing about, since this work is based on the pugxml parser by Kristen Wegner from 2003, released into the public domain with contributions from Neville Franks. Top level governance is thin and modern: SECURITY.md, .gitattributes and a scripts directory for the release tarball.
Editorial conclusion
pugixml fits a C++ codebase that already has a DOM mindset and wants XPath without taking on a schema aware parser, and it fits commercial code because the licence is MIT. It does not fit a project that needs validation against a schema or DTD processing, since nothing in the repository claims either. Before you adopt it, read the complete manual rather than the quick start, because the quick start is described as skipping important features, and decide whether exceptions stay enabled, since a single define removes them at compile time.
Frequently asked questions
How can I parse XML using C++?
pugixml loads a document into a pugi::xml_document and returns a pugi::xml_parse_result you can test for failure. You then either walk the tree with child, children and attribute calls, or query it with XPath 1.0 through select_nodes.
how to install pugixml
The repository ships both a Makefile and a CMakeLists.txt at the top level, so you build it from source with your own toolchain. The Makefile defaults to a debug config and you switch it with values such as config=release, config=sanitize or config=coverage.
how to install pugixml on ubuntu
Nothing in the repository is platform specific: it is a C++ library with a Makefile and a CMakeLists.txt, and CI configuration for Windows sits in appveyor.yml. The README points new users to the quick-start guide at pugixml.org/docs/quickstart.html.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zeux-pugixml)Star history chart for your README
[](https://hysenlabs.com/projects/zeux-pugixml)Was this useful?