AlphaSift: auditable YAML stock screening with an optional LLM opinion
AI-native stock screening engine with full-market discovery, LLM ranking, risk-aware scoring, and auditable evaluation.
At a glance
- What is it?
- A Python screening engine that filters a full A-share snapshot with hard rules and factor scores, can blend a language model's ranking in at a configurable weight, and is unusually explicit about stale data because every cached fallback is labelled in the payload. Strategies are YAML files, the default provider order changes depending on whether you hold a Tushare token, and the recorded examples are dated and marked as output rather than advice.
- Who is it for?
- AlphaSift is a good fit if you want a screening pipeline you can audit and re-run rather than a black box that produces tickers, since the strategy files, the funnel counts and the fallback labels are all inspectable. Three things to weigh.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
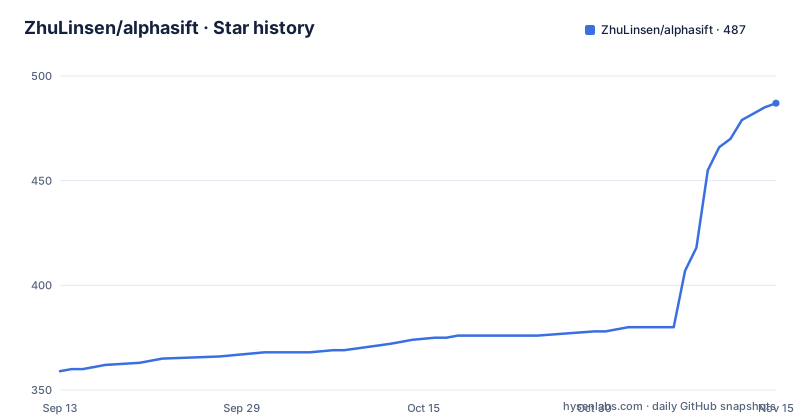
- ZhuLinsen/alphasift487 ★ · +128
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| ZhuLinsen/alphasift | 359 | 487 |
128 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three layers, and only the first one is required
The processing model is described as three numbered layers, and the layering is what makes the tool auditable. L1 is deterministic screening: hard filters and factor scoring applied to the full market snapshot, with no model involved and therefore no model to argue with when a candidate disappears. L2 is optional LLM ranking, which adds structured cross-candidate reasoning and returns theses, catalysts, risks, a confidence value and portfolio risk buckets rather than a single opaque number. L3 is pluggable post-analysis, where a local scorecard is used by default and DSA or external HTTP analyzers can be substituted. Around those sit four more capabilities: hotspot discovery for topic and sector heat with leader stock fallbacks and cache quality metadata, optional daily feature enrichment at the candidate level using moving averages, MACD and RSI, breakout strength, volume ratio, pullback distance and platform duration, an evaluation loop for saved runs, and an agent-native interface where SKILL.md describes the callable surface to an AI agent.
Strategies are YAML files that ship inside the package
The word auditable in the project's own description comes from the strategy format. Strategies are declared in YAML rather than in code, and the packaging configuration includes the strategy directory as package data for the alphasift package, so a strategy file is a reviewable artefact that travels with the distribution instead of a function you have to read to trust. The command line exposes them directly, with alphasift strategies listing the built-in strategies, and screening is then a strategy name plus flags, as in alphasift screen dual_low --no-llm. Two strategies are shown in the documentation with their recorded funnels. The dual low strategy takes a full market of 5190 stocks down to 337 after hard filters and outputs the top five, scored and annotated with price, change, price to earnings and price to book. The volume breakout strategy starts from the same 5190 and narrows to 126. The gap between those two numbers is the strategy, and it is legible without running anything. The whole loop fits in a handful of commands:
# Install in editable mode
pip install -e .

# List built-in strategies
alphasift strategies

# Run the no-key demo
alphasift quickstart

# Screen without LLM ranking
alphasift screen dual_low --no-llm
The model is a 0.40 weighted opinion, capped at 30 candidates
The LLM configuration defaults are the most useful thing in the file, because they show how much authority the model is actually given. LLM_RANK_WEIGHT defaults to 0.40, so deterministic scoring keeps the majority of the final score. LLM_MAX_CANDIDATES caps the list handed to the model at 30, and LLM_CANDIDATE_MULTIPLIER at 6 controls how many candidates are prepared relative to that. LLM_MIN_COVERAGE at 0.60 is a floor on how much of the candidate set the model must actually cover before its ranking is trusted, and LLM_MAX_RETRIES defaults to 1, so a failed call does not silently produce a half ranked list. LLM_MAX_TOKENS defaults to 2048, with the stated reason being that it keeps local servers from generating unbounded output after the client has already timed out. Context is bounded too, with LLM_CONTEXT_MAX_CHARS at 4000 and optional per-candidate news, announcement and fund-flow context limited to 8 candidates with 3 news items and 3 announcements each, cached for 24 hours.
Fallbacks are labelled in the data rather than hidden
The most defensible engineering decision here is refusing to pass off cached data as live data. When live constituent APIs fail and the engine falls back to last-good cached leaders, the returned stocks carry an explicit source field naming that path, along with a source confidence value and a fallback flag set to true, and the project states that this is intentional rather than a convenience. The hotspot cache file follows the same discipline, carrying a schema version currently at 2, a generation timestamp, and a metadata block recording the provider, row count, source errors and the stale or fallback state, with sidecar files written when history is requested. Detail responses keep the raw timeline for auditability while also exposing a compact route list grouped by day, newest first and trimmed for display, which falls back to a short current summary of heat, stage and leader when no timeline evidence exists. An agent consuming this can tell the difference between a live reading and a cached one without parsing prose.
The snapshot source order changes with a Tushare token
Data acquisition is a priority list rather than a single integration, and the default list is not fixed. Without a Tushare token the snapshot source priority defaults to efinance, then akshare's east money endpoint, then the east money datacenter. With a token, Tushare is prepended, giving Tushare, efinance, akshare and the datacenter in that order. The project is explicit that Tushare supplies the most recent trading day's daily and valuation data and is not a real-time quote feed, so a snapshot is a daily artefact and comparisons across intraday moments are not meaningful. Two settings exist for reproducibility: TUSHARE_TRADE_DATE pins a specific trading day in YYYYMMDD form so an experiment can be repeated, and ALPHASIFT_FALLBACK_SNAPSHOT_PATH points at a last-good snapshot file on disk. Sector and industry classification prefers a local mapping file, with the optional akshare sector reverse lookup turned off by default, which is the right default for a component whose classifications feed into scoring.
Evaluation is a separate pass over a saved run
The evaluation loop is what separates this from a screener that just ranks things. A run is saved, and it is evaluated later using newer snapshots rather than being judged at the moment it was produced. The evaluation deducts transaction cost, tags outcomes as follow-through or failed breakout, collects failure samples for review, and can optionally fetch price paths to compute maximum drawdown and maximum favourable excursion. Two helpers are exported from the package for this, one for a single saved run and one for several. The design implication is that the ranking function and the scoring of its results are kept apart, so a strategy can be changed and re-scored against the same historical snapshots without re-running the screen, and so a strategy that looks good on paper has to survive a cost-adjusted, path-dependent check before anyone relies on it. The Python surface for the main path is deliberately small:
from alphasift import screen

result = screen("dual_low", use_llm=False)
for pick in result.picks:
    print(f"{pick.rank}. {pick.code} {pick.name} score={pick.final_score:.1f}")
The two evaluation helpers, for a single run and for several, are exported from the same package.
Five data providers and a LiteLLM config borrowed from elsewhere
The dependency list explains both the data story and the intent. On the market side there are five providers, with efinance, akshare, baostock, Tushare and yfinance, which is one provider too many for a clean design and exactly what you end up with when a project has to work across mainland market feeds and international ones. On the model side it depends on LiteLLM rather than on a vendor SDK, and the configuration deliberately reuses the shape used by another project, with a documented precedence order where a LiteLLM router YAML file wins over multi-channel configuration, which wins over a single model name. Legacy variable names are still accepted, and any OpenAI-compatible or Ollama endpoint can be used, which is what makes a local model a one-line change. Provider keys are only needed for the L2 layer, so the deterministic path runs with no key at all, and there is a separate no-key demo command for checking an install.
The worked examples are dated and marked as output, not advice
The documentation is careful about its own numbers in a way most project readmes are not. The screening examples are stated to have been run on April 12, 2026, using the previous trading day's A-share closing data from April 10, 2026, with LLM ranking disabled, and they are labelled explicitly as examples of engine output rather than recommendations. The same restraint appears in the disclaimer, which says the project is for learning, research and engineering experiments, is not investment advice or a return guarantee or a buy or sell instruction, that outputs depend on third party data, optional LLM providers, local configuration and strategy parameters and can be delayed, incomplete, wrong or unsuitable for real trading, and that users are responsible for independent research, compliance checks, transaction costs, liquidity risk, announcement timing and every resulting decision. For an engine that ranks securities, having that paragraph in the readme rather than in a terms of service page is the minimum acceptable posture.
Editorial conclusion
AlphaSift is a good fit if you want a screening pipeline you can audit and re-run rather than a black box that produces tickers, since the strategy files, the funnel counts and the fallback labels are all inspectable. Three things to weigh. The LLM layer is optional and off by default in every documented example, so the deterministic path is the one you should validate first. Data freshness is bounded by the providers, and the project says so plainly: the Tushare path returns the most recent trading day's daily and valuation data rather than live quotes. And the licensing of the underlying data is your problem, since the engine inherits whatever terms come with the provider you point it at. The last push was on 2026-07-03, the manifest version is 0.2.0, and there are no tagged releases.
Frequently asked questions
What is AlphaSift?
It is an agent-friendly stock discovery and ranking engine, Apache-2.0 licensed and requiring Python 3.10 or newer. It scans a broad market universe, applies auditable YAML strategies, enriches candidates with optional market context, ranks them with deterministic factors plus optional LLM judgment, and saves runs so they can be evaluated later against newer snapshots.
Do I need an LLM API key to use AlphaSift?
No. Deterministic screening at layer one runs without one, which is how every documented example is run with the --no-llm flag, and the Python API exposes the same path through screen with use_llm set to false. A provider key is only required for the optional LLM ranking layer, and there is a separate no-key demo command.
Which market data sources does AlphaSift use?
Five providers, with efinance, akshare, baostock, Tushare and yfinance as declared dependencies. The snapshot source priority defaults to efinance, then an akshare east money endpoint, then the east money datacenter, and Tushare is prepended when a token is present. The project notes that Tushare supplies the most recent trading day's daily and valuation data rather than real-time quotes.
How does AlphaSift mark stale or cached data?
Explicitly, in the payload. When live constituent APIs fail and cached leaders are used, returned stocks carry a source field naming that path, a source confidence value and a fallback flag set to true, and the hotspot cache records schema version, generation time and metadata including provider, row count, source errors and stale or fallback state.
Is AlphaSift investment advice?
No, and the readme says so in a disclaimer. It is presented as being for learning, research and engineering experiments, not as investment advice, a return guarantee or a buy or sell instruction, with the note that outputs can be delayed, incomplete, wrong or unsuitable for real trading, and that users carry responsibility for research, compliance, transaction costs, liquidity and every resulting decision.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zhulinsen-alphasift)Star history chart for your README
[](https://hysenlabs.com/projects/zhulinsen-alphasift)Was this useful?