SAG keeps events and entities in SQL and builds the hyperedge only when you ask
A new SOTA for RAG — an original retrieval architecture and an open-source knowledge base for humans and agents.
At a glance
- What is it?
- The Zleap-AI knowledge base sells itself as a third retrieval architecture that joins chunks with SQL at query time instead of maintaining a GraphRAG graph; the code that backs it is a Next.js web app, a Python API on SQLite and LanceDB, and a compose file whose defaults include a secret the application refuses in production.
- Who is it for?
- SAG fits a single user or one team who wants citations back to original chunks, a source of truth they can query through an API or MCP, and a database that starts as two files instead of a server. It does not fit a multi-tenant deployment without work, because the shipped auth mode is machine identity and registration closes after the first credential.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
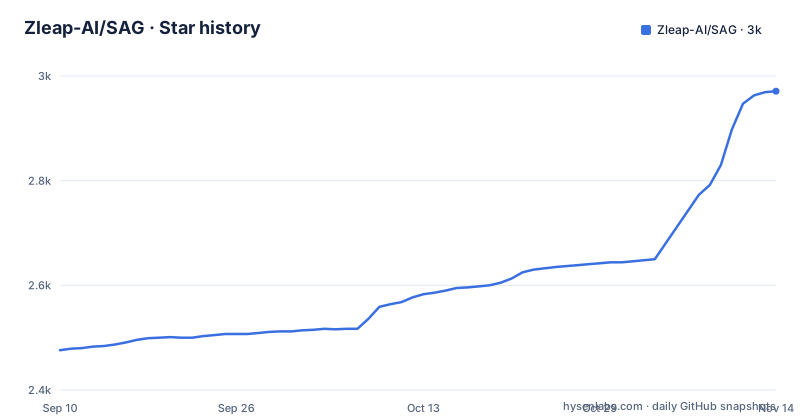
Star history
- Zleap-AI/SAG2,971 ★ · +495
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| Zleap-AI/SAG | 2.5k | 3k |
495 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
SQL joins at query time instead of a graph kept up to date
The pitch is a third architecture rather than a blend. Dense RAG retrieves chunks by semantic similarity, GraphRAG adds offline graph construction and pays for triple extraction, entity merging, relation normalization, global maintenance, and difficult incremental updates. SAG stores the meaning once and lets relational queries assemble the rest:
chunk → one semantically complete event
chunk → multiple indexing entities
event ↔ entities → one latent hyperedge
An event carries the complete meaning of its chunk instead of being fragmented into independent triples. An entity is a lightweight index and an expansion point, not a replacement for that meaning. The hyperedge is the piece that is never stored: it is created locally when SQL joins the events that share entities around the current query, and nothing is pre-built or maintained globally. Indexing parses a document into chunks, pulls one event and several entities out of each, persists all of it to relational storage, and writes chunk, event, and entity representations to vector and full-text indexes. Retrieval finds seed entities and events with semantic and lexical signals, expands through joins into a local candidate space, builds only the hyperedges this query needs, deduplicates, and returns the original chunks. A new chunk therefore adds its own rows instead of forcing a graph rebuild. Original evidence stays the output boundary: whatever events win selection map back to the chunks they came from, which is what makes the clickable citations in a chat answer possible rather than a separate feature.
Fast is vector, Precise is multi, and the same switch drives Dify
Search has two modes and two scopes. Retrieval can run globally or be narrowed to the sources you selected, and the mode is either Fast, named `vector`, or Precise, named `multi`. The optional Dify endpoint, which exposes this app as an external knowledge base to Dify, carries the same two-way switch and ships with `SAG_DIFY_SEARCH_STRATEGY` set to `vector` for lower request latency, while `multi` is described as entity expansion plus LLM reranking, so the slower mode buys its accuracy with another model call. That endpoint refuses service while `SAG_DIFY_API_KEY` is empty, which is the shipped default, so the integration stays inert until someone runs `make setup-dify`, which shells out to `python3 scripts/setup_dify.py` to generate and store the key. A separate `compose.dify.yaml` sits at the root beside the default compose file, and the same knowledge can leave the app four ways: a self-hosted REST interface with an OpenAPI description, an OpenAI-compatible chat endpoint, MCP, or the `zleap-sag` Python package, with source tracing promised on any result or citation.
The benchmark margin is the project's own measurement
Three datasets, one configuration, and margins that belong to the authors: HotpotQA, 2WikiMultiHopQA, and MuSiQue, all under the same `BGE-Large-EN-v1.5` embedding and `Qwen3.6-Flash` LLM. Averaged across them, the project reports 90.07% Recall@5 and 72.96% F1, ahead of the strongest per-metric baseline by 6.79 and 4.33 points, and on MuSiQue, the hardest of the three, by 11.52 and 7.01. The claim attached to those numbers is the best retrieval and end-to-end QA performance on every benchmark. The method sits in an arXiv paper numbered 2606.15971 with seven named authors, and the reproduction scripts are promised in a separate SAG-Benchmark repository rather than in this one. No outside reproduction appears in this project's files and no third-party score is quoted anywhere, so read the numbers as what one team measured on its own harness.
One repository, two version lines, and two desktop builds
The tag list runs two version lines side by side. The plain line is at v1.8.11, dated 2026-09-23. Two days later come `fnos-v1.5.10-fnos` and `fnos-v1.5.11-fnos`, described as native x86 fnOS builds, and those tags carry a 1.5.x core version while the main line sits at 1.8.x, so the two lines number themselves independently. Three names describe one artifact: the repository is SAG, the package on PyPI is `zleap-sag`, and the module the local server imports is `sag_api`. Publishing runs through a script rather than a button, since `make release VERSION=1.4.0` calls `node scripts/release-public.mjs --tag-only`, the Makefile says it is for the reviewed public/main branch, and a dry-run target checks the conditions without creating anything. The desktop side has two rows and one asymmetry: `SAG-*-mac-arm64.dmg` for macOS 15 on Apple Silicon is signed and notarized, while `SAG-Setup-*-win-x64.exe` for Windows 10/11 on x64 is unsigned for now and Windows may show an unknown-publisher warning. Both rows say in-app updates need a separate download and an install confirmation, no Intel Mac row is listed, and the sentence introducing the desktop app ends mid-word at `Ap` in the file you can read.
A known weak secret in the compose file, refused in production
The default compose file starts the API with `SAG_SECRET_KEY` set to `dev-insecure-secret-change-me-in-production-0123456789`, and the comment beside it says the application rejects that known weak key once you switch to production. The weak default is therefore deliberate: it exists so `docker compose up -d --build` works with nothing to configure, and the refusal in production mode is the enforcement. `.env.example` says the same thing from the other side, asking production deployers to set a strong random value and offering `openssl rand -hex 32` as the command, while noting that a local dev run may leave it empty and let Compose fill in the development key. `SAG_ENVIRONMENT` defaults to `dev`, which is what decides between the two behaviours. CORS defaults to `http://localhost:3000`, the data directory is `/data/engine` with uploads beside it, and the database URL is a SQLite file whose four slashes mean the path is absolute inside the container. All of it lands in a single named volume, `sagdata`, which the compose comments say is written to in one place so rebuilding the containers does not lose it.
Registration is a one-time door and the auth mode starts at local
`SAG_AUTH_MODE` defaults to `local`, which the example environment file describes as identity by machine name, and `password` is the mode for email and password when the app is reached from outside. Either way `SAG_ALLOW_REGISTRATION` defaults to `false`, and the comment explains the shape of the limit precisely: false still lets the first real credential be created, and registration is refused from then on. Combined with the claim that the product is deliberately local-first and single-user, that is one account for the lifetime of an installation rather than a user system with roles. The rest of the exposure surface hangs off one variable, because `BIND_ADDRESS` is `127.0.0.1` in the example file with a note that LAN or server deployments should set `0.0.0.0`, and that same value feeds the compose setting which enables local discovery by default.
The Makefile binds 0.0.0.0 while the example file promises loopback
The example environment file states that the machine listens only on the loopback address by default and ships `BIND_ADDRESS=127.0.0.1`. The Makefile does something else.
cd apps/api && . .venv/bin/activate && uvicorn sag_api.main:app --reload --host 0.0.0.0 --port 8000The web target runs the Next dev server with `-H 0.0.0.0` as well, and both targets carry a comment saying they are reachable from the LAN. So the documented local development path listens on every host interface while the file describing the default says the opposite. Compose is a separate story: the API service there binds the host loopback, and the one extra endpoint, local discovery, is switched on by default with its bind address taken from `BIND_ADDRESS`, its comment saying the container needs it to recognise discovery requests forwarded through the Docker gateway. An endpoint that is on by default and reachable through a gateway deserves a second read before you widen that variable.
cd apps/web && npm run dev -- -H 0.0.0.0One embedding dimension setting you must not change later
Three variables decide vector storage. `SAG_EMBEDDING_SCHEMA_DIMENSIONS` is left empty, which means 1024, and it is the one that fixes the vector store schema and the validation of returned vectors; the file says plainly that existing knowledge bases must not have it changed. `SAG_EMBEDDING_REQUEST_DIMENSIONS` is the optional dimension sent to the embedding endpoint and follows the schema dimension when empty, with a worked example in the comments that Qwen3-Embedding-8B means 4096. `SAG_EMBEDDING_DIMENSIONS` survives as a compatibility alias, and the file asks new deployments to prefer the first two. Model and endpoint defaults are `bge-large-en-v1.5` and an OpenAI-compatible base URL, while `SAG_LOCK_LLM_CONFIG` stays false so the generation model can be changed from the settings page, with the reminder that an LLM configuration change needs a service restart. One default deserves a second look: `SAG_SAG_LANGUAGE` is `zh` while the benchmark configuration quoted above uses an English-labelled embedding model.
Editorial conclusion
SAG fits a single user or one team who wants citations back to original chunks, a source of truth they can query through an API or MCP, and a database that starts as two files instead of a server. It does not fit a multi-tenant deployment without work, because the shipped auth mode is machine identity and registration closes after the first credential. If you take the accuracy claims seriously, reproduce them from the separate benchmark repository rather than from the numbers in the README, and if you already have a knowledge base, do not touch the schema embedding dimension. On Windows, expect an unsigned installer and a publisher warning, and on an Intel Mac there is no desktop build listed at all.
Frequently asked questions
What is SAG and what does it replace?
It presents itself as an original retrieval architecture rather than a combination of dense RAG and GraphRAG. Chunks become events plus indexing entities, and SQL joins over shared entities create the hyperedge at query time instead of maintaining a graph offline.
What does SAG need to run?
SQLite and LanceDB, with no external database service. The desktop app bundles the web workspace and the local knowledge backend, so that path needs no Python, no Node.js, and no database; the source path installs both with `make install`.
What is the difference between the Fast and Precise search modes?
Fast is `vector` and Precise is `multi`. The optional Dify endpoint uses the same switch, defaults to `vector` to lower latency, and describes `multi` as entity expansion plus LLM reranking.
Can I change SAG's embedding model without breaking an existing knowledge base?
Leave `SAG_EMBEDDING_SCHEMA_DIMENSIONS` alone once data exists. An empty value defaults to 1024 and that schema dimension drives both the vector store schema and the validation of returned vectors; use `SAG_EMBEDDING_REQUEST_DIMENSIONS` for the request-side value, which follows the schema when empty.
Is the SAG desktop installer signed on Windows?
Not yet. The macOS Apple Silicon disk image is signed and notarized, while the Windows x64 installer is unsigned for now, so Windows may show an unknown-publisher warning. On both platforms an in-app update needs a separate download and an install confirmation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zleap-ai-sag)Star history chart for your README
[](https://hysenlabs.com/projects/zleap-ai-sag)Was this useful?