PrivateGPT: a fixed Python 3.11 pin, and two Claude features it does not have
Complete API layer for private AI applications on local models: RAG, skills, tools, MCP, text-to-sql, and more. Works with any OpenAI-compatible inference server.
At a glance
- What is it?
- PrivateGPT is an Apache-2.0 API layer that sits between your application and a model server you run yourself, following the Claude API as its reference. It ships no model of its own, it pins Python to 3.11 exactly, and its own compatibility table marks prompt caching and OAuth as absent.
- Who is it for?
- Adopt PrivateGPT when you want one API surface across several local models, want retrieval with citations and database access without rebuilding those primitives, and can commit to Python 3.11 as the only supported interpreter.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
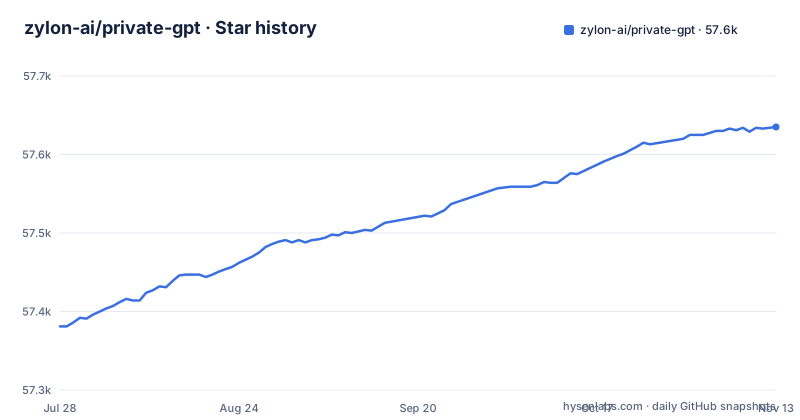
Star history
- zylon-ai/private-gpt57,635 ★ · +254
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| zylon-ai/private-gpt | 57.4k | 57.6k |
254 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It never runs a model, it points at one through OPENAI_API_BASE
The single most important line in the README is the disclaimer: PrivateGPT does not run models itself. It connects to any OpenAI-compatible inference server through the OPENAI_API_BASE environment variable, and the test of compatibility is short. If the server implements /v1/chat/completions and /v1/models, it works. The architecture diagram shows three layers, your application or agent or workflow or UI, then the PrivateGPT API, then an OpenAI-compatible server with Ollama, llama.cpp and vLLM named as examples. Everything above that line is the product: a messages API with streaming, async and token counting, file and artifact ingestion, retrieval with citations and agentic RAG, tools mirroring the Claude API such as web search, web fetch and code execution, plus custom tools and MCP connectors. The consequence is that your first integration task is not an install, it is proving your inference server answers those two endpoints.
requires-python is bounded above by 3.12, so 3.11 is the only interpreter
pyproject.toml sets requires-python to >=3.11,<3.12, and that upper bound is the project's real platform requirement. The install commands reinforce it, since both the Linux and the Windows forms pass --python 3.11 to uv. The container agrees: the Dockerfile starts from python:3.11.10-slim-bookworm, an exact patch level. So a machine whose system Python is 3.12 or 3.13 does not qualify, and the documented route to a usable interpreter is uv, which is why the install script from astral.sh appears in the quickstart for both platforms. There is a second detail in the same commands: --find-links points at wheels.privategpt.dev/packages, a wheel index hosted by the project. The consequence is that the documented install command depends on that index being reachable.
The container derives its system packages from the extras you name
The Dockerfile takes an EXTRAS argument defaulting to core and then walks the list, setting four flags. Documents turn on for core or any of ingest, ingest-core, ingest-documents, ingest-markitdown and ingest-markup, and that installs libmagic1, libxml2, libxslt1.1, poppler-utils, libreoffice, pandoc and ghostscript. Media turns on for core, media, media-image, media-audio and media-video, which pulls in ffmpeg and libavcodec-extra. Web scraping turns on for core, tools and tool-web-scraping, with a list of browser libraries behind it, and database support turns on for core, tools, tool-database, database, database-postgres, database-mysql, database-mssql and database-db2. The consequence is that core is not a small default. A plain core image carries an office suite, a document converter and ffmpeg, while a narrower set of extras produces a much smaller image with those capabilities switched off at the system level, not merely at the Python level.
Three install routes assume three different things about your machine
macOS has a Homebrew tap, so the route is a tap followed by an install:
brew tap zylon-ai/tap
brew install private-gpt
Linux and Windows both go through uv instead, installing the project with the core extra. The Windows form is a PowerShell one-liner that fetches the uv install script and then runs uv tool install with --python 3.11 and the same find-links index. A fourth route is the container, and the README sends you to the quickstart guide for Docker rather than giving a docker command inline. The consequence for anyone comparing them: Homebrew manages the interpreter and dependencies its own way, uv manages them in a tool environment, and the image manages them at build time, so the same project ends up with three different upgrade commands and three different places to look when a transitive dependency breaks. Pick the one your machine already has tools for.
Starting it means pointing two variables at two ports
The quickstart starts the model server first. With Ollama the example is a pull of qwen3.5:35b for the LLM at about 24 GB, a pull of mxbai-embed-large for embeddings at about 670 MB, and then ollama serve. Only then does PrivateGPT start, with both endpoints supplied as environment variables, the chat one through OPENAI_API_BASE and the embedding one through OPENAI_EMBEDDING_API_BASE:
OPENAI_API_BASE=http://localhost:<llm-port>/v1 \
  OPENAI_EMBEDDING_API_BASE=http://localhost:<embedding-port>/v1 \
  private-gpt serve
The two ports are separate because retrieval needs an embedding model and generation does not, which is why a single-server setup still needs two values. The CLI entry point is private_gpt.cli.main:main, exposed as the private-gpt script. Those 24 GB are the real cost of this stack, and they are yours to host rather than billed per token.
Three rows of the compatibility table say no
The README carries a table comparing the Claude API against PrivateGPT, and reading the rows that are not fully ticked is the fastest way to decide whether it fits; only prompt caching and OAuth/organizations are marked not supported. Prompt caching is marked not supported, and OAuth and organizations is marked not supported, while token-based auth is supported. Skills are marked basic rather than complete. Structured outputs are marked inference-dependent, and vision is model-dependent, so both are pushed down to whatever server you point at. Batch and async processing is marked async only. Two rows go the other way: database querying and CSV and tabular analysis are built in rather than something you reach through tools, which is the project's own claim about where it adds value. The consequence: an application written against the Claude API ports cleanly except where caching, organisation accounts or strict structured output are load-bearing.
The workbench at /ui is a demonstrator, and the tests wipe a data directory
Two framing decisions are worth knowing before you build anything. The first is the UI. It ships at /ui on port 8080, and it can send messages, pick models from /v1/models, upload documents, test retrieval with citations, enable tools per chat, configure databases, MCP connectors, skills and custom tools, and inspect traffic through an API Debugger. The README is explicit that this is a demonstrator, not the core product, and that developers are expected to build their own applications on the API. The second is the test setup, where the Makefile test target removes the contents of the test local data directory before running, with PGPT_HOME pointed at the checkout, and a test-changed variant adds a git diff filter. So a test run is destructive to local_data under the test home, and the WIPE_PGPT_HOME default points at a real user directory rather than a throwaway. Four worker targets also exist, celery-worker, arq-worker, chat-worker and tools-worker.
Editorial conclusion
Adopt PrivateGPT when you want one API surface across several local models, want retrieval with citations and database access without rebuilding those primitives, and can commit to Python 3.11 as the only supported interpreter. Do not adopt it if your application depends on prompt caching or organisation level OAuth, since the project's own table marks both as not supported, or if you want a turnkey install with no model server, because the layer refuses to run a model itself. Verify four things first. That whatever server you point OPENAI_API_BASE at implements /v1/chat/completions and /v1/models, since that is the whole contract. That you can get a 3.11 interpreter, because requires-python is bounded above by 3.12. Which extras you install, since the container's system packages are derived from those names. And whether the built-in tools you need are enabled, since core is what turns on documents, media, web scraping and database support in the image.
Frequently asked questions
What is private GPT?
In this project it is an Apache-2.0 licensed open-source API layer for building AI applications on local models, covering RAG, skills, tools, MCP, text-to-sql, embeddings and orchestration. It follows the Claude API as its reference and ships a workbench UI at /ui for testing, while the API is the product.
How do I install private GPT?
On macOS, brew tap zylon-ai/tap followed by brew install private-gpt. On Linux, install uv from astral.sh and run uv tool install --python 3.11 with the wheels index at wheels.privategpt.dev. A running OpenAI-compatible server, Ollama being the easiest, is a prerequisite.
How do I install private GPT on Windows?
Through PowerShell, using the uv install script for Windows and then uv tool install --python 3.11 with the same find-links index and the private-gpt[core] extra. The Python version is not a preference: pyproject.toml bounds requires-python to >=3.11,<3.12.
Is private GPT free?
The software is Apache-2.0 licensed and free. The compute is not free but it is yours: the quickstart pulls qwen3.5:35b at about 24 GB plus an embedding model at about 670 MB, and the project states that PrivateGPT powers its own on-premise platform, Zylon.
What is the difference between private GPT and Ollama?
They occupy different layers. Ollama is named as the easiest starting point for the model server, and PrivateGPT connects to any OpenAI-compatible server through OPENAI_API_BASE, requiring /v1/chat/completions and /v1/models. PrivateGPT adds the application layer above that: messages, ingestion, retrieval with citations, tools and MCP.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zylon-ai-private-gpt)Star history chart for your README
[](https://hysenlabs.com/projects/zylon-ai-private-gpt)Was this useful?