AgentDock refuses both jobs it sits next to, and makes its two safety rails the compose file's defaults
Secure MCP runtime for AI agents to operate local machines, servers, and containers with multi-device orchestration.
At a glance
- What is it?
- A Go runtime that gives a model tool access to real machines, servers and containers over a protocol transport, with no chat interface and no inference of its own. Published ports default to loopback, the authentication token is interpolated in a form that refuses to start unset, and a fixed tunnel domain and a quick tunnel are both one flag away.
- Who is it for?
- The design decision worth respecting is the refusal. This runtime does not chat and does not run a model, so it can be pointed at every machine you own without becoming another thing that holds your keys, and the two safety rails are defaults rather than advice: the published port is a loopback address, and the compose file will not start without an authentication token because the value is interpolated in a form that fails on absence.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 7, 2026, and from our analysis. They are not legal advice.
Star history
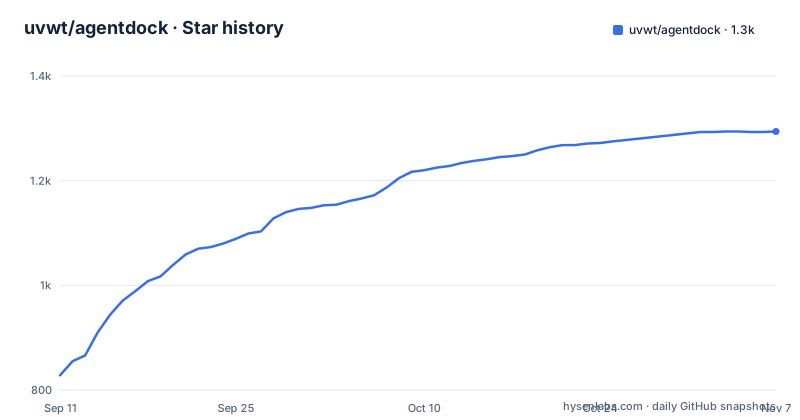
- uvwt/agentdock1,294 ★ · +466
| Repository | 2026-09-11 | 2026-11-07 |
|---|---|---|
| uvwt/agentdock | 828 | 1.3k |
466 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It refuses both jobs it sits next to, and says which one it keeps
The scope statement is two sentences long and both are refusals.
The document says AgentDock does not provide a chat interface and does not perform model inference. Then it states the one thing it does: let agents operate real environments within explicit permission boundaries and return structured, traceable, and verifiable results.
That is a useful boundary, because the tools are exactly the ones a chat product would want for itself. File read and write, command execution, version control, browser automation, deployment configuration, and a tunnel that publishes a machine to the internet. Any of these would be unremarkable inside a chat application and alarming in a standalone runtime that points at every machine you own. Putting the permission boundary and the traceable results in the same sentence as the refusal is the whole pitch.
The architecture diagram makes the shape concrete. Three model front-ends sit on top, a protocol transport with multiple instances supported, then three separate runtimes: one on a local Mac, one on a machine inside the network, one on a cloud server. Each exposes a different capability set, and the same client configuration points at whichever one it needs. Multiple instances connecting to each other is what makes a workflow that spans two machines possible in one conversation.
The opening pitch is worth reading for who it is aimed at. It describes managing several computers and servers from one chat window, writing code and running tests in the real environment, and doing so without consuming a dedicated coding agent's quota. That last clause is a competitive position rather than a feature: the intended user already pays for a coding agent and wants to point the same subscription's chat at something else.
Loopback by default, and the compose file will not start without a token
The container configuration contains the security model, and it is written in defaults rather than in advice.
The service listens inside the container on all interfaces and on one port. The published port, however, defaults to a loopback address on the host, and the environment block sets the internal host to all interfaces explicitly. So the exposure is narrow unless someone widens it, and a comment in the file says as much: because it binds all interfaces inside, an authentication token must be supplied.
The token is required in a stronger sense than a default. It is interpolated with the shell form that fails when the variable is absent, so bringing the stack up without setting it stops the tool rather than starting it unprotected. That is a better mechanism than documenting that a token is important, because the failure happens before anything is listening.
Three more defaults are worth naming. A health check runs a dedicated health check program every thirty seconds with a five second timeout, a ten second grace period on start, and three retries, and the tunnel profile depends on that check passing before it starts. Log files are capped at ten megabytes with five files kept, so a long-running server does not fill a disk. And a one gigabyte shared memory setting is applied to every image, including the ones that do not need it, with a comment explaining that the browser image's renderer wants more and that keeping it on ordinary images is harmless.
Two optional profiles sit beside it, both starting the same tunnel client. One is a quick tunnel, which takes an address from the service by name and passes a flag that disables the client's self-update. The other is a named tunnel that needs a token and a domain you own. The quick one is the one you will start by accident.
A Go runtime on a Node base image, running as a fixed non-root identifier
The container file is where the engineering decisions of a small team show up, and there are two that stand out.
The first is the base image. The build stage is a Go image pinned by content digest, which is correct and reproducible. The runtime stage is a Node slim image, also pinned by digest, and the reason is not fashion: the project does browser automation through a Chrome DevTools protocol client and ships skill packages that may be JavaScript, so the runtime needs a JavaScript toolchain and a browser present. A compiled binary that then depends on a Node base is the honest cost of that feature set, and paying it in a slim image rather than a full one is a reasonable middle.
The build stage is also careful. It copies only the module files and the two source trees it needs, which keeps the build context small, and it disables the C compiler and trims paths. It then injects the commit and the build date into the binary at link time through a small internal package, so a running instance can report which source it was built from. Both values default to a placeholder, so a build that forgets to pass them still succeeds with an honest unknown.
The second decision is identity. A group and a user are created at a fixed numeric identifier, a home directory is created for it, and three directories inside that home are created with owner-only permissions. Not a default-permission directory with a permission change later; the restrictive mode is set at creation. That matters for a tool whose whole job is writing files on your machine, and it is the kind of detail that is easy to skip and expensive to retrofit.
The binaries are then copied with explicit modes, and the core skills are staged into a temporary bundle path so the entrypoint can install them at first run rather than at build time.
Skills arrive with a digest, and there are three different origins
The skills system is the most interesting part of the capability list, and it reads like a supply-chain design rather than a feature list.
First, the division of ownership. Official and community skill content lives in a separate repository, and this repository keeps only the core skills that must ship with the runtime, named as the bootstrap and security skills plus a built-in user guide. So the set of things that can execute code on your machine is deliberately small in the artefact you download, and the rest is opt-in from elsewhere.
Second, how managed content is replaced. Install, update and remove of managed skill content are described as digest-based, meaning an update that produces identical content is a no-op, and replacement is atomic. Both halves matter: the digest stops a reinstall from churning a working directory, and the atomicity means a failed update does not leave you with half a skill.
Third, and most important, the isolation. Managed, shared and workspace skill sources are kept distinct, and the distinction is enforced with provenance references issued by the host rather than declared by the skill. So a skill cannot claim to be a managed skill, and a managed skill's environment variables and its persistent data are isolated from the package content itself. A skill that reads a directory it was handed cannot thereby reach the runtime's own state.
Alongside that is the dynamic server registry: register, enable, disable, refresh and remove, over two transports, with tools that can be searched, whose schemas can be inspected, and whose calls are controlled, plus configuration isolation between servers. Searching a tool before calling it and reading its schema first is the difference between an agent that knows what it is about to run and one that does not.
It can host a coding agent, and expose a tool for answering that agent's prompts
There is a nesting here that the feature list mentions once and does not dwell on.
The runtime can optionally act as a native client for the agent protocol and host a local coding-agent adapter. The desktop control panel provides presets for three named coding agents, and the host configuration decides both whether the integration is enabled and which adapter is selected. So an agent that arrived through a chat window can, on this machine, start a second coding agent.
Three tool names describe the interface. One creates and manages sessions. One runs prompts and lets the caller observe them. And one answers the inner agent's permission requests.
That third one is the part to think about. An agent controlling a machine can spawn another agent that also wants to run things, and the approval for the inner agent is now a tool the outer agent can call. The permission boundary that the scope statement advertises is therefore not a single wall; it is a wall with a door in it, and the door is a tool.
Nothing here says the nesting is unsafe, and a host-side control panel plus a per-session model is a reasonable design. But it means the answer to the question of who can run what on this machine is not fully described by the one sentence about explicit permission boundaries. If you enable the adapter, it is worth finding out what an outer agent may do with a permission request raised by an inner one, because the default answer is likely to be whatever the tool permits.
The protocol is a separate module pinned to a commit, and the runtime is ahead of it
The module file is short and tells you the dependency story of a small Go service.
Fifteen direct requirements. Among them: a pseudo-terminal library, which is how the interactive command sessions and terminal emulation work on Windows; a glob library; a browser automation pair built on the Chrome DevTools protocol, which is the native alternative to driving a browser through a scripting runtime; a websocket library; the model context protocol SDK; a JSON Schema validator; a tracing package and its trace component, which is presumably what the structured, traceable part of the scope statement is built on; two OAuth libraries; and a YAML parser.
The entry that deserves attention is a sibling module. The protocol this runtime speaks lives in a separate repository under the same organisation, and it is required at a pseudo-version, which in the Go ecosystem means a commit rather than a release. The pinned commit is dated the twenty ninth of September 2026, two days before the most recent push to this repository.
Now compare the version numbers. The newest tag on the runtime is zero point nine point one. The sibling module is at zero point eight point two. So the runtime's release line is ahead of the protocol it depends on by a minor version, and the dependency is pinned to a commit rather than to the newest commit either.
That combination is normal during active development and it has a consequence for anyone upgrading. There is no tag on the protocol side for you to pin to, so a rebuild of the runtime can pick up a different protocol than the one the binary was tested against, and the version numbers in the two repositories are not comparable. If the protocol is something you also depend on directly, treat the two as one change set rather than two packages.
Five installers, and three shapes of public address
The installation section is aimed at people who will never open the source, and it says so.
The statement is that regular users install from the official package for their operating system and do not need the source code or the Go toolchain. Then five paths are listed: a container path, an automated Linux install, a manual service-manager deployment for a Linux server, a macOS install, and a graphical Windows installer. The Windows entry is the notable one, since it is the platform that historically makes compiled tools awkward, and shipping a double-click installer says the team has done the work rather than leaving it to a package manager.
The connection section is where the risk lives, and it offers exactly three shapes.
Local only, where the client and the runtime are on the same machine. A temporary public address, for when a chat window, a phone, or another device needs access and no domain is ready, with the honest warning that the address may change after the tunnel restarts. And a fixed domain, for long-term use, which requires a domain managed by a particular provider and a tunnel token.
The middle option is the one people will use to test and then forget about. A chat client configured with a bearer token against an address that no longer resolves will simply fail to connect, and the diagnosis is not obvious from the client's side.
After installation you take the endpoint and either a bearer token or sign-in details from the control panel or the terminal and paste them into the client's connector settings. The configuration is a URL and an authorisation header:
{
  "mcpServers": {
    "agentdock": {
      "url": "http://127.0.0.1:8765/mcp",
      "headers": {
        "Authorization": "Bearer <AGENTDOCK_AUTH_TOKEN>"
      }
    }
  }
}
And two instructions that should be read as requirements rather than advice: public access must keep authentication enabled, and credentials must never appear in screenshots, issue reports, or public conversations. The second one is aimed at the people who will file the bug, which is the right audience.
Editorial conclusion
The design decision worth respecting is the refusal. This runtime does not chat and does not run a model, so it can be pointed at every machine you own without becoming another thing that holds your keys, and the two safety rails are defaults rather than advice: the published port is a loopback address, and the compose file will not start without an authentication token because the value is interpolated in a form that fails on absence. Check three things before exposing any of it. A quick tunnel gives you a public address that changes when the tunnel restarts, which is fine for an afternoon and wrong for anything you intend to rely on, so a named tunnel with your own domain is the one to choose deliberately. Skills are the real supply-chain surface here, since a managed skill can be installed and updated from outside the repository, so the digest-based replacement and the isolation of a skill's environment from the runtime's data directory are the mechanisms to verify rather than assume. And the protocol the runtime speaks lives in a separate module pinned to a commit rather than a release, at a version behind the runtime, so treat an upgrade as a coordinated change.
Frequently asked questions
What is AgentDock and what does it not do?
It is an independent Go runtime that gives AI agents file, command, version control, skill, protocol, browser automation and task execution capabilities across local machines, remote servers and containers. It explicitly does not provide a chat interface and does not perform model inference; it states one responsibility, which is letting agents operate real environments within explicit permission boundaries and return structured, traceable results.
How do I install AgentDock?
From the official package for your platform, without needing the source or Go. The documentation lists five paths: a container install, an automated Linux install, a manual service-manager deployment for a Linux server, a macOS install, and a graphical Windows installer. After installation you take the endpoint and a bearer token or sign-in details from the control panel or terminal and add them to your client's connector settings.
How does AgentDock protect a machine from being exposed?
Two defaults. The published container port is a loopback address on the host even though the service binds all interfaces inside the container, and the authentication token is interpolated in a form that makes the container stack refuse to start when the variable is unset. The document also states that public access must keep authentication enabled and that credentials must not appear in screenshots, issues, or public conversations.
What are the three ways to connect to AgentDock?
Local only, with the client and the runtime on the same computer. A temporary public address, where the address may change after the tunnel restarts. Or a fixed domain, which requires a domain managed by a particular provider plus a tunnel token. Both tunnel shapes are provided as optional profiles in the container configuration.
Where do AgentDock skills come from and how are they kept isolated?
Official and community skill sources live in a separate repository, and this repository keeps only the core skills that must ship with the runtime, namely bootstrap, security and a built-in user guide. Managed, shared and workspace sources are kept distinct using host-issued provenance references, managed skill environment variables and persistent data are isolated from package content, and updates use digest-based no-op with atomic replacement.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uvwt-agentdock)Star history chart for your README
[](https://hysenlabs.com/projects/uvwt-agentdock)Was this useful?