Apache Iggy: A Rust Message Log Built on io_uring and a Thread-Per-Core Design
Apache Iggy: Hyper-Efficient Message Streaming at Laser Speed
At a glance
- What is it?
- Apache Iggy is a persistent message streaming platform written in Rust that speaks QUIC, WebSocket, TCP and HTTP. It targets teams that want a Kafka-shaped log without the JVM, and it trades ecosystem breadth for low-level I/O control.
- Who is it for?
- Adopt Apache Iggy when you control the Linux hosts, your clients can use one of the shipped SDKs, and the operational cost of a JVM-based broker is the thing you are trying to remove. Do not adopt it if you need the Kafka connector ecosystem, a managed cloud offering, or non-Linux production hosts, because the README ties its best performance to io_uring and thread-per-core on modern Linux.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
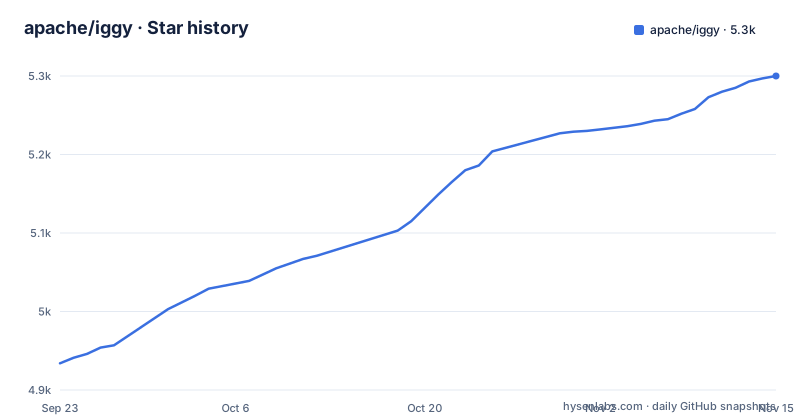
Star history
- apache/iggy5,300 ★ · +366
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| apache/iggy | 4.9k | 5.3k |
366 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Apache Iggy is, and the problem it removes
Iggy is a persistent, append-only message log. Producers write to it, consumers read from it, and the server keeps the data on disk. The README is explicit that this is not an extension running on top of Kafka or a SQL database: it is a log built from the ground up in Rust around low-level I/O. That framing matters because it defines the audience. If you already run Kafka and your team is comfortable with it, Iggy is not asking to replace your broker on day one. It is asking whether the broker itself, and the runtime it needs, is the part you want to keep paying for.
The intended user is an engineer who has felt the weight of a JVM-based streaming stack: heap tuning, garbage collection pauses, and a resource footprint that scales with the runtime rather than the workload. The README claims low latency and predictable resource usage specifically because Rust compiles to native code with no GC. Whether that claim holds for your traffic is something you would measure, not something the README can settle for you.
The naming is a deliberate signal. Iggy is short for Italian Greyhound, described in the README as small yet extremely fast dogs. The project is positioning itself as a small-footprint alternative, not as a superset of everything that came before it.
Thread-per-core, io_uring and the shared-nothing architecture
The mechanism the README leans on hardest is a thread-per-core, shared-nothing design combined with io_uring and compio. In practice that means the server does not funnel all work through a shared pool of threads contending on the same locks. Each core owns its work, and the kernel's asynchronous I/O interface is used to keep that core busy without blocking on syscalls.
This is a real architectural commitment with real consequences. The README states that thread-per-core plus io_uring gives the best possible performance on modern Linux systems. That sentence contains the limitation as well as the pitch: the design is tuned for Linux, and io_uring is a Linux interface. If your production hosts are not Linux, or your kernel is old enough that io_uring support is limited, you are outside the configuration the project optimizes for.
On top of the log itself, Iggy offers multiple transport protocols: QUIC, WebSocket, TCP with a custom binary specification, and HTTP as a regular REST API. The REST API is optional and can be enabled separately. The README also notes that Iggy works directly with binary data, avoiding enforced schema and serialization overhead, and uses custom zero-copy (de)serialization. That is a trade-off worth naming: no enforced schema means the server will not protect you from writing bytes your consumers cannot parse. Schema discipline becomes your responsibility, not the broker's.
Installing Apache Iggy with Docker Compose and running the CLI
The repository ships a Dockerfile and a docker-compose.yml, and that is the shortest path to a running server. The compose file defines one service, iggy-server, and maps four ports: 3000, 8080, 8090 and 8092. It also sets IGGY_NODE_ADVERTISED_ADDRESS to localhost, with a comment explaining that the image binds every listener to 0.0.0.0 and the address clients dial has to be declared separately. If you change the host clients use, that variable is the one to change.
services:
  iggy-server:
    container_name: iggy-server
    environment:
      - IGGY_NODE_ADVERTISED_ADDRESS=localhost
    ports:
      - 3000:3000
      - 8080:8080
      - 8090:8090
      - 8092:8092
That excerpt is the core of the compose service: one container named iggy-server, the advertised address set to localhost, and the four published ports. The compose file also requires IGGY_ROOT_PASSWORD (it is started as IGGY_ROOT_PASSWORD=... docker compose up -d), because the server refuses to start without root credentials; IGGY_ROOT_USERNAME defaults to iggy. If a port collides with something already on the host, the Dockerfile sets the listener defaults to override: IGGY_HTTP_ADDRESS=0.0.0.0:3000, IGGY_QUIC_ADDRESS=0.0.0.0:8080, IGGY_TCP_ADDRESS=0.0.0.0:8090 and IGGY_WEBSOCKET_ADDRESS=0.0.0.0:8092.
The Dockerfile builds two binaries from source: iggy, which is the CLI, and iggy-server. Both land in /build/target/release inside the builder stage and are copied into a debian:trixie-slim runtime image. The build stage installs build-essential, pkg-config, libssl-dev, libhwloc-dev, libudev-dev, nodejs and npm, then builds the web frontend before compiling the Rust binaries. Expect the first build to be slow, because it builds the web frontend and compiles both Rust binaries from source.
Once a server is up, the CLI is the first thing to try. The README links to a quickstart and includes a CLI section, and the repository has a core/cli workspace member. The client SDK is published on crates.io as iggy. Check the quickstart page for the exact invocation rather than guessing at flags.
Client SDKs, the Kafka gateway and the connector sinks
Iggy is not a single-language project. The README lists SDK badges for Rust (crates.io, package iggy), JavaScript (npm, package apache-iggy), Python (PyPI, package apache-iggy), Java (Maven Central, org.apache.iggy:iggy) and .NET (NuGet, package Apache.Iggy). The examples directory mirrors that with csharp, go, java, node, php, python, rust and swift subdirectories. Note the mismatch worth checking: Go, PHP and Swift appear under examples but not in the badge list, so confirm the SDK status for those before designing around them.
The workspace reveals more than the README's feature list. There is a core/ai/mcp member, which corresponds to the Model Context Protocol section in the table of contents, and a gateways/ directory at the top level alongside a Kafka gateway section. There is also a connectors tree with a long list of sinks: bigquery_sink, clickhouse_sink, delta_sink, doris_sink, elasticsearch_sink, http_sink, iceberg_sink, influxdb_sink, meilisearch_sink, mongodb_sink, postgres_sink, quickwit_sink, rabbitmq_sink and redshift_sink, plus a connectors runtime and SDK. That is a meaningful amount of outbound integration surface for a project this young.
The Kafka gateway is the pragma here. If it works as advertised, it lets existing Kafka clients talk to Iggy without a rewrite, which removes the biggest migration objection. The README lists it as a section, but compatibility level is not stated in the feature list, so treat protocol coverage as something to verify against your specific client library rather than assume.
Where Apache Iggy is the wrong tool
The clearest limitation is platform. The README ties peak performance to io_uring and thread-per-core on modern Linux. That is not a footnote; it is the core design. Running Iggy on macOS or Windows in production puts you outside the path the project optimizes, and the README does not present a comparable story for those platforms.
The second limitation is ecosystem depth. Iggy's connector list is long for its age, but it is not Kafka's. Kafka has years of third-party sinks, sources, managed services, monitoring integrations and accumulated operational knowledge. If your architecture depends on a specific connector that only exists for Kafka, Iggy's sink list is the thing to check line by line, and the README does not guarantee a match.
The third is schema. The README presents working directly with binary data and avoiding enforced schema as a feature, and for throughput it is. For a team that relies on the broker to reject malformed records, it is the opposite. Iggy will accept bytes. Your consumers will discover the problem later.
Finally, the security model is described in the feature list as user authentication and authorization with granular permissions and Personal Access Tokens, and lists TLS support for all transport protocols; the compose file shows the server refuses to start without root credentials (IGGY_ROOT_PASSWORD must be set, IGGY_ROOT_USERNAME defaults to iggy). Anyone putting this on a network should read the SECURITY.md file and the configuration docs before exposing a port.
Apache Iggy compared with Kafka and NATS
Kafka is the default comparison, and the difference is architectural rather than feature-by-feature. Kafka runs on the JVM and organizes data into topics and partitions with a consumer group protocol that has been reimplemented by many clients. Iggy runs as a native Rust binary and organizes data into streams, topics and partitions, with its own binary protocol on TCP plus QUIC, WebSocket and HTTP options. The practical difference is what you operate: a JVM with heap tuning versus a native process with io_uring. The practical cost is ecosystem: Kafka's client and connector surface is far larger.
NATS takes a different position again. NATS is built around lightweight subjects and a pub/sub core, with JetStream added for persistence. Iggy is a persistent log first; the README describes it as a persistent append-only log for message streaming, not as a messaging bus with persistence bolted on. If your workload is request/reply and ephemeral fan-out, a subject-based system is a closer fit. If your workload is a durable, replayable log, Iggy's model is the nearer one.
Pulsar is the third comparison people reach for, and the axis is the same as with Kafka: Pulsar separates compute from storage and brings its own operational model, while Iggy is a persistent log built around thread-per-core I/O on each node. The README has a Clustering section, and the feature list does not describe replication guarantees, so anyone evaluating Iggy for a multi-node deployment should read that section directly rather than infer from the feature list.
Licence, releases and what upgrades cost you
Iggy is licensed under Apache-2.0, and the repository carries both LICENSE and NOTICE files plus an ASF_LICENSE.txt and a licenserc.toml for licence header checking. The ASF governance model matters for adoption risk: the project is under the Apache Software Foundation, with a mailing list and a documented contribution process in CONTRIBUTING.md. For a company that needs a permissive licence with no copyleft obligations on the server, Apache-2.0 is the expected answer, but the NOTICE file is where attribution requirements live and it should be read rather than assumed.
Release cadence is visible. The most recent release in the repository is server-0.9.0, dated 2026-09-18. Before that came server-0.8.0 on 2026-04-22 and server-0.7.0 on 2026-02-25. That is a roughly two-month gap followed by a roughly five-month gap, which is not a fixed schedule. The version numbers are still in the 0.x range, so the project has not declared a 1.0 stability commitment. Treat minor version bumps as potentially breaking until the release notes say otherwise.
The upgrade cost is therefore not the download; it is the reading. A 0.x project that ships a new minor release every few months requires you to check the changelog before every bump. The repository has a cliff.toml, which suggests changelog generation is automated, so the notes should exist. Whether they cover configuration key changes is the thing to check on each upgrade.
Editorial conclusion
Adopt Apache Iggy when you control the Linux hosts, your clients can use one of the shipped SDKs, and the operational cost of a JVM-based broker is the thing you are trying to remove. Do not adopt it if you need the Kafka connector ecosystem, a managed cloud offering, or non-Linux production hosts, because the README ties its best performance to io_uring and thread-per-core on modern Linux. Before committing, verify three things yourself: that your client language has an SDK in the supported list, that the ports you need (3000, 8080, 8090, 8092) are free and reachable, and that the configuration keys your deployment depends on are documented for the server-0.9.0 release rather than only in the repository.
Frequently asked questions
What are the key differences between Apache Iggy and Kafka?
Iggy is a persistent message log written in Rust with a thread-per-core, shared-nothing design using io_uring, while Kafka runs on the JVM. Iggy supports QUIC, WebSocket, TCP and HTTP transports, and the README lists a Kafka gateway section, whose compatibility should be checked against your client.
What is Apache Iggy?
It is a persistent message streaming platform written in Rust, supporting streams, topics and partitions with user authentication and authorization. The README describes it as a log built from the ground up rather than an extension on top of Kafka or a SQL database.
Which ports does the Apache Iggy Docker image expose?
The Dockerfile sets IGGY_HTTP_ADDRESS to 0.0.0.0:3000, IGGY_QUIC_ADDRESS to 0.0.0.0:8080, IGGY_TCP_ADDRESS to 0.0.0.0:8090 and IGGY_WEBSOCKET_ADDRESS to 0.0.0.0:8092, and the compose file maps those same four ports.
Which programming languages have an Apache Iggy SDK?
The README lists client SDKs for Rust, JavaScript, Python, Java and .NET, published on crates.io, npm, PyPI, Maven Central and NuGet respectively. The examples directory also contains Go and PHP samples.
Does Apache Iggy support clustering?
The README table of contents includes a Clustering section, so the feature is part of the project. Read that section directly for replication guarantees and failover behaviour before planning a multi-node deployment.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apache-iggy)Star history chart for your README
[](https://hysenlabs.com/projects/apache-iggy)Was this useful?