Cayley: a Go graph database for Linked Data, and how to run it
An open-source graph database
At a glance
- What is it?
- Cayley is an open-source graph database written in Go and aimed at Linked Data workloads. Its Gizmo query language, HTTP server and LevelDB or Bolt backends make it a reasonable fit for read-heavy traversal work, provided you accept a slow release cadence and a thin operational story.
- Who is it for?
- Adopt Cayley if you need a Go-native graph store for read-heavy traversal over RDF-style quads and you are comfortable reading the GitBook docs and the source, since the last tagged release was v0.7.7 on 2019-10-15 while the master branch was last pushed on 2026-08-27. Do not adopt it if you need frequent tagged releases, a documented upgrade path between versions, or a query planner you can tune without reading the code.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 79 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
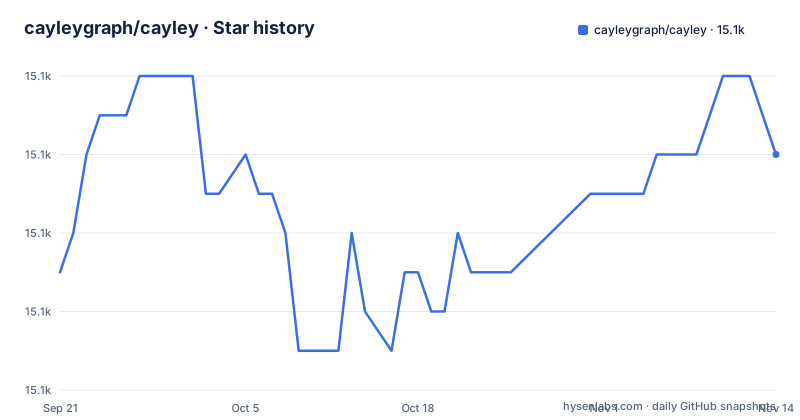
Star history
- cayleygraph/cayley15,068 ★ · +3
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| cayleygraph/cayley | 15.1k | 15.1k |
3 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Cayley is for, and who ends up using it
Cayley describes itself as an open-source database for Linked Data, the W3C's term for data published in RDF-style subject-predicate-object form. The README says it was inspired by the graph database behind Google's Knowledge Graph, formerly Freebase. That lineage explains the shape of the thing: it stores quads rather than rows, and it expects you to query relationships rather than join tables.
The people who reach for it are usually building something where the relationships are the data. A recommendation engine that walks from a user to the things they bought to the things other buyers bought. A knowledge base that merges entities from several sources and needs to answer "what connects these two nodes". A permissions or dependency graph that has to be traversed at request time rather than precomputed.
What separates Cayley from a general-purpose database with a graph extension is the query surface. It ships three query languages: Gizmo, which the README describes as inspired by Gremlin; a GraphQL-inspired language; and MQL, described as a simplified version for Freebase users. The repository also contains a built-in query editor, visualizer and REPL, which is unusual for a database of this size and is genuinely useful when you are trying to work out why a traversal returned nothing.
The honest framing is that Cayley is a traversal engine with several storage backends bolted underneath, not a storage engine with a graph layer bolted on top. That distinction matters when you start choosing where the quads actually live.
Quads, backends and the HTTP server on port 64210
The data model is the quad: subject, predicate, object, and a label. The repository's top-level entries include graph/, query/, schema/, server/ and writer/, and the go.mod file lists drivers for LevelDB (github.com/syndtr/goleveldb), Bolt (github.com/boltdb/bolt), SQLite (github.com/mattn/go-sqlite3), PostgreSQL (github.com/jackc/pgx/v5 and github.com/lib/pq) and MySQL (github.com/go-sql-driver/mysql). Cayley's own quad types come from a separate module, github.com/cayleygraph/quad. So the storage layer is pluggable, and the choice you make there determines almost everything about how the deployment behaves.
The read path goes through the server package, which is what the Dockerfile starts. The image's entrypoint is the http subcommand bound to port 64210, and the healthcheck runs a separate health subcommand. The Dockerfile also installs a persisted configuration at /etc/cayley.json and declares a volume at /data, with a comment warning that if you use a backend like bolt, the file has to live in that directory or it will not survive the container.
Query execution is where the design shows its age and its intent. The README's performance section reports that on 2014 consumer hardware and an average disk, 134m quads in LevelDB is manageable and a multi-hop intersection query (the README's example is films starring two given actors) takes about 150ms. Those numbers come from the README, they were measured over a decade ago, and they should be read as an order of magnitude rather than a specification. I would not plan capacity from them.
The modularity claim in the README is backed by the repository layout: the repository has client/, examples/ and inference/ directories alongside graph/, query/ and writer/.
Installing Cayley and loading your first graph
The README points at a Snap Store badge and at a GitBook documentation site; it does not reproduce install commands inline. The Dockerfile, however, documents the container workflow explicitly, and that is the most reproducible path in the repository.
The image is built from golang:1.22, compiles ./cmd/cayley, installs a persisted configuration at /etc/cayley.json, runs cayley init against it, and then starts cayley http bound to :64210. The Dockerfile's own comment gives the invocation pattern, including the --init flag and the -i flag for loading a data file:
docker run cayleygraph/cayley --init -i /data/my_data.nqThe -i argument names a file in N-Quads format, and /data is the declared volume, so the loaded graph persists across container restarts. Expect the server to come up on port 64210 and the healthcheck to start probing it after a five second start period.
If you would rather build from source, the go.mod file declares go 1.22 with a toolchain of go1.22.5, and the Dockerfile builds ./cmd/cayley with version information injected through ldflags into github.com/cayleygraph/cayley/version. The repository also ships cayley_example.yml at the top level and a configurations/ directory containing persisted.json, which is the file the Docker build moves to /etc/cayley.json. Reading those two files together is the quickest way to understand which backend the default configuration selects.
For a first query, the REPL and the built-in query editor are the lowest-friction entry points, since they need no client library. The examples/ directory contains hello_world, hello_bolt, hello_schema and transaction, plus a top-level examples/README.md, and those are the closest thing to a guided tour that the repository offers.
Where Cayley gets in the way
The release history is the first thing to weigh. The most recent tagged release is v0.7.7 from 2019-10-15, preceded by v0.7.6 the day before and v0.7.5 in 2018. The master branch was last pushed on 2026-08-27, so development has not stopped, but it has not been packaged into a release for a long time. Anyone who pins a version number is pinning code from 2019, and anyone who wants current code has to build from master and accept that master is not a release.
That gap has a concrete consequence: the go.mod on master declares go 1.22 and a toolchain of go1.22.5, while the v0.7.7 tag dates from 2019. If you build from a tag, you are building against a dependency set that the current repository has moved past, and the README does not document how to move between versions or what changed.
The second limitation is operational. The Dockerfile declares a /data volume and warns that a Bolt file must be written there, which is a hint about how easy it is to lose a graph by mounting the wrong path. There is no documented backup, compaction or replication procedure in the README. For a single-node analytical workload that is tolerable. For anything that needs a replica set or point-in-time recovery, it is not.
The third is scope. Cayley is a read-optimised traversal engine. The README's own performance note is about a multi-hop intersection query, which is the workload it was designed for. If your problem is high-volume transactional writes with occasional graph lookups, a relational database with a recursive CTE will be less machinery than this.
Cayley against a property-graph database like Neo4j
The obvious comparison is Neo4j, and the difference is not performance, it is the data model and the query language philosophy.
Neo4j is a property graph database. Nodes and relationships carry arbitrary key-value properties, and Cypher is a declarative pattern-matching language where you draw the pattern you want and the engine finds it. It is a self-contained system with its own storage engine, its own transaction model and its own clustering story.
Cayley is an RDF-style quad store with a pluggable backend. There are no properties on a node; if you want to attach an attribute, you add another quad. Its Gizmo language is procedural rather than declarative: the README describes it as inspired by Gremlin, which means you build a traversal step by step rather than describing the shape of the result. The GraphQL-inspired language and MQL offer different trade-offs within the same engine.
The practical consequence is that Cayley's storage choice is yours. You can run it against LevelDB for a single-node analytical job, or against PostgreSQL if you already operate one. Neo4j makes that decision for you. Cayley also gives you the visualizer and REPL in the box, which Neo4j matches with its own browser tooling.
If your team already thinks in Cypher and wants a managed graph product, Cayley is the wrong shape. If your data is already RDF and you want to keep it that way, or you want to reuse an existing PostgreSQL instance as the store, Cayley's backend modularity is the reason to look at it.
Licence, maintenance and what an upgrade actually costs
Cayley is licensed under Apache-2.0. That is a permissive licence: it permits commercial use and modification, and it includes an explicit patent grant, which matters if you are embedding the database in a product. It also means that if you fork and distribute a modified Cayley, you must preserve the licence and the notices. The repository carries AUTHORS, CONTRIBUTORS and CODEOWNERS files, so provenance is traceable. None of this is legal advice; if you are shipping Cayley inside a product, have counsel read the Apache-2.0 text rather than a summary of it.
The maintenance picture is mixed and worth stating plainly. The repository is not archived. The last push to master was on 2026-08-27, which is recent. The last tagged release, v0.7.7, was on 2019-10-15. Those two facts together describe a project where the code moves but the release process does not, and that has a direct cost: you cannot track upstream by bumping a version number in a manifest. You either stay on a 2019 tag or you vendor a commit from master and re-vendor it yourself.
Upgrading between the tagged releases is also undocumented in the README. There is no migration guide, no changelog excerpt, and no statement about on-disk format compatibility between v0.7.5, v0.7.6 and v0.7.7. If you store a graph in a Bolt or LevelDB file, assume you will need to export and re-import rather than upgrade in place, and test that assumption on a copy before you touch production.
Editorial conclusion
Adopt Cayley if you need a Go-native graph store for read-heavy traversal over RDF-style quads and you are comfortable reading the GitBook docs and the source, since the last tagged release was v0.7.7 on 2019-10-15 while the master branch was last pushed on 2026-08-27. Do not adopt it if you need frequent tagged releases, a documented upgrade path between versions, or a query planner you can tune without reading the code. Before committing, verify three things: that the backend you intend to use (LevelDB, Bolt, SQLite, PostgreSQL or MySQL) is the one your data volume fits, that the Gizmo or GraphQL query language covers the traversals you actually need, and that you can build the master branch yourself, because the tagged releases predate the current go.mod.
Frequently asked questions
What is Cayley in the context of this Go graph database?
Cayley is an open-source database for Linked Data, written in Go and licensed under Apache-2.0. The README says it was inspired by the graph database behind Google's Knowledge Graph, formerly Freebase, and it stores data as quads rather than rows.
How do you install and start the Cayley graph database server?
The Dockerfile builds an image whose entrypoint is the http subcommand bound to port 64210, with a persisted configuration at /etc/cayley.json and a volume at /data. The README also links a Snap Store badge and points to a GitBook documentation site for other install paths.
Which query languages does Cayley support?
The README lists three: Gizmo, described as inspired by Gremlin; a GraphQL-inspired query language; and MQL, described as a simplified version for Freebase users. The repository also includes a built-in query editor, visualizer and REPL.
What storage backends can Cayley use?
The go.mod file lists drivers for LevelDB, Bolt, SQLite, PostgreSQL and MySQL, and the README describes the project as modular so it can connect to different back-end stores. The choice of backend determines the operational behaviour of the deployment.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cayleygraph-cayley)Star history chart for your README
[](https://hysenlabs.com/projects/cayleygraph-cayley)Was this useful?