SayIt: open-source voice typing for Windows with local GGUF models
Open-source voice typing for Windows — a Wispr Flow / Superwhisper alternative. Press a shortcut, speak, and AI-polished text lands at your cursor. Local models, your own API keys, or a self-hosted backend.
At a glance
- What is it?
- SayIt is a Windows dictation app that transcribes speech and inserts polished text at your cursor, with local recognition, your own API keys, or a self-hosted backend. It is early software, and the licence shapes who can ship it.
- Who is it for?
- Adopt SayIt if you dictate on Windows and want the recognition path to stay on your machine, or if you are willing to run the FastAPI backend yourself. Do not adopt it if you need macOS or Linux support, or if you plan to embed it in a closed-source product, because AGPL-3.0 reaches network use.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 11 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 20, 2026, and from our analysis. They are not legal advice.
Star history
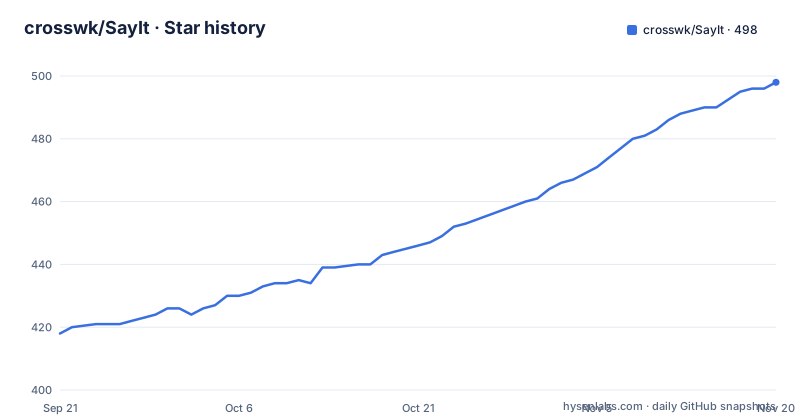
- crosswk/SayIt498 ★ · +80
| Repository | 2026-09-21 | 2026-11-20 |
|---|---|---|
| crosswk/SayIt | 418 | 498 |
80 Stars in the last 60 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem SayIt targets: typing is the slow part of working with AI
SayIt's own framing is that typing is often the slowest part of working with an AI assistant. You have a thought, you type it, you fix the typos, you send it. The project's answer is to make speech the input path and put the cleanup step in the same loop. Press a shortcut, speak, and the app transcribes, cleans up, and inserts the result at the cursor, without switching windows.
The audience is narrow and specific: Windows users who dictate into editors, chat apps, and browsers. The repository is TypeScript with a Tauri client on one side and a FastAPI server on the other, and the topics list local-first, privacy, and self-hosted alongside wispr-flow-alternative and superwhisper-alternative. That tells you the intended comparison set. The pitch is not a general transcription service. It is a replacement for the paid dictation tools that send your audio to someone else's servers, with the processing location left as your decision.
What makes it more than a shortcut wrapper is the cleanup stage. The README describes an editable AI cleanup step that removes filler words, repairs recognition errors, and formats ideas, with built-in presets that you can change. If you would rather have a faithful transcript, the documentation says that is a choice too. That is the part most dictation tools do not expose.
How the three voice engine modes change where your audio goes
The README lays out three modes, and the difference is entirely about data flow. In Local mode, speech recognition stays on your PC, and with AI cleanup off, the documentation states that nothing leaves the device. In Cloud API mode, your PC talks directly to the ASR and AI providers you configure, with no SayIt server in the path. In Server mode, audio is processed by a SayIt backend you control, or by the public trial server if you just want to try it.
Local recognition ships seven GGUF models with GPU acceleration when available. The list includes Parakeet Unified EN, which the README calls the fastest and most accurate for English, plus SenseVoice Small, Fun-ASR Nano, Nemotron 3.5 ASR covering 32 languages, and three Qwen3-ASR sizes. Cloud recognition supports Doubao, Qwen, Xiaomi MiMo, and Groq Whisper. AI cleanup works with DeepSeek, Qwen, Groq, MiMo, Ollama, and any OpenAI-compatible endpoint.
Two features deserve a closer look because they are where the design gets interesting. Context-aware writing is off by default and reads the text around your cursor so new dictation matches tone and terminology; the README says password fields are skipped. If you select text first, your speech becomes an editing instruction and replaces the selection. That is a real editing model, not just insertion. The second is per-app rules, which switch cleanup presets based on the app you are typing into. Both sit on top of the transcription layer rather than inside it, which is why they are optional.
Installing SayIt on Windows and dictating your first sentence
The desktop client is distributed as a Windows installer from the releases page. The README's get-started steps are three: download the latest installer, open SayIt and choose a voice engine, then press the configured shortcut in any app and speak. The default public server is described as enough for a quick trial, which means you can evaluate the interaction before configuring anything.
The default shortcut behaviour is press once to start and again to finish. Hold-to-talk exists too, but the README places it under a separate shortcut, so you have to assign it rather than assume it is the default.
# No install command: download the Windows installer from
# https://github.com/crosswk/SayIt/releases/latest
For regular use, the recommendation is Local mode or your own cloud provider keys, configured from the in-app settings. The README notes that provider console links sit beside each key field, which shortens the loop between deciding on a provider and getting a key.
If you want to build the client from source rather than use the installer, the development path is a Tauri build. The first native build compiles the C++ speech engine and the README warns it may take around 20 minutes; later builds use the cache.
cd client
npm install
npm run tauri dev
The stated requirements are Node.js 18+, Rust 1.75+, CMake 3.20+, and the Vulkan SDK. There is one platform-specific note worth catching before you file a bug: on non-English Windows installations, set `CL=/utf-8`.
Self-hosting the SayIt backend with Docker Compose
Server mode is the option for teams and managed deployments, and the README recommends Docker Compose as the deployment path. The backend combines FastAPI, WebSocket streaming, Qwen3-ASR, and an optional OpenAI-compatible cleanup model.
git clone https://github.com/crosswk/SayIt.git
cd SayIt/server
cp config.example.yaml config.yaml
cp .env.example .env
# Add your provider and deployment settings to .env/config.yaml
docker compose up -d --build
The setup copies two example files and expects you to fill in provider and deployment settings before bringing the stack up. GPU speech recognition requires an NVIDIA GPU, and the README recommends 16 GB or more of VRAM for the default server model. That is a real hardware floor, not a suggestion, and it rules out most laptops for the server role.
The README points to the server guide for configuration, deployment, security, and API details. It does not document rollback, backup, or migration between server versions in the main README, so treat those as things to check in the server guide before you put this in front of a team. The project also publishes a performance reference for Qwen3-ASR-1.7B with vLLM on an AWS EC2 g5.xlarge with an NVIDIA A10G 24 GB: roughly 0.8 s for 30 seconds of audio, 1.6 s for one minute, 2.1 s for two minutes, 2.5 s for three minutes, and 3.0 s for five minutes. Those are the project's own numbers on that instance, not a general guarantee.
Where SayIt is the wrong tool
The platform boundary is the first limitation. The repository describes Windows only, the badge says Windows, and the releases are Windows installers. If your team is on macOS or Linux, this is not the project for you, and the README does not present a path to either.
Local mode has a cost the marketing framing tends to hide. Seven GGUF models ship with the app, and the README says detected GPUs are used automatically, but GPU acceleration is conditional. On a machine without a usable GPU, you are running speech recognition on the CPU, and the README does not state what that does to latency. The project publishes latency figures for a server GPU, not for local CPU inference, so you should measure your own machine before assuming local mode is fast enough for long dictation.
Self-hosting has a higher bar than the three-mode table suggests. An NVIDIA GPU with 16 GB or more of VRAM is recommended for the default server model, and the deployment involves a config file, an environment file, and a Compose build. That is normal for a backend, but it is not a turnkey appliance.
Finally, the project is young. The releases listed are v0.1.8, v0.1.9, and v0.2.0, with v0.2.0 dated 2026-09-09. The last push to the repository was on 2026-09-09, so the codebase is moving, but the version numbers are still in 0.x territory. Treat the API surface and the settings layout as things that can change between releases, and read the changelog before upgrading.
Alternatives: Superwhisper and Wispr Flow versus a self-hosted stack
The project positions itself against Wispr Flow and Superwhisper, and the topics list both as alternatives it targets. The difference is not the shortcut-and-speak interaction, which all three share. It is where the audio and the text are processed and who controls the prompts.
With a hosted dictation product, the recognition and cleanup happen on the vendor's infrastructure, and the cleanup behaviour is whatever the vendor ships. SayIt's Cloud API mode also uses remote providers, but you choose them and supply the keys, and the README says no SayIt server is involved. Its local mode goes further: recognition stays on your PC, and with AI cleanup off, the documentation states nothing leaves the device. Neither of the hosted tools offers a local recognition path, because that is not their model.
If you already run Ollama or have an OpenAI-compatible endpoint, the cleanup stage can point at it, which means the writing style is something you can tune rather than something you wait for. The trade-off is maintenance: a hosted tool is someone else's operational problem, and SayIt's local and server modes are yours. If you want dictation with no configuration and no GPU, the hosted tools are the simpler answer. If you want the recognition path to be inspectable and the cleanup prompts to be editable, SayIt is the one that exposes them.
Licence and upgrade cost under AGPL-3.0
SayIt is licensed AGPL-3.0, and the README carries the standard badge. For individual use this changes nothing. For a company, the network clause matters: if you modify SayIt and let users interact with it over a network, the AGPL's source-availability obligation can reach your modified version. Running the unmodified backend for internal dictation is a different situation from shipping a modified SayIt as part of a product. This is a description of the licence family, not legal advice; if you are embedding it, have someone qualified read the licence text in the repository.
The upgrade cost is a function of how you deploy. Desktop users install from the releases page and the app carries its own settings, so an upgrade is a new installer. The friction is that 0.x releases can move settings around, and the README documents local history, diagnostics, and re-transcription but does not promise settings migration. Self-hosted deployments carry the real cost: a Compose rebuild, a config file and an environment file to keep in sync, and a server guide to consult for deployment and security details. The README does not document a rollback procedure in the main file, so decide your upgrade window before you pull a new image.
Editorial conclusion
Adopt SayIt if you dictate on Windows and want the recognition path to stay on your machine, or if you are willing to run the FastAPI backend yourself. Do not adopt it if you need macOS or Linux support, or if you plan to embed it in a closed-source product, because AGPL-3.0 reaches network use. Before committing, check that your GPU is detected in the voice engine settings, that the shortcut you want is free in the apps you dictate into, and that the per-app cleanup rules behave the way you expect in your editor.
Frequently asked questions
What is SayIt?
SayIt is open-source voice typing for Windows: you press a shortcut, speak, and the app transcribes, cleans up, and inserts the text at your cursor. It supports local GGUF models, cloud ASR providers with your own keys, or a self-hosted backend.
How do I install SayIt on Windows?
Download the latest Windows installer from the releases page, open SayIt, and choose a voice engine. The README says the default public server is enough for a quick trial, and regular use means switching to Local mode or adding your own provider keys in the in-app settings.
Does SayIt work without sending my audio to a server?
In Local mode, speech recognition stays on your PC, and with AI cleanup off the README states nothing leaves the device. Cloud API mode sends audio to the ASR and AI providers you configure, and Server mode sends it to a SayIt backend you control or to the public trial server.
What are the requirements for self-hosting the SayIt backend?
The README recommends Docker Compose, and GPU speech recognition requires an NVIDIA GPU with 16 GB or more of VRAM recommended for the default server model. The backend combines FastAPI, WebSocket streaming, Qwen3-ASR, and an optional OpenAI-compatible cleanup model.
What is a SayIt alternative?
The project positions itself as an alternative to Wispr Flow and Superwhisper. The practical difference is control over processing location and cleanup prompts: SayIt can run recognition locally or against providers you configure, while the hosted tools process audio on the vendor's infrastructure.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/crosswk-sayit)Star history chart for your README
[](https://hysenlabs.com/projects/crosswk-sayit)Was this useful?