GBrain: sourced, correctable agent memory on Postgres, with trust boundaries you have to read first
gbrain adds searchable long-term notes to OpenClaw, Hermes Agent, Claude Code, and Codex so earlier work can be retrieved in later sessions.
At a glance
- What is it?
- GBrain gives OpenClaw, Hermes Agent, Claude Code, Codex and other harnesses a shared long-term memory with sources, corrections and withdrawal. This review covers the keyless starting point, the three ways to attach a brain, the synthesis and graph layers, and where its privacy and sharing guarantees stop.
- Who is it for?
- GBrain suits people who already run an agent harness and want one memory, with sources and corrections, shared across Claude Code, Codex, Hermes or OpenClaw, and who are willing to run their own database. It is the wrong choice if you need a guarantee that memory text never reaches a model provider, or a company deployment where shared database credentials must still isolate users.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
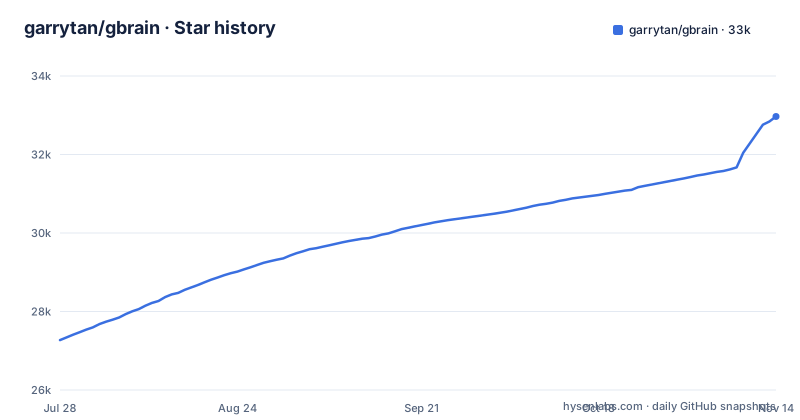
- garrytan/gbrain32,969 ★ · +5,698
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| garrytan/gbrain | 27.3k | 33k |
5,698 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Facts are stored with sources and can be corrected or withdrawn
GBrain gives the agent you already use a memory you control. Instead of opaque chat history, it stores explicit facts together with their sources, supports corrections and withdrawal, and makes the same memory available across several agents. The package describes itself as a Postgres native personal knowledge brain with hybrid RAG search, and the TypeScript source ships a `gbrain` CLI from `src/cli.ts` along with an embedded PGlite engine export.
You start keyless, with keyword retrieval only. Semantic search, synthesis and background enrichment are added later when you need them. Durable preferences and facts can be shared across agents, while transient task state and harness configuration stay local to each agent. That split means switching from Claude Code to Codex keeps what you taught the brain about people and projects, but not the scratch state of a half finished task.
Keyless does not mean nothing leaves the machine
Starting keyless avoids separate model API keys, but it is not a privacy boundary. The harness model sees recalled memory even in keyless mode, so whatever your agent provider is, it receives the facts GBrain pulls into context. Once you configure cloud embedding, reranking, extraction or synthesis providers, those providers can receive text as well.
Costs split the same way. Your harness subscription and any model API usage you configure separately are different bills. The optional personal agent bootstrap takes about 15 minutes, but always-on enrichment needs its own compute and API configuration.
Backups are the other trap. Markdown export is not a full database backup. If you treat the exported Markdown as your safety copy, a restore will lose whatever lives only in the database. Plan a proper Postgres backup from the start, and read the memory boundaries guide in docs/guides before pointing GBrain at anything sensitive.
Three ways to attach a brain, and one command to publish it
The recommended setup adds GBrain to an existing agent: your agent keeps its identity, memory is saved inside its environment, and no new personal agent identity or private repository is needed. Guides cover Grok Bot, Muse, and Codex or Claude Code, with others connected over MCP.
The second setup uses a brain on your own computer from anywhere. One command publishes it over MCP on your Tailscale tailnet and keeps it running:
gbrain mcp exposeAdding `--funnel` opens it to cloud agents such as Grok Bot, Muse and ChatGPT, which also widens who can reach the endpoint, so treat that flag as a deliberate exposure decision.
The third connects an existing hosted brain, through native OAuth or a private machine connection. Dashboard login, clients and permissions are handled with a separate owner credential, and delegation is an explicit choice. Hosted GBrain at gbrain.io is optional paid hosting; the code itself is MIT licensed and free to self-host.
Company brains confine remote callers, not database credential holders
GBrain can serve as a company brain, and this is where the fine print matters most. Authenticated remote clients are constrained by source and operation grants plus visibility filters. Local files and shared database credentials sit on a different trust boundary: sources alone do not isolate those callers. Anyone handed the database credentials is outside the grant system.
The project is explicit that its authorization tests exercise specific access paths, not a universal no-leak guarantee. The consequence for a team rollout is concrete. If several people or agents share one database login, per source restrictions will not keep one of them from reading another's memory. Give remote users MCP access with grants, keep database credentials with the owner, and read the sharing boundaries section of docs/architecture/brains-and-sources.md and the company brain tutorial before inviting anyone in.
A synthesis layer and a typed graph on top of retrieval
Beyond keyword and semantic retrieval, two optional layers change what a query returns. The synthesis layer writes cited prose across people, companies, deals and ideas, with an explicit note on what the brain does not know yet, instead of returning a list of matching chunks. Asked what you need before a meeting with Alice, the goal is an answer rather than five page links.
The typed knowledge graph works differently for local and remote writes. Trusted local page writes extract supported references without LLM calls when auto-linking is enabled. Remote `put_page` edges arrive later, through sweeps, maintenance or `add_link`, so a fact written remotely will not show up in graph queries straight away. Walks are breadth-first. On BrainBench relationship questions, relationship retrieval lifts production R@5 from 0.6626 to 0.7241; the 0.9791 figure is the `graph-oracle-parse` upper bound, not a product score.
Garry Tan's production numbers describe his deployment, not a default
GBrain was built by Garry Tan, President and CEO of Y Combinator, to run his own agents. It is the production brain behind his OpenClaw and Hermes deployments, which hold 155,795 pages, 24,589 people and 5,340 companies, with 66 cron jobs running autonomously. His agent ingests meetings, emails, tweets, voice calls and ideas overnight, enriches each person and company it meets, fixes its own citations and consolidates memory.
Those figures show what the system can hold, but they come from an always-on setup with its own compute, API configuration and ingestion sources. A fresh keyless install does none of that: it starts with keyword retrieval over what you put in. The 24/7 dream cycle that keeps the brain current is a daemon you have to provision and pay for, on your hardware, your database and your keys.
Skills ship inside the brain, and releases land several times a day
New local brains include memory skills in their content root. Agents can join an authorized catalog, and only approved editors can publish to it. Managed coding agent installs add an owned native router, but restart and real-use verification are separate steps, so an install that reports success has not yet proven the router works in your harness. Staged migration preserves sharing choices and personal edits.
The repository is built for agents to read: `llms.txt` maps the documentation, `llms-full.txt` inlines the core docs, and agents are pointed to AGENTS.md, CLAUDE.md for Claude Code, and INSTALL_FOR_AGENTS.md. The project uses Bun, per bun.lock and bunfig.toml.
The pace is fast. Versions v0.60.559.0, v0.60.560.0 and v0.60.561.0 were all published on 2026-11-03, and the last push was on 2026-11-02. Pin a version for anything shared, and read CHANGELOG.md before upgrading a brain other people depend on.
Editorial conclusion
GBrain suits people who already run an agent harness and want one memory, with sources and corrections, shared across Claude Code, Codex, Hermes or OpenClaw, and who are willing to run their own database. It is the wrong choice if you need a guarantee that memory text never reaches a model provider, or a company deployment where shared database credentials must still isolate users. Before adopting it, read the memory boundaries and sharing boundaries guides, decide which embedding and synthesis providers may receive your text, and keep a real database backup rather than relying on Markdown export.
Frequently asked questions
What is Garry Tan's GBrain?
GBrain is an MIT licensed memory layer Garry Tan built to run his own AI agents. It stores explicit facts with sources, supports corrections and withdrawal, and shares the same memory across agents.
What is GBrain for Hermes?
GBrain adds searchable long-term notes to Hermes Agent so earlier work can be retrieved in later sessions. It is the production brain behind Garry Tan's own OpenClaw and Hermes deployments.
Is GBrain free?
Yes, GBrain is MIT licensed and free to self-host. gbrain.io is optional paid hosting, and any model API usage you configure is billed separately by those providers.
How do you set up GBrain?
The recommended route adds GBrain to an agent you already use, with guides for Grok Bot, Muse, and Codex or Claude Code. You can also run gbrain mcp expose to publish a local brain over MCP on your Tailscale tailnet, or connect a hosted brain from gbrain.io.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/garrytan-gbrain)Star history chart for your README
[](https://hysenlabs.com/projects/garrytan-gbrain)Was this useful?