LevelDB: A Stable Ordered Key-Value Store, Frozen in Time
LevelDB is a fast key-value storage library written at Google that provides an ordered mapping from string keys to string values.
At a glance
- What is it?
- Google's LevelDB is a battle-tested embedded key-value library with an ordered map model. But with maintenance reduced to critical fixes, adopters must weigh its maturity against its stagnation.
- Who is it for?
- Adopt LevelDB if you need a proven, embedded, ordered key-value store in C++ and can accept a frozen API and minimal upstream activity. Avoid it if you require active development, new features, or extensive platform support beyond POSIX and Windows.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
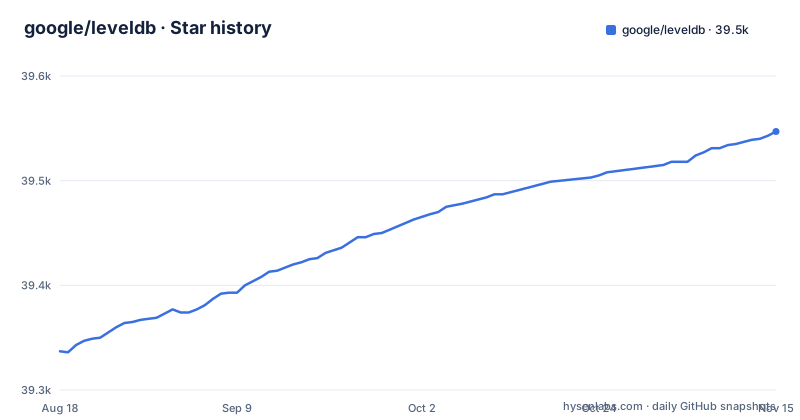
- google/leveldb39,547 ★ · +210
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| google/leveldb | 39.3k | 39.5k |
210 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What LevelDB Solves and Who It Serves
LevelDB solves a specific problem: providing a fast, ordered mapping from string keys to string values within a single process. It is not a server, not a SQL database, and not a distributed system. It is a library that you link into your application, and it is aimed at developers who need persistent storage with a simple key-value API and deterministic iteration order. The README is explicit about the target user: someone who wants arbitrary byte arrays as keys and values, sorted order, and the ability to customize the sort order with a comparison function. This makes it suitable for embedded databases, local caches, or as a building block for higher-level storage engines. It is not for anyone needing concurrent multi-process access or relational queries; the limitations section states plainly that only a single process can access a database at a time and that there is no built-in client-server support.
The Core Mechanism: Ordered Storage with Log-Structured Merge
LevelDB is built as a log-structured merge tree (LSM tree). Writes are appended to a log and then merged into sorted files, which explains the high write throughput in the fill benchmarks and the need for occasional compaction. The README confirms that data is stored sorted by key and that iteration is supported in both directions. It also mentions atomic batches and transient snapshots, which are typical of LSM designs that maintain a consistent view across multiple memtables and SSTable files. The key insight is that LevelDB trades read amplification for write efficiency: random writes are fast because they are buffered, but reads may need to check multiple levels. The benchmark numbers, which show fillseq at 62.7 MB/s and fillrandom at 45.0 MB/s on a 2011-era machine, reflect this design. The actual compaction mechanics are not described in the README, so a developer should consult the bundled documentation in doc/index.md for the full picture.
Getting It Running: Build Commands and Configuration
Building LevelDB is straightforward with CMake. The README gives the exact commands for POSIX systems: clone the repository with submodules, then create a build directory and run cmake with a release build type. The commands are: git clone --recurse-submodules https://github.com/google/leveldb.git, then mkdir -p build && cd build, then cmake -DCMAKE_BUILD_TYPE=Release .. && cmake --build. For Windows, the instructions are different: generate a Visual Studio 2017 project with cmake -G "Visual Studio 15" .., and for 64-bit use cmake -G "Visual Studio 15 Win64" .., then build with devenv /build Debug leveldb.sln or open the solution in Visual Studio. There is no package manager install command in the README; you must build from source. The build system is CMake, and the project uses submodules for dependencies (see .gitmodules and third_party/), so the --recurse-submodules flag is essential. The README also notes that the project is unlikely to accept changes to CMakeLists.txt, so if you need a different build system, you are on your own.
Performance Expectations from the Included Benchmark
The README includes a performance report from the db_bench program, which is part of the source. The setup uses a database with one million entries, each with a 16-byte key and a 100-byte value that compresses to about half its size. The benchmark ran in May 2011 on a 4-core Intel Core2 Quad Q6600, so the numbers are dated but still indicative of the design's characteristics. Sequential writes (fillseq) achieve 62.7 MB/s, while random writes (fillrandom) hit 45.0 MB/s, which is roughly 400,000 writes per second. The fillsync benchmark, which flushes to disk after every operation, drops to 0.4 MB/s, showing the cost of durability. The overwrite benchmark, which updates existing keys, runs at 46.5 MB/s. These numbers are noisy, as the README admits, and they are not a substitute for benchmarking on your own hardware. The key takeaway is that LevelDB is write-optimized, but synchronous writes are expensive, and compression is enabled by default (Snappy) and can be changed to Zstd.
The Elephant in the Room: Limited Maintenance and Its Consequences
The most striking part of the README is the maintenance warning at the top: this repository is receiving very limited maintenance, and only critical bug fixes or changes needed by internal Google clients will be reviewed. This is not a subtle hint; it is a clear boundary. The last release is 1.23 from February 2021, and the last push to the repository was on 2026-10-08, so the project has gone years without a release. For an engineer evaluating adoption, this has direct consequences: do not expect new features, performance improvements, or support for new compilers or operating systems. The contribution guidelines reinforce this by stating that changes to build configuration are unlikely to be accepted. This means if a modern C++ standard or a new OS version breaks the build, you may need to patch it yourself or wait indefinitely. The project is not abandoned, but it is in maintenance mode, and the README's language is blunt about the review criteria. This is a trade-off: you get a stable API, but you also get a project that has stopped evolving.
Limitations That Are Deal-Breakers for Some Use Cases
The README lists three explicit limitations, and they are worth reading carefully. First, LevelDB is not a SQL database: no relational model, no SQL queries, no indexes. If you need to query by anything other than the key, this is the wrong tool. Second, only a single process can access a database at a time, though that process can be multi-threaded. This rules out any multi-process architecture, such as a web server with forked workers sharing a database. Third, there is no client-server support built in; if you need network access, you must wrap your own server around the library. These are not hidden gotchas; they are stated plainly in the documentation. Another limitation that is not listed but is implied by the maintenance policy is the lack of forward-looking platform support. The contribution requirements mention that only POSIX and Windows are tested, and other platforms are unlikely to be accepted. So if you are on BSD, embedded Linux with a custom libc, or a new architecture, you may face an uphill battle.
Alternatives: Comparing Approaches to Embedded Storage
The most direct alternative to LevelDB is RocksDB, which is a fork of LevelDB with a different design philosophy. RocksDB is also an embedded key-value store with an LSM tree, but it is optimized for server workloads, with features like bloom filters, column families, and configurable compaction strategies. The key difference is that RocksDB is actively maintained and has a much larger feature set, at the cost of increased complexity. Where LevelDB is minimal and stable, RocksDB is extensive and evolving. Another alternative is SQLite, which provides a relational model and SQL, but it is not ordered by key in the same way. The choice depends on your needs: if you want a simple, ordered map with minimal dependencies, LevelDB works. If you need advanced tuning or active development, RocksDB is the more appropriate choice. LevelDB prioritizes simplicity and stability, while RocksDB prioritizes flexibility and performance.
Licensing and Upgrade Costs: What the Material Tells Us
LevelDB is licensed under BSD-3-Clause, which is permissive and allows commercial use with attribution. The BSD license means you can incorporate the code into proprietary projects, as long as you preserve the copyright notice. The maintenance cost is the bigger concern. Upgrading from an older version to 1.23 is likely straightforward because the API is stable, as the contribution guidelines state they strive to maintain a stable API. However, the upgrade cost is not just about the library itself; it is about the ecosystem. The project uses submodules for dependencies, so you must manage those. The lack of new releases means you will not receive security fixes unless they are critical and accepted, which is a risk. The repository includes a NEWS file alongside the GitHub releases. The practical cost is that you are on your own for any issue that is not a critical bug, and you must decide whether that is acceptable for your application.
Editorial conclusion
Adopt LevelDB if you need a proven, embedded, ordered key-value store in C++ and can accept a frozen API and minimal upstream activity. Avoid it if you require active development, new features, or extensive platform support beyond POSIX and Windows. Before committing, verify that your target platforms and compilers are covered by the existing build configuration, and review the current issue tracker for any unfixed critical bugs. The project's own maintenance policy makes clear that anything beyond critical fixes is unlikely to land, so your team must be prepared to fork or vendor the code for any custom needs.
Frequently asked questions
What is LevelDB used for?
It is an ordered mapping from string keys to string values, where keys and values are arbitrary byte arrays kept sorted by key. You call Put, Get and Delete from inside your own process, and there is no client-server layer built in.
How to install leveldb?
The README documents a source build only. You clone the repository with the submodule flag included, then configure and compile with CMake inside a separate build directory. No package manager install step is given.
Is leveldb dead?
The README states that the repository is receiving very limited maintenance and will only review critical bug fixes and changes needed by internally supported clients. The last push to the default branch was on 2026-10-08, and the newest release is 1.23 from 2021-02-23.
LevelDB vs sqlite?
The project says plainly that LevelDB is not a SQL database, with no relational data model, no SQL queries and no support for indexes. Access is a sorted key range with a caller-supplied comparison function, not a query language.
What are the key differences between RocksDB and LevelDB?
On the LevelDB side, the README states these boundaries: a single process per database, no client-server support built in, and no indexes, so an application that needs those will have to wrap its own server around the library.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/google-leveldb)Star history chart for your README
[](https://hysenlabs.com/projects/google-leveldb)Was this useful?