AI Website Cloner Template: how /clone-website turns a URL into a Next.js 16 codebase
AI Website Cloner Template guides coding agents through recreating a reference site as a structured Next.js project.
At a glance
- What is it?
- JCodesMore/ai-website-cloner-template is a Next.js starter plus one agent skill, /clone-website, that has Claude Code, Codex, Cursor or OpenCode inspect a live site and rebuild it as editable components. It fits migrations of sites you own and recovering lost source, and it leaves you holding someone else's assets if you point it anywhere else.
- Who is it for?
- Use this template when you own a site on WordPress, Webflow or Squarespace and want it back as a Next.js 16 codebase you can edit, or when the source of a live site is gone. It is the wrong tool if you need output in another framework, or if the site belongs to someone else, since the logos, brand assets and copy it extracts stay theirs.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
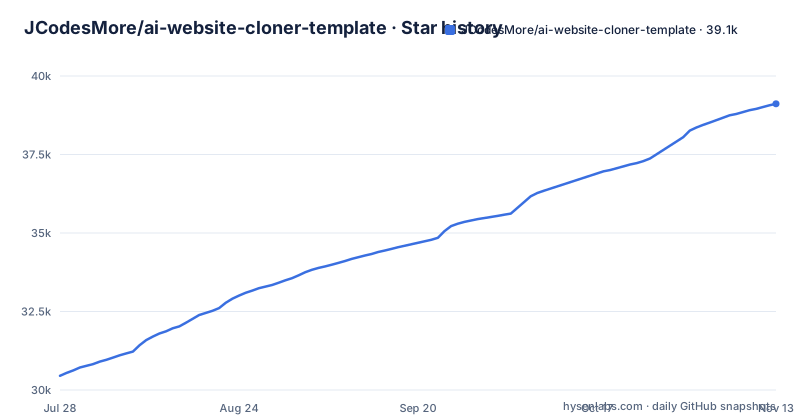
- JCodesMore/ai-website-cloner-template39,114 ★ · +8,662
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| JCodesMore/ai-website-cloner-template | 30.5k | 39.1k |
8,662 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
/clone-website runs a four-step Map, Observe, Build, Compare loop
The project is two things in one repository: a Next.js starter and a skill called /clone-website that tells a coding agent how to reproduce a reference site inside that starter. The skill runs in four steps.
Map ties source URLs to local routes and preserves work already in the project, so a second run does not wipe the first. Observe inspects desktop and mobile pages, extracts real assets and fonts, and exercises alternate states. Build implements editable components and working interactions, and can hand independent sections to sub-agents. Compare reviews the source and local pages at matched sizes and states, repairs visible differences and runs the production check.
The split of labour is deliberate. Direct HTTP or asset tools handle extraction where practical, while browser comparisons decide appearance and behaviour. What comes back is route mappings, run instructions, comparison screenshots and a list of remaining gaps. That last item is the honest part of the design: the skill reports what it could not match instead of claiming a perfect copy.
One portable skill in .agents/skills, bridged into Claude Code by a command file
The skill lives once, at .agents/skills/clone-website/. Codex, Cursor and OpenCode read it from there directly. Claude Code instead goes through a small command bridge at .claude/commands/clone-website.md, which keeps /clone-website and its arguments working without exposing a second copy of the skill to the other agents. Editing the canonical skill therefore changes behaviour for all four agents at once.
Support is not equal across them. Claude Code with Opus 5.5 is marked as recommended and the project says it gives the best results. Codex CLI, OpenCode and Cursor are listed as supported. Since the agent does the inspection, extraction and component writing, clone quality tracks the agent and model you run it with more than anything in the template itself. A team standardised on a different agent should expect to compare its output against a Claude Code run before trusting it.
Setting up: let the agent clone the template, then run npm run check
The prerequisites are Node.js 24 or later, which package.json enforces with an engines field of >=24, and a supported coding agent. The recommended setup hands the work to the agent itself with this prompt:
Set up https://github.com/JCodesMore/ai-website-cloner-template
as a standalone project in a new folder on my computer.
Ask me where to put it. Clone the repository, remove its origin remote,
install dependencies, and run npm run check. Leave it ready for me
to clone a website.
The alternative is GitHub's template button: create your own repository from it, then ask the agent to clone that, install dependencies and run npm run check. Either way, check is the gate that proves the starter builds before any cloning starts:
npm run check # Run lint + typecheck + buildIt chains ESLint, tsc --noEmit and next build. With that passing, open the project in your agent with browser access enabled and give it the target URL. In Claude Code or Cursor:
/clone-website https://example.comAfter the build finishes, further changes are ordinary requests to the agent.
Extracted assets land in public/sites/<site>, and ownership does not transfer
The project structure shows exactly where cloned material goes. Source-specific components and extracted SVGs sit under src/components/sites/<site>/. Images, fonts, videos and other assets go to public/sites/<site>/. A page brief, asset map and inspection evidence are written to docs/research/<site>/, and screenshots to docs/design-references/.
That layout makes the legal boundary concrete. A finished clone contains the source site's real fonts, images and copy, not placeholders. The project's own list of what it is not intended for spells out the consequences: no phishing or impersonation, no passing off someone else's design, since logos, brand assets and original copy belong to their owners, and no violating terms of service on sites that prohibit scraping or reproduction.
The stated use cases are narrower than the tagline suggests: migrating a site you own off WordPress, Webflow or Squarespace, recovering a live site whose repository is gone, and studying how production sites achieve a layout or animation. For learning, the code stays on your machine. For anything you publish, every file under public/sites/<site>/ needs to be yours or replaced.
Without browser access the skill cannot observe, and motion-heavy sites leave gaps
The setup instructions require opening the project in an agent with browser access enabled. That is not a nicety. Observe and Compare both depend on rendering the source and local pages at matched sizes, so an agent limited to HTTP fetches can pull assets but cannot judge appearance or exercise interactive states. A run without a browser loses the step that catches visual differences.
Framer pages and animated sites get focused inspection guidance covering responsive variants, media, sticky scenes and scroll or time-driven motion. Having guidance for those cases signals that they are the hard ones, and the deliverables list of remaining gaps is where shortfalls appear. A marketing site built around scroll-linked animation is the case most worth checking by hand against the comparison screenshots.
The output is also fixed to one stack. Every clone becomes a Next.js App Router project. If the migration target is Astro, plain HTML or another framework, the template offers no path there, and porting the generated components is extra work on top of the clone.
Next.js 16 with shadcn/ui on Base UI and Tailwind v4 oklch tokens
The starter pins next and eslint-config-next to 16.3.5 and React to 19.2.4, uses the App Router and runs TypeScript in strict mode. Components come from shadcn/ui built on Base UI primitives through @base-ui/react, styled with Tailwind CSS v4 using oklch design tokens. Lucide React supplies default icons, and during cloning those are replaced by SVGs extracted from the source.
Shared helpers follow shadcn conventions: a cn() utility in src/lib/utils.ts combining clsx and tailwind-merge, primitives in src/components/ui/, and hooks and TypeScript interfaces in their own folders. For a developer who already works in this stack, the target layout is familiar, and the skill aims for editable components rather than copied markup, which is the whole point of rebuilding instead of mirroring.
The pinned versions cut both ways. A clone made today is on Next.js 16.3.5, and moving it to a later Next.js release is your job, not the template's.
Docker targets: a standalone production image on 3000 and a dev container on 3001
The repository ships a Dockerfile, a Dockerfile.dev and a docker-compose.yml with two services:
docker compose up app --build # build and run the app
docker compose up dev --build # run the app in dev mode on port 3001
The app service builds the runner stage, maps ${PORT:-3000} on the host to port 3000, restarts unless stopped and health-checks itself with wget against localhost:3000. The dev service uses Dockerfile.dev, maps ${DEV_PORT:-3001}, and mounts the working directory into /app while keeping node_modules and .next inside the container. Both set NEXT_TELEMETRY_DISABLED=1 and read .env.local and .env when present, with neither file required.
The production Dockerfile is adapted from the Next.js with-docker example. It defaults to node 24.14.1-slim to match the Node 24 baseline and installs from whichever lockfile it finds, using npm ci for package-lock.json. It stops with No lockfile found. if there is none, so deleting package-lock.json breaks the image build.
Removing the origin remote cuts you off from template updates
The recommended setup prompt tells the agent to remove the origin remote. That makes each clone a standalone project, and it also means fixes to the skill do not reach you automatically. Recent releases show why that matters: v0.5.1 on 2026-09-27 was a security patch that also moved to Opus 5.5, v0.6.0 on 2026-10-05 improved the cloning workflow, and v0.6.1 the same day added rule-based fidelity guidance. The last push was on 2026-10-19 and package.json reads 0.6.1, a pre-1.0 version. Pulling those changes into an existing clone means copying .agents/skills/clone-website/ across by hand.
The closest alternative is a site mirroring tool such as wget or HTTrack, which saves the served HTML, CSS and assets as static files. That is faster and needs no AI agent, but the result is the original markup, not editable React components. The template trades speed for a codebase you can keep developing. The project is MIT licensed.
Editorial conclusion
Use this template when you own a site on WordPress, Webflow or Squarespace and want it back as a Next.js 16 codebase you can edit, or when the source of a live site is gone. It is the wrong tool if you need output in another framework, or if the site belongs to someone else, since the logos, brand assets and copy it extracts stay theirs. Before cloning anything substantial, confirm your agent runs with browser access enabled and plan to read the remaining gaps list in the deliverables rather than assuming the clone is complete.
Frequently asked questions
Is there an AI that can clone a website, like AI Website Cloner Template?
AI Website Cloner Template gives Claude Code, Codex, Cursor or OpenCode a /clone-website skill that inspects a URL and rebuilds the site as a Next.js 16 app. Claude Code with Opus 5.5 is the recommended pairing.
Is cloning a website with AI Website Cloner Template illegal?
The project states it must not be used for phishing, impersonation or passing off someone else's design, and that some sites prohibit scraping or reproduction in their terms of service. Its intended uses are sites you own, recovering lost source code and learning.
How do I clone an entire website with AI Website Cloner Template?
Set up the template, run npm run check, open the project in your agent with browser access enabled, and run /clone-website followed by the URL. The skill maps routes, inspects pages, builds components and compares the result against the source.
What is the Claude skill for cloning a website in AI Website Cloner Template?
It is /clone-website. The canonical skill sits in .agents/skills/clone-website/, and Claude Code reaches it through the command bridge at .claude/commands/clone-website.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jcodesmore-ai-website-cloner-template)Star history chart for your README
[](https://hysenlabs.com/projects/jcodesmore-ai-website-cloner-template)Was this useful?