nanoGPT: A Minimal GPT Trainer That Prioritizes Readability Over Features
GitHub describes it as The simplest, fastest repository for training/finetuning medium-sized GPTs.. The repository metadata lists Python as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Andrej Karpathy's nanoGPT is a stripped-down, ~300-line training loop and model definition for training and finetuning medium-sized GPTs. It is now deprecated in favor of nanochat, but remains a useful reference for understanding GPT training mechanics.
- Who is it for?
- Adopt nanoGPT if you want to study a readable, minimal GPT training loop and are comfortable with the deprecation notice: the README states it is 'very old and deprecated' in favor of nanochat. Do not adopt it for new production work.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 12 months ago, on November 12, 2025.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
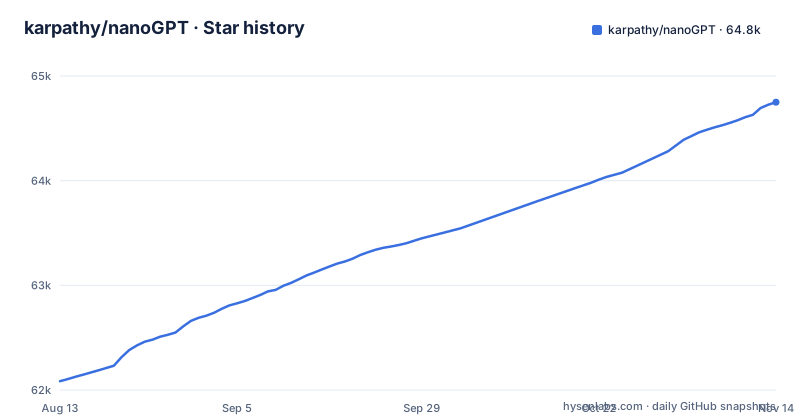
- karpathy/nanoGPT64,750 ★ · +2,666
| Repository | 2026-08-13 | 2026-11-14 |
|---|---|---|
| karpathy/nanoGPT | 62.1k | 64.8k |
2,666 Stars in the last 93 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What nanoGPT Actually Solves
nanoGPT solves a specific problem: it gives you a GPT implementation that is short enough to read in one sitting. The README states that train.py is a ~300-line boilerplate training loop and model.py is a ~300-line GPT model definition. That brevity is the point. It is not a framework with abstractions, config systems, or distributed training utilities beyond what PyTorch provides. It is for people who want to see exactly how a GPT is trained, or who want a starting point they can hack on without wading through thousands of lines of code. The intended users are deep learning practitioners, students, and researchers who already understand Transformers and want a minimal, working example. The README explicitly separates two audiences: 'not a deep learning professional' who wants a quick character-level demo, and 'a more serious deep learning professional' who wants to reproduce GPT-2. The latter is the real use case: the code reproduces GPT-2 (124M) on OpenWebText in about 4 days on a single 8xA100 node, according to the README.
The Architecture: Two Files, One Training Loop
The core mechanism is visible in the repository layout. There is model.py, which defines the GPT architecture, and train.py, which contains the training loop. The model can optionally load GPT-2 weights from OpenAI, which is a key feature for finetuning. The data flow is straightforward: raw text is tokenized into a single stream of integers stored as a binary file (train.bin and val.bin). For OpenWebText, the data preparation script downloads and tokenizes the dataset using GPT-2's BPE tokenizer via tiktoken, then stores the token IDs as raw uint16 bytes. Training then reads these binary files directly, which is efficient because there is no on-the-fly tokenization. The training loop uses PyTorch's Distributed Data Parallel (DDP) for multi-GPU training, as shown in the torchrun command. It also uses PyTorch 2.0's compile feature for speed, which you must disable on CPU. The README says the code is 'plain and readable' and that is the core design choice.
Getting It Running: From Shakespeare to GPT-2
Installation is a single pip command: pip install torch numpy transformers datasets tiktoken wandb tqdm. The quick start path is the Shakespeare character-level demo. Run python data/shakespeare_char/prepare.py to download the 1MB text file and create train.bin and val.bin. Then train with python train.py config/train_shakespeare_char.py. That config file sets a context size of 256 characters, 384 feature channels, 6 layers, and 6 heads. On an A100 GPU, the README claims about 3 minutes of training and a best validation loss of 1.4697. Sampling is done with python sample.py --out_dir=out-shakespeare-char. For CPU-only machines, you must pass a long list of overrides: --device=cpu --compile=False --eval_iters=20 --log_interval=1 --block_size=64 --batch_size=12 --n_layer=4 --n_head=4 --n_embd=128 --max_iters=2000 --lr_decay_iters=2000 --dropout=0.0. On Apple Silicon, add --device=mps to use the Metal Performance Shaders, which the README says can accelerate training 2-3x. For the full GPT-2 reproduction, you run python data/openwebtext/prepare.py to download and tokenize OpenWebText, then torchrun --standalone --nproc_per_node=8 train.py config/train_gpt2.py. That run takes about 4 days on 8x A100 40GB and reaches a loss of about 2.85, per the README.
The Deprecation Problem: nanochat Is the Successor
The most important limitation is not technical; it is the deprecation notice at the top of the README. The update from November 2025 says nanoGPT 'is now very old and deprecated' and that 'it is very likely you meant to use/find nanochat instead.' That is a direct warning from the author. The repo is left up for posterity, but there is no active development. This means you should not expect bug fixes or new features. If you adopt nanoGPT, you are adopting a frozen codebase. That is fine for learning or for a one-off experiment, but it is a real risk for any project that expects to run for more than a few months. The README also notes that the code is 'still under active development' in a later paragraph, but that is contradicted by the deprecation notice. The practical takeaway: treat nanoGPT as a reference implementation, not a maintained library.
Wrong Tool Cases: When nanoGPT Fails You
nanoGPT is the wrong tool if you need anything beyond a single GPT-2-scale model. The README only mentions GPT-2 sizes up to 1.3B as a finetuning starting point. The README's CPU example finishes in about 3 minutes but reaches a loss of only 1.88 and gives worse samples than the GPU run. The data preparation scripts the README walks through are for the Shakespeare and OpenWebText datasets.
Alternatives: minGPT and nanochat
The README explicitly names two alternatives. The first is minGPT, which nanoGPT is a rewrite of. The README says nanoGPT 'prioritizes teeth over education,' implying minGPT was more educational but less practical. minGPT is also by Karpathy. The second and more relevant alternative is nanochat, the successor. The README says 'it is very likely you meant to use/find nanochat instead.' The README calls nanochat a "new and improved cousin" and says nanoGPT is "now very old and deprecated". If you are starting a new project today, nanochat is the obvious choice. If you want to study the original GPT-2 training code, nanoGPT is still valuable.
Maintenance, Licensing, and Upgrade Costs
The repository is licensed under MIT, which means you can use, modify, and redistribute the code freely, including for commercial purposes. There is no copyleft obligation. However, because the project is deprecated, the maintenance burden falls entirely on you. The repository has no GitHub releases. The code depends on several external libraries: PyTorch, numpy, transformers, datasets, tiktoken, wandb, and tqdm. Each of these evolves independently. If you rely on nanoGPT, you may need to patch it when those dependencies break. The upgrade path is not to upgrade nanoGPT itself, but to migrate to nanochat. In short, the licence is permissive, but the practical cost of keeping nanoGPT alive is yours to bear.
Editorial conclusion
Adopt nanoGPT if you want to study a readable, minimal GPT training loop and are comfortable with the deprecation notice: the README states it is 'very old and deprecated' in favor of nanochat. Do not adopt it for new production work. Before using it, verify that your PyTorch version supports the compile flag (PyTorch 2.0+) and that your hardware matches the recommended specs for GPT-2 reproduction (8x A100 40GB). The code is MIT licensed, so you can fork it, but expect to maintain it yourself.
Frequently asked questions
what is nanogpt
nanoGPT is an MIT-licensed Python repository described as the simplest, fastest repository for training and finetuning medium-sized GPTs. It is a rewrite of minGPT that prioritizes teeth over education, with train.py and model.py each about 300 lines.
how to use nanogpt
Run the Shakespeare data prepare script, train with a config file, then sample from the output directory. The quick start trains a character-level GPT on the works of Shakespeare in about 3 minutes on one A100 GPU.
how to set up nanogpt
The install is one pip line for torch, numpy, transformers, datasets, tiktoken, wandb, and tqdm. Then run the relevant prepare script under data/ to build train.bin and val.bin before launching train.py.
Is NanoGPT free?
This repository is MIT-licensed training code, not a hosted product. Its top banner now marks it very old and deprecated and points to a newer project called nanochat.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- 17 GitHub Repositories to Learn AIdev.to · Nov 2, 2026 · 3 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/karpathy-nanogpt)Star history chart for your README
[](https://hysenlabs.com/projects/karpathy-nanogpt)Was this useful?