Kubero wraps Kubernetes in a two-container control plane
A free and self-hosted PaaS alternative to Heroku / Netlify / Coolify / Vercel / Dokku / Portainer running on Kubernetes
At a glance
- What is it?
- Kubero puts a web UI and a Kubernetes operator in front of a cluster so small teams can push containers and Git repositories without writing Helm charts. The convenience is real, and so is the gap between its stated storage model and what its own container ships.
- Who is it for?
- Adopt Kubero if one engineer owns a healthy Kubernetes cluster and wants a Heroku-style deploy button, review apps and pipelines without writing Helm charts, and the operator namespace is a normal part of your fleet. Do not adopt it if you need high availability add-ons, clear multi-tenancy boundaries or a promised support window, since the shipped add-ons are documented as not high availability ready.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 33 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
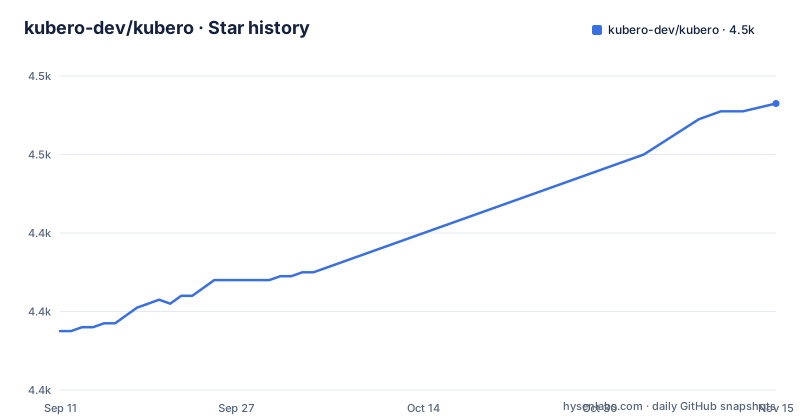
- kubero-dev/kubero4,473 ★ · +58
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| kubero-dev/kubero | 4.4k | 4.5k |
58 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two containers, no external database, one namespace
Kubero's pitch is narrow enough to state in a sentence: it runs two containers, kubero-ui and an operator, inside a namespace on any Kubernetes instance, and you deploy applications through that UI instead of writing manifests by hand. The README states that all data is stored on your cluster etcd without an extra database, which is what you would want to hear before planning a restore procedure.
That claim does not survive contact with the Dockerfile. Two environment variables are baked into the release stage:
ENV DATABASE_URL=file:/app/server/db/kubero.sqlite
ENV DATABASE_TYPE=sqlite
So the UI container opens a SQLite file at /app/server/db/kubero.sqlite, and docker-compose.yaml mounts a host directory onto exactly that path with ./server/db:/app/server/db. Both statements can be true at once if Kubernetes objects live in etcd while the UI keeps its own data in that SQLite file. The distinction matters for backups: a backup of etcd alone would not include a file mounted into the UI container.
Docker Deployments skip Helm, and that is the whole trade
The feature that distinguishes Kubero from a bare cluster is Docker Deployments: you point it at a container image or a source repository and it produces the Kubernetes objects for you. The README is explicit that this works without Helm charts, and that is the cost centre for the whole design. Templates and add-ons are the escape hatch when the defaults do not fit, and the addon table marks which of them ship inside the operator.
A deprecated chart still sitting in the selector is a real trap. The README marks every Bitnami entry as deprecated. The footnote under the table says the shipped add-ons are not high availability ready and exist to get you started quickly, which is an admission that the built-in path is a starting point rather than a production shape. PostgreSQL HA from CloudNative, and the operator-based options from Minio, Percona, Crunchy Data, Opstree and CockroachDB, sit in the column without the built-in mark.
Pipelines, GitOps review apps and redeploys share one source of truth
The deployment path has three entry points and they converge on the same object. CI/CD pipelines give you up to four staging environments per application. Automatic redeployments fire on pushes to branches or tags. GitOps review apps build, start and clean up an isolated app when a pull request opens and close again when it merges or closes.
That third one surprises teams, because cleanup is automatic rather than something you approve. Notifications for build and deployment events go out over Discord, Slack or webhooks, which is enough to catch a failed review build without watching the UI, and vulnerability scans run on a schedule or on demand against running applications. Metrics and logs are read in the UI, and a built-in web console drops you into a container shell.
Everything here depends on the operator holding valid credentials for the cluster. Kubero reads its kubeconfig either from a file on disk or from a base64 encoded variable, and the compose file shows both names.
Running it outside the cluster: docker-compose, port 8000 and a kubeconfig blob
The repository ships a compose file for the case where you would rather not put Kubero in the cluster it manages. It builds the UI from the local Dockerfile with VERSION=Local-Build as a build arg, sets KUBERO_NAMESPACE=kubero, and publishes container port 2000 on host port 8000. The two files it expects are named in comments rather than created for you: copy server/.env.template to server/.env, and copy config.yaml.template to config.yaml.
The kubeconfig is the part people get wrong. The compose file carries the extraction command in a comment, base64 so it survives YAML:
kubectl config view --raw --minify | base64Paste the result into KUBECONFIG_BASE64, or mount a kubeconfig file and point KUBECONFIG_PATH at it. KUBERO_CONTEXT is left commented out in the file, so check which context your kubeconfig selects before starting. There is a development variant of the same compose file for a local kind cluster and a kind.yaml at the repository root, so the loop for contributing is a kind cluster plus the compose stack rather than a hosted test environment.
Multi-tenancy and SSO are present in the UI, not enforced by the architecture
The feature list names multi-tenancy, SSO with GitHub and OAuth2, and Basic Auth for applications. The feature list gives one line for each; anyone choosing Kubero for a shared cluster should check the documentation at kubero.dev for how they work.
What the repository layout does show is a split between server and client, both built with yarn in the Dockerfile, plus a services directory and a client directory for the UI. The primary language is TypeScript, the image is built from node:22-alpine, and the entrypoint is CMD [ "node", "main" ] over a compiled server directory. There is no external stateful service to provision, no message broker, and no separate migration job in the compose file.
The image ships the template directory, the Prisma schema and no schema migration job
The final stage of the Dockerfile copies five things out of the build stage: the compiled server, its package.json, node_modules, the client build inlined into server/dist/public, and the deployments templates directory:
COPY --from=build /build/server/src/deployments/templates /app/server/deployments/templatesPrisma schema files are copied in from server/prisma. Nothing in the compose file runs a separate migration step or worker, and the database directory is mounted from the host, so the SQLite file outlives any one image.
That is the concrete upgrade cost, and it is small in exchange for having no database to operate. The same image also carries the client build, so the interface you get is the one built into that version, not a separately versioned frontend. The application template catalogue numbers more than 160 entries.
Where Coolify and Dokku differ from Kubero
The repository description places Kubero alongside Heroku, Netlify, Coolify, Vercel, Dokku and Portainer, and the alternatives fall into two groups. Coolify sits on Docker and manages the host it runs on, wiring containers, networks and volumes itself. Dokku is a single-tenant, per-application plugin stack over one host's Docker daemon, which makes it excellent for one app and a poor fit for a shared control plane.
Kubero sits on the far side of both. It assumes a Kubernetes cluster already exists and healthy, and it acts as a control plane inside it, so the things Docker-on-a-host gives you for free, such as port mapping and disk, are things you now express through the cluster's own primitives. The cost of that choice is that cluster operations skill stops being optional: when a deployment fails, the first question is whether the cluster will accept the object, not whether the container started.
Editorial conclusion
Adopt Kubero if one engineer owns a healthy Kubernetes cluster and wants a Heroku-style deploy button, review apps and pipelines without writing Helm charts, and the operator namespace is a normal part of your fleet. Do not adopt it if you need high availability add-ons, clear multi-tenancy boundaries or a promised support window, since the shipped add-ons are documented as not high availability ready. Verify the tag you plan to pin first, since the latest release is v3.1.1 from 2025-09-17, the last push to main is dated 2026-09-09 and the licence is GPL-3.0, and check that its Dockerfile still points DATABASE_URL at the SQLite file you already have.
Frequently asked questions
What are the alternatives to Kubero?
Kubero's own description names Heroku, Netlify, Coolify, Vercel, Dokku and Portainer as the platforms it stands in for. Coolify and Dokku manage Docker on a host, while Kubero requires an existing Kubernetes cluster and runs a UI and an operator inside it.
How do you install Kubero?
The repository ships docker-compose.yaml, which builds the UI image locally, sets KUBERO_NAMESPACE=kubero and maps host port 8000 to container port 2000. Before starting, copy server/.env.template to server/.env and config.yaml.template to config.yaml, and supply cluster access through KUBECONFIG_BASE64 or KUBECONFIG_PATH.
Does Kubero need a separate database?
The README says all data is stored on your Kubernetes etcd without an extra database. The Dockerfile nonetheless sets DATABASE_URL=file:/app/server/db/kubero.sqlite, so the UI container also keeps a local SQLite file that the compose file mounts from ./server/db.
Does Kubero need Helm charts to deploy an application?
No. Docker Deployments place a container on Kubernetes without needing Helm charts, which is the main difference from running a cluster by hand. Add-ons maintained by groundhog2k ship with the operator, while the Bitnami entries in the addon table are marked deprecated.
What does the Kubero container image contain?
The repository ships docker-compose.yaml for running the UI outside the cluster, and a Dockerfile that builds server and client with yarn on node:22-alpine. The entrypoint is CMD [ "node", "main" ] and the image writes its build version into /app/server/VERSION.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/kubero-dev-kubero)Star history chart for your README
[](https://hysenlabs.com/projects/kubero-dev-kubero)Was this useful?