Microsoft's Data Science for Beginners: A Free 10-Week Curriculum, Assessed
10 Weeks, 20 Lessons, Data Science for All!
At a glance
- What is it?
- Microsoft's Data Science for Beginners offers a structured 10-week, 20-lesson curriculum with quizzes and assignments. It is a solid starting point for newcomers, but its scope and maintenance model deserve scrutiny before you commit.
- Who is it for?
- Adopt this curriculum if you are a self-directed beginner who wants a free, structured introduction to data science with quizzes and hands-on assignments. Avoid it if you need deep mathematical rigor or advanced production techniques, as the lessons cover foundations only.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 25 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
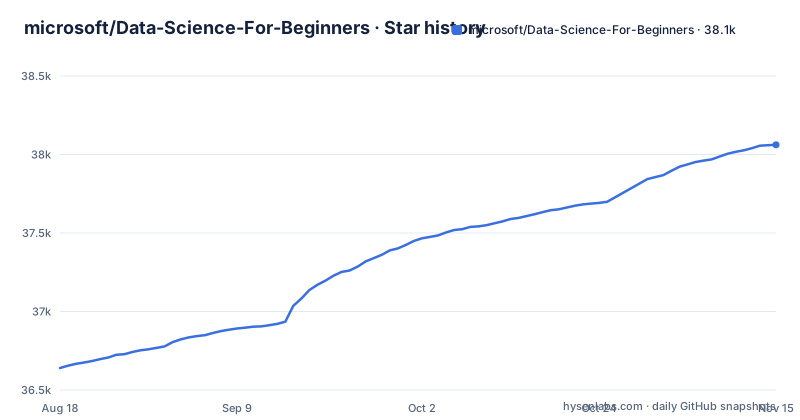
Star history
- microsoft/Data-Science-For-Beginners38,062 ★ · +1,422
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| microsoft/Data-Science-For-Beginners | 36.6k | 38.1k |
1,422 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Curriculum Actually Covers
The repository is primarily Jupyter Notebooks, which tells you the format: interactive, code-heavy, and exploratory. The repository is organised into six numbered directories, from 1-Introduction to 6-Data-Science-In-Wild. The quizzes are a notable feature because they force retrieval practice, which is more effective than passive reading. The assignments give you a chance to apply what you learned, and the solutions are provided, so you can check your work. This is a well-structured introduction, not a reference manual.
The Mechanism: Quizzes, Lessons, and Assignments in a Loop
The technical mechanism is straightforward: clone the repo, open the notebooks, and run them. The notebooks are Jupyter files, so you need a Jupyter environment. The README links to GitHub Codespaces, which lets you run notebooks in the cloud without local setup. That is a low-friction entry point. The repository also supports local use, and the sparse checkout command avoids pulling the 50+ translations if you only need English.
Getting It Running: Commands and Config Keys
The sparse checkout command is a concrete, useful detail. It is not a config key in the traditional sense, but it is a command-line option that shapes your setup. The README also mentions a Discord community and a 'Learn with AI Series' event, but those are optional community features, not required for running the curriculum. For a beginner, the fastest path is to click the Codespaces link in the README, which spins up a cloud environment with the repo ready. That removes the need to install Python or Jupyter locally. If you prefer local, you need Python and Jupyter installed, plus the libraries used in the notebooks. The repository also has INSTALLATION.md and TROUBLESHOOTING.md at its root.
The Multi-Language Translation Machine
The translation system is not just a list of folders. It is a GitHub Action that runs automatically, which means the translations are updated as the English content changes. That is a maintenance advantage, but it also means the translations may lag or contain artifacts. If you rely on a translation, you should cross-check key terms against the English version. The project's approach is broad but shallow in this regard. For a curriculum, accuracy matters, and machine translation is not always accurate. That is a real consideration if you are recommending this to non-native English speakers.
Where It Falls Short: Scope and Maintenance
Another limitation is the reliance on Jupyter Notebooks. Notebooks are great for exploration but poor for version control and reproducibility. If you are a professional looking to upskill, this is not for you. For a complete novice, the limitations are less critical because the goal is to get started, not to master production workflows.
Alternatives: How It Differs from Other Free Courses
The project-based approach is another differentiator. The README describes a project-based pedagogy where you learn while building, and every lesson includes an assignment. Data Science for Beginners is a middle ground between a tutorial and a full course. It is not as deep as a specialization, but it is more structured than a random collection of tutorials. That makes it a good first step, but you will need to follow up with more advanced resources.
Maintenance and Upgrade Cost
The lack of releases is a concrete concern. If you use this curriculum in a classroom, you should pin the commit you use to ensure consistency. The repository has CONTRIBUTING.md, CODE_OF_CONDUCT.md and SUPPORT.md at its root. You are relying on Microsoft's goodwill to maintain the project. The MIT license gives you the right to fork it, so you can take over maintenance if needed. That is a safety net, but it requires effort. Overall, the maintenance cost is moderate if you only consume the content, but it rises if you depend on it for a course.
Editorial conclusion
Adopt this curriculum if you are a self-directed beginner who wants a free, structured introduction to data science with quizzes and hands-on assignments. Avoid it if you need deep mathematical rigor or advanced production techniques, as the lessons cover foundations only. Before starting, verify that the Jupyter notebooks run in your chosen environment (Codespaces, local, or cloud) and check the current state of the GitHub issues for any known problems. The multi-language translations are a genuine asset, but they add bulk to the download, so use sparse checkout if you only need English. This curriculum is a good first step, not a complete career path.
Frequently asked questions
what is data science for beginners
It is a 10-week, 20-lesson data science curriculum offered by Microsoft's Azure Cloud Advocates and published under the MIT licence. Each lesson includes pre-lesson and post-lesson quizzes, written instructions to complete the lesson, a solution, and an assignment.
How do I start learning data science?
The repository is organised as six numbered directories, from 1-Introduction through 2-Working-With-Data, 3-Data-Visualization, 4-Data-Science-Lifecycle, 5-Data-Science-In-Cloud, and 6-Data-Science-In-Wild, so the order of study is built into the folder names. The stated method is project based, learning while building rather than watching.
Can I teach myself data science?
The material is self contained, with written instructions, a solution, and an assignment for every one of the 20 lessons. Teachers have a separate guide in for-teachers.md, alongside INSTALLATION.md, USAGE.md, TROUBLESHOOTING.md, and SUPPORT.md at the root of the repository.
projects in data science for beginners
Building projects is the stated method rather than an extra. An examples/ directory ships five standalone Python scripts, starting at 01_hello_world_data_science.py and continuing through loading data, a simple analysis, basic visualization, and a real world example.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-data-science-for-beginners)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-data-science-for-beginners)Was this useful?