Browser Arena: A Reproducible Benchmark for Cloud Browser Providers
The Browser Arena. Comparing how cloud browser providers perform.
At a glance
- What is it?
- Browser Arena is an open-source benchmark that measures cloud browser providers on the same EC2 instances, using the same test, and publishes a public leaderboard. It ranks providers on reliability, latency, and cost with a transparent scoring system.
- Who is it for?
- Adopt Browser Arena if you need a reproducible, provider-agnostic way to compare cloud browser services, whether you are choosing a vendor or tracking performance over time. Skip it if you require benchmarks for non-Chrome browsers, custom workflows, or if you cannot run your own EC2 instances.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 20, 2026, and from our analysis. They are not legal advice.
Star history
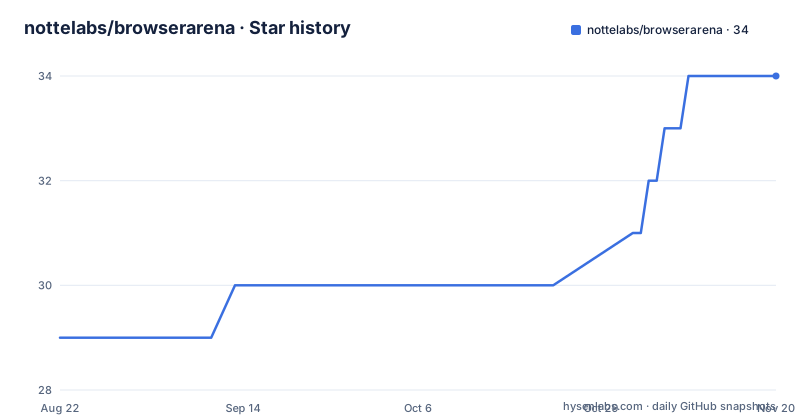
- nottelabs/browserarena34 ★ · +5
| Repository | 2026-08-22 | 2026-11-20 |
|---|---|---|
| nottelabs/browserarena | 29 | 34 |
5 Stars in the last 90 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Browser Arena Measures and Why It Matters
Cloud browser providers offer remote Chrome sessions, but comparing them is hard. Each provider has its own API, pricing, and performance profile. Browser Arena solves this by running a standardized test across every major provider: create a session, connect via CDP, navigate to a page, and release the session. The project records the time for each stage and derives reliability, latency, and cost metrics. The audience is engineers who need to pick a provider for production workloads, especially those where browser startup time directly affects user experience. The README notes that the project extends an earlier benchmark from Steel, adding more providers, a scoring system, and a public leaderboard. The live results are hosted at browserarena.ai, but the code is open so anyone can reproduce the numbers.
The Test Pipeline: From API Call to Session Release
The core benchmark is a four-step lifecycle. First, the provider's API creates a session. Second, Playwright connects to that session over the Chrome DevTools Protocol (CDP). Third, the page navigates to example.com, waiting for domcontentloaded. Fourth, the provider's API releases the session. The README emphasizes that create and release timings reflect provider API design, not browser speed. A provider that uses synchronous session management will show slower create times than one that returns immediately. The connect and goto stages are the better proxy for actual browser performance. This distinction matters because a naive comparison of total time would penalize providers for design choices that have nothing to do with rendering speed. The benchmark runs in two modes: sequential, where 100 sessions run one at a time, and concurrent, where 100 sessions run in batches of 10 parallel sessions.
How to Run the Benchmark Yourself
The README provides a straightforward setup. Clone the repository, install dependencies with npm install, copy .env.example to .env, and add your provider API keys. Then run npm run bench -- --provider=notte --runs=100. Node.js 18 or newer is required. The CLI supports a --help flag to list all options. Results are stored in a results/ directory, and you can query them locally with DuckDB using a provided SQL file: duckdb -c ".read queries/hello-browser/simple.sql". There is also a Railway deployment option, though the README does not detail the configuration. For daily automated runs, the project includes a script, scripts/run-and-publish.sh, which runs the benchmark for one region's providers and pushes the results to the main branch. Two EC2 boxes run this script on a cron schedule, one for us-east-1 providers and one for us-west-1 providers, staggered by an hour to avoid push races.
The Scoring System: Fixed Anchors and Weighted Dimensions
Each provider receives a Value Score from 0 to 1, combining reliability, latency, and cost with equal weights by default. The leaderboard allows shifting weights with presets like Speed first or Budget first. The normalization uses fixed anchors, not relative scaling. Reliability of 90% maps to 0.0, and 100% maps to 1.0. Latency of 10,000 ms maps to 0.0, and 0 ms maps to 1.0. Cost of $0.20 per hour maps to 0.0, and $0.00 maps to 1.0. The final score is a weighted sum of the three normalized dimensions. The README explains why fixed anchors beat two common alternatives. Ratio-to-best scaling gives each dimension a different effective scale, so cost can silently dominate even with equal weights. Min-max on observed data maps the worst provider in each dimension to 0.00, which unfairly zeroes out a provider that is 98.3% reliable if everyone else is 100%. Fixed anchors keep scales comparable and stable as providers are added or removed.
Fairness Measures and Their Limits
The methodology includes several fairness measures. Ten warm-up runs precede measurement to reduce cold-start effects. All providers navigate to the same URL, example.com. No provider-specific tuning is applied; default SDK settings are used. Rate limit errors trigger an automatic 30-second backoff. Most provider SDKs auto-retry transient errors, so success rates reflect post-retry outcomes. These measures are reasonable, but they have limits. The test environment uses t3.micro EC2 instances, which are small and may not represent the network conditions of a real production deployment. The README shows RTT measurements to each provider's CDP endpoint, ranging from 9 ms for Hyperbrowser to 62 ms for Browserbase, but those are from specific regions. The benchmark does not test browser features beyond a simple navigation, so it says nothing about rendering complex pages, handling WebGL, or streaming video. If your workload involves heavy pages, this benchmark is only a starting point.
A Real Alternative: Steel's Browserbench
The README credits Steel's browserbench as the foundation for this project. Steel's benchmark tested five providers, while Browser Arena extends it with more providers, a scoring system, and a public leaderboard. The key difference is the scope of the methodology. Steel's original project focused on raw measurements, while Browser Arena adds a normalization framework and a weighted score. If you want a simpler set of raw numbers without the scoring layer, Steel's browserbench might be sufficient. However, Browser Arena's fixed-anchor scoring addresses a real problem: comparing latency and cost on the same scale. If you prefer to compute your own weights, you can use the raw data from Browser Arena, but you would need to replicate the measurement pipeline. The choice between the two depends on whether you want a ready-made score or just the underlying data.
Maintenance and Upgrade Considerations
The project is under active development, with daily automated runs that push results to the main branch. The README does not mention a release schedule or versioning; the repository shows no recent releases. This suggests the project is in a continuous integration mode, where the benchmark and results evolve together. The cron setup requires two EC2 boxes, each with its own deploy key and .env file. Upgrading the benchmark code would involve pulling changes on each box and ensuring the cron script still works. The results are stored in a results/ directory, and the DuckDB queries suggest a schema that could change. The MIT license allows free use and modification, but there is no guarantee of backward compatibility. If you rely on this project for vendor selection, you should pin a specific commit and track changes to the methodology manually.
Editorial conclusion
Adopt Browser Arena if you need a reproducible, provider-agnostic way to compare cloud browser services, whether you are choosing a vendor or tracking performance over time. Skip it if you require benchmarks for non-Chrome browsers, custom workflows, or if you cannot run your own EC2 instances. Before relying on results, verify that the provider list and test environment match your use case, and check the methodology for any recent changes. The scoring weights are adjustable, so confirm that the default 33/33/33 split reflects your priorities.
Frequently asked questions
How does Browser Arena measure a cloud browser provider?
It runs four steps for every provider: create a session through the provider API, connect Playwright over CDP, navigate to a URL and wait for domcontentloaded, then release the session through the API. Results are medians across successful runs, in either sequential mode or batches of 10 parallel sessions.
Which providers does Browser Arena rank?
Nine of them: Notte, Tilion in beta, Browserbase, Steel, Kernel, Hyperbrowser, Anchor Browser, Browser Use and Lightpanda. Each is tested from one of two EC2 t3.micro boxes, with Notte, Browserbase and Lightpanda on the us-west-1 runner and the rest on us-east-1.
How does the Browser Arena value score turn latency into a number?
Reliability, latency and cost are each normalised to a 0 to 1 scale against fixed anchors and combined with equal 33/33/33 weights by default. Latency scores 0 at 10,000 ms and 1 at 0 ms, reliability scores 0 at 90 percent and 1 at 100 percent, and cost scores 0 at 0.20 dollars an hour and 1 at zero. Presets such as Speed first shift the weights.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nottelabs-browserarena)Star history chart for your README
[](https://hysenlabs.com/projects/nottelabs-browserarena)Was this useful?