elasticsearch-learning-to-rank pairs one plugin version with several Elasticsearch minors, and its stated support policy does not match its own tags
Plugin to integrate Learning to Rank (aka machine learning for better relevance) with Elasticsearch
At a glance
- What is it?
- What o19s/elasticsearch-learning-to-rank actually ships: per Elasticsearch version zip builds, a feature logging loop for offline model training, and a README that delegates almost every operational detail to documents outside the repository.
- Who is it for?
- The plugin is still the shortest path from a hand-tuned Elasticsearch query to a trained ranker, provided your cluster runs a version that already has a published build. Two facts decide whether that applies to you.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 152 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
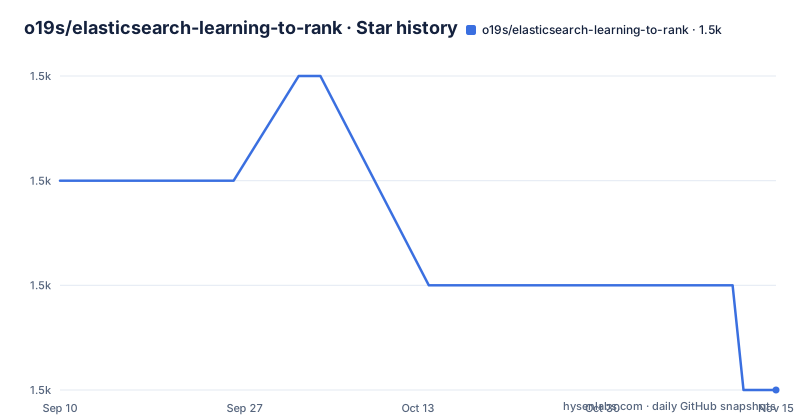
Star history
- o19s/elasticsearch-learning-to-rank1,519 ★ · -2
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| o19s/elasticsearch-learning-to-rank | 1.5k | 1.5k |
-2 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The support policy says *.*.1, the newest three tags are not
Release artifacts for this plugin are named for two versions at once, plugin and Elasticsearch. The three most recent are v1.5.13-es9.3.5 on 2026-06-16, v1.5.13-es9.3.2 on 2026-06-12 and v1.5.13-es9.2.4 on 2026-02-19.
Two things follow from that list. The plugin version has not moved at all across those three releases; only the Elasticsearch minor has, from 9.2.4 to 9.3.5. And none of the three is a `.1` release, which sits awkwardly against the stated policy in the Elastic Release Support section: officially supported versions are `*.*.1` releases, and anyone who needs a different version is asked to submit a pull request. In practice the published builds track whichever ES minors the maintainers could compile against, not a fixed cadence of point releases, so the policy line reads as an intention rather than a description of what is on the releases page.
The last push to the repository is dated 2026-06-16, the same day as the newest tag. Nothing in the visible text describes a release plan beyond that, so anyone planning around a future Elasticsearch minor is planning around a build that may not exist yet.
The install command in the README points at a zip for ES 7.11.2
Installing means handing `elasticsearch-plugin` a URL for a zip built against your exact Elasticsearch version, and the example in the README is old enough to be worth noticing:
./bin/elasticsearch-plugin install https://github.com/o19s/elasticsearch-learning-to-rank/releases/download/v1.5.4-es7.11.2/ltr-plugin-v1.5.4-es7.11.2.zipThat is the v1.5.4 build for Elasticsearch 7.11.2, several plugin versions and many Elasticsearch minors behind what is currently published. The zip name carries both versions, which is the pattern to follow when you pick your own. Two operational notes come with the command: the plugin installer is expected to raise security exceptions that you confirm, and passing `-b` to `elasticsearch-plugin` accepts them automatically, so a scripted install needs that flag. If a cluster is already running, it has to be restarted afterwards.
When no prebuilt version matches, the documented fallback is to build it yourself with the wrapper committed in the tree:
./gradlew clean check
./bin/elasticsearch-plugin install file:///path/to/elasticsearch-learning-to-rank/build/distributions/ltr-<LTR-VER>-es<ES-VER>.zip
The `file://` prefix matters, because the installer is given a local path rather than a remote one, and the distribution filename again encodes both versions. That path requires a JDK and a Gradle wrapper download, and the alternative offered in the same paragraph is filing an issue asking for a build.
The README is a pointer file and delegates the answers elsewhere
There is a heading in the README asking where the documentation is, and the answer is: not here. Operational detail is deferred to a readthedocs site, which the README describes as having quite a bit of information about learning to rank basics and how the plugin eases development. Known problems are deferred to KNOWN_ISSUES.md, contributions to CONTRIBUTING.md, and a hands-on example to a separate repository.
That structure explains why this file stays short, and it also sets a boundary for what a reader can learn from it. Nothing in the visible text shows a configuration file, a single query, or the request that uploads a trained model. Nothing shows where on disk the plugin keeps the features it logs. The only storage locations named anywhere are the three GitHub URLs, one for each of the two repositories and the docs site.
The known issues file is described with a qualifier worth keeping in mind: it lists what the maintainers are aware of, and it might include workarounds to mitigate them where such a workaround exists. That phrasing is an admission that some issues have no mitigation. Since the file itself is not reproduced in the README, you will have to open it before drawing conclusions about which Elasticsearch versions behave well.
The demo moved to another repository, and a demo directory is still in the tree
The I want to jump in section points at o19s/hello-ltr as the place the demo now lives, noting that it carries both Elasticsearch and Solr examples, and sends you to a notebook for the TMDB dataset to get started. At the same time, the top level of this repository still contains a `demo/` directory, and the files recorded from it are `demo/xgboost-demo/`.
So the working example and the code that supports it are split across two repositories, with an xgboost flavored directory remaining here. Nothing in the visible text says what that directory holds now, whether it is a leftover from when the demo lived here, or whether it still runs. If you are looking for a starting point, the README's own pointer is the other repository, and the practical consequence is that the Solr example is only available there, since this plugin is Elasticsearch specific and the tree contains no Solr side at all.
The same top level also holds a `sample_models/` directory, so at least some trained models are shipped with the code rather than produced by it. Combined with the fact that model training happens elsewhere, the repository's role is clear: it logs features, it stores models other people trained, and it serves them.
The plugin logs features for offline training and serves the result
Four capabilities are listed, and they form a loop with a deliberate break in the middle.
Features are stored inside Elasticsearch itself, as query templates. Feature scores are then logged so the log becomes a training set for offline model development. Models are stored back into Elasticsearch in linear, xgboost or ranklib format. Finally, a stored model ranks search results.
The break is the second step's wording. The training set is built for model development that happens outside the plugin, and no training command appears anywhere in the visible text. What the repository provides is the recording half and the serving half, which is a reasonable division of labor: the hard part of relevance work is usually assembling features and judging them offline, and the part that has to be fast is scoring a query with a fixed set of weights. Three model formats are named, so a team that already trains in one of them can export and load it, while a team that trains in something else has to convert first.
The two production claims in the file, that the plugin powers search at the Wikimedia Foundation and at Snagajob, are stated without a version, a scale or a configuration. They tell you the plugin survived contact with real traffic. They do not tell you which release those deployments run, and the version scheme above is precisely the thing that decides whether a build exists for your cluster.
The build badge points at Travis while the tree carries a .github directory
The first line of the README is a badge pointing at `travis-ci.com/o19s/elasticsearch-learning-to-rank`. The tree at the same time contains a `.github/` directory. Nothing in the visible text reconciles the two, so whether builds still run on Travis, on GitHub Actions, or on both is not settled by anything here.
What is settled is the build entry point. `./gradlew clean check` runs the wrapper committed in the tree, and `gradlew.bat` sits alongside it for Windows, so nobody needs a system Gradle. The rest of the build surface is visible in the directory listing: `build.gradle`, `settings.gradle`, `gradle.properties`, a `gradle/` directory for wrapper files, `scripts/`, `config/`, `docs/`, `publish/`, `sample_models/`, `demo/` and `src/`.
The presence of `publish/` alongside the license files points at a release assembly step that produces the zips you install. The presence of `config/` at the top level is the one entry with no explanation in the file: the README never says what that directory configures, whether it holds a sample configuration or something the plugin reads at install time. For a project whose whole job is consulting a trained model at query time, the configuration surface is exactly the part a new user needs, and it is the part the visible text leaves blank.
Apache release files sit next to a 2017 announcement link
The top level carries `LICENSE.txt`, `NOTICE.txt` and a `licenses/` directory, which is the standard shape for redistributing an Apache-2.0 component, and the declared license is Apache-2.0. `NOTICE.txt` is the file that has to travel with redistributions, so its presence matters more here than usual: the zip you install through `elasticsearch-plugin` is a redistribution of third party code into someone else's cluster.
The homepage recorded for the project is not the documentation. It is an Open Source Connections blog post from 2017-02-14, the announcement that describes where the plugin was initially developed. The file credits significant contributions from Wikimedia Foundation, Snagajob Engineering, Bonsai and Yelp Engineering, and thanks Jettro Coenradie specifically for porting to ES 6.1. That single credit is a useful index to how this project has been maintained: the path from 6.1 to the 9.x tags in the releases list ran through porting work contributed as patches rather than through a stated roadmap.
The file also points at a conference talk whose title is the honest summary of the project's difficulty, a Berlin Buzzwords session called We built an Elasticsearch Learning to Rank plugin. Then came the hard part, plus a blog post on why search is not like other machine learning problems, and a list of sibling projects: Elyzer, Splainer, Quepid, and the Relevant Search book. None of that material is in this repository, which is the point of the credit list. This is an old, externally documented project whose code is still being tagged against current Elasticsearch releases.
Editorial conclusion
The plugin is still the shortest path from a hand-tuned Elasticsearch query to a trained ranker, provided your cluster runs a version that already has a published build. Two facts decide whether that applies to you. First, the build you need may not exist: releases are cut per Elasticsearch minor, the README's own install example still points at a 7.11.2 zip, and an unsupported version means either building it yourself with the Gradle wrapper or opening an issue and waiting. Second, the visible documentation is not where the operational answers live. Configuration, query syntax, model upload calls and the failure modes all sit in the readthedocs site, in KNOWN_ISSUES.md, or in the separate demo repository, so read those before estimating the work. Teams that need a ranker this week and run a mainstream Elasticsearch release will find the plugin feature complete, with linear, xgboost and ranklib formats supported. Anyone on an odd internal build, or anyone expecting the plugin to train models rather than serve them, will find the gap elsewhere.
Frequently asked questions
How do I install the elasticsearch-learning-to-rank plugin?
Pick the prebuilt zip that matches your Elasticsearch version from the releases page and hand it to the plugin installer by URL. You will be asked to confirm security exceptions, which you can skip with `-b`, and a cluster that is already running has to be restarted afterwards.
What happens if elasticsearch-learning-to-rank has no build for my Elasticsearch version?
You build it yourself with `./gradlew clean check` and install the result from the build directory with a `file://` URL, or you file an issue asking for a release. The project also asks that anyone needing an unsupported version submit a pull request, and states that it officially supports `*.*.1` releases of Elasticsearch.
Which ranking model formats does elasticsearch-learning-to-rank store?
Linear, xgboost and ranklib. The plugin does not train them: it stores features as Elasticsearch query templates, logs their scores into a training set for offline model development, and then serves a model you load back into the cluster.
Does the elasticsearch-learning-to-rank repository include a working demo?
Not any more. The demo lives in a separate repository, o19s/hello-ltr, which carries Elasticsearch and Solr examples and a TMDB notebook to start from. A `demo/` directory with an xgboost demo still exists in this tree, and the top level also ships a `sample_models/` directory.
Which Elasticsearch versions is elasticsearch-learning-to-rank built against?
Builds are cut per Elasticsearch minor, and the three most recent releases pair plugin version 1.5.13 with ES 9.3.5, 9.3.2 and 9.2.4. The install example in the README still points at the v1.5.4 build for ES 7.11.2, so read the releases list rather than the example when you choose.
Who uses the elasticsearch-learning-to-rank plugin?
The README says it powers search at the Wikimedia Foundation and at Snagajob, and lists significant contributions from Wikimedia Foundation, Snagajob Engineering, Bonsai and Yelp Engineering, with the plugin initially developed at Open Source Connections. It does not attach a version or a scale to those deployments.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/o19s-elasticsearch-learning-to-rank)Star history chart for your README
[](https://hysenlabs.com/projects/o19s-elasticsearch-learning-to-rank)Was this useful?