Completed job rows are never deleted
💎 Robust job processing in Elixir, backed by modern PostgreSQL, SQLite3, and MySQL
At a glance
- What is it?
- Oban is a background job library for Elixir that keeps its queue in your existing SQL database rather than adding a broker. The design decision that defines it is that a finished job is retained, which turns the queue table into both a work list and a metrics store.
- Who is it for?
- Oban suits an Elixir application that already has a relational database and wants background jobs in the same transaction as the work that creates them, without adding a broker to operate. Four things to check before you commit.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Elixir, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
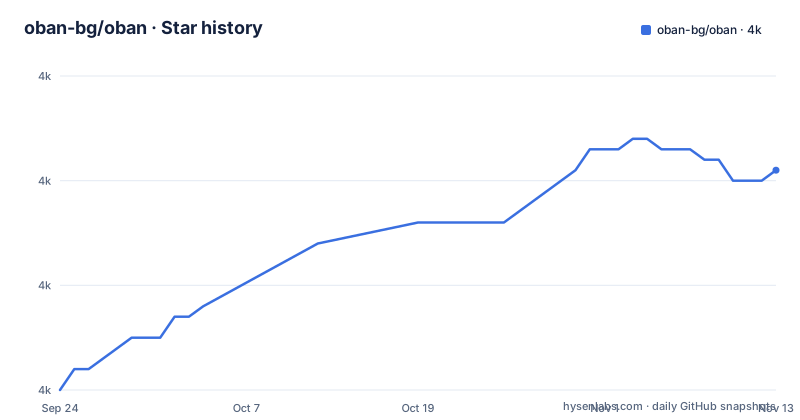
- oban-bg/oban4,001 ★ · +21
| Repository | 2026-09-24 | 2026-11-13 |
|---|---|---|
| oban-bg/oban | 4k | 4k |
21 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A completed job is not deleted, which is the whole design
Most queue systems delete a row when the work is done. This one keeps it, and the README states that as its distinguishing feature: it retains job data for historic metrics and inspection, so you can leave an application running indefinitely without worrying about jobs being lost or orphaned due to crashes. The mechanics follow from that choice. After a job is processed the row remains, so you can inspect historical jobs and see aggregate data at the job, queue or argument level. Separately, every queue records metrics to the database during runtime, and those records are what you monitor for queue health across nodes and may use for analytics. Two tables of concerns, then: one is your durable work list and audit trail, the other is a live health signal. The cost sits on the other side of the same ledger. Nothing in the README says rows expire automatically, so a table that only ever grows is a real operational concern, and retention policy becomes something your team has to own rather than something the library does for you.
The queue lives in the database you already have, which is the argument for it
Three advantages are listed and they are all consequences of one decision: running the queue inside a SQL database rather than alongside it. The first is fewer dependencies, on the reasoning that if you are running a web application there is a very good chance you are already on a SQL database, so putting the queue there minimises what else you have to operate. The second is transactional control. You can enqueue a job in the same transaction as the other database changes that justify it, so either the job and the work are both committed or neither is. That is the property that makes a job queue part of your domain model instead of a side effect, and it is the strongest argument for this shape. The third is that backups cover it, since jobs sit inside the primary database and are backed up together with the data they relate to. Nothing here is clever; it is a bet that the operational simplicity of one datastore outweighs the throughput characteristics of a purpose-built broker. Whether that bet is right depends on your write volume and on how much you value not operating a second system.
Three engines, explicitly of differing maturity
The engines section ships implementations for three databases and says something careful in the same breath: each supports the same core functionality, though they have differing levels of maturity and suitability for production. That sentence is doing real work and it is unusual to see it written. Most libraries with multiple backends imply parity and let you discover the gaps. Here the gaps are declared without being enumerated, so the practical consequence is that you cannot choose an engine from this page; you have to ask, or read the guides, or try it. The version requirements are precise, which helps: Elixir 1.15 or newer, Erlang 24 or newer, and then PostgreSQL 14 or newer, MySQL 8.4 or newer, or SQLite 3.37 or newer. Note that the MySQL floor is a recent 8.x release rather than an old supported one, and the SQLite floor is specific enough to suggest it was chosen for a particular feature. The test setup in the repository matches the claim of parity under test: a compose file starting three-database-capable services, with health checks, no engine excluded.
Six features are paid, and the one about concurrency is the one you will notice
There is a section describing a licensed extension package, and six named additions sit under it. One enables global concurrency limits, global rate limiting, queue partitioning and automatic insert batching, described as being for distributed job processing. Others add execution hooks, structured arguments, output recording, encrypted arguments at rest and chained execution to workers. Another composes jobs with arbitrary dependencies in sequential, fan-out and fan-in patterns. Another processes related jobs while tracking aggregate progress. Another allows runtime configuration of schedules, queues, priorities and automatic scaling. And another builds and inserts jobs from ordinary functions without defining worker modules at all. Read that list against the free list and the shape of the split is clear. Uniqueness, scheduling, periodic jobs, priority, cancellation, historic metrics, telemetry and graceful shutdown are all free. What is paid for is coordination across many nodes: limits that hold globally rather than per queue, and automatic scaling. So if you run one node, the free library is complete for most workloads. If you run many and need a global ceiling, that is the paywall.
Every job runs in its own process, which is both the concurrency model and the isolation model
Jobs are stored in a single table and executed in distinct queues, each with its own concurrency limits, so a slow queue cannot back up faster ones. Within a queue, every job runs in a dedicated process, which the README describes as providing fully concurrent execution, a clean environment between jobs, and efficient cleanup afterwards. Three properties in one sentence, and each has a cost as well as a benefit. Concurrent execution means a job that crashes does not take its neighbours with it, which is the isolation you want. A clean environment between jobs means you cannot rely on process state carrying over, so anything a job needs must be in its arguments, and that is where a large payload becomes a database write. Efficient cleanup means the runtime reclaims resources promptly, but it also means a job holding external state, a file, a lock, a subscription, has to release it itself. For a job queue in a language with lightweight processes this is the right default, and it is worth remembering that the isolation you get is process isolation, not transactional isolation of whatever the job touches.
Queue control works across nodes without distributed Erlang, and that is stated with a caveat
Queues can be started, stopped, paused, resumed and scaled independently at runtime, and the README makes a point of saying this works locally or across all running nodes, even in environments like a particular platform-as-a-service where distributed Erlang is not available. That parenthetical is doing real work. Changing a queue's state on one node and having every other node honour it requires either a consensus mechanism or a database-backed signal, and in a managed environment that does not let nodes find each other, the database is the only channel. The features that depend on this are the ones listed above it: insert triggers that dispatch jobs on all connected nodes as soon as they are inserted, and periodic jobs where duplicates are never enqueued no matter how many nodes you run. Both are cross-node coordination problems solved with the database. The cost is latency and a polling loop where a message queue would give you push, and the benefit is that the system has no new infrastructure and no new failure mode. Whether that trade is right is a deployment decision, not a library decision, but it explains why the paid tier's global limits are not trivially free.
The README describes the unreleased branch and says so at the top
The first thing after the table of contents is a note saying this file is for the unreleased main branch and that you should reference the published documentation for the latest stable release. That is good practice, and it has a specific consequence for anyone reading it. The feature list you are looking at, including the paid tier's contents and the engine descriptions, may not match what is on the package registry right now. The release history supports the caution: the newest tag is from August 2026, the one before it from May, and the last commit on the branch is dated 2026-09-29, so the branch is ahead of the last tag. Two commits in the tree tell you how the project is checked. There is a static analysis configuration file and a formatter configuration file, both of which are the standard Elixir tooling for style and lint enforcement. And there is a compose file whose only purpose is running the three supported databases for the test suite, with health checks rather than fixed sleeps, which is the difference between a test setup that is reliable and one that is fast.
Editorial conclusion
Oban suits an Elixir application that already has a relational database and wants background jobs in the same transaction as the work that creates them, without adding a broker to operate. Four things to check before you commit. Decide who owns retention, because completed job rows are kept by design and nothing in the README says they expire, so an ever-growing table becomes your problem. Ask which engine is production-ready, since the README states the three differ in maturity without saying how. Confirm the free feature set covers you, with global concurrency and rate limiting behind the paid tier, which matters only if you run several nodes. And remember that isolation between jobs is process isolation, not transactional isolation of whatever the job touches.
Frequently asked questions
What is Oban, the Elixir job processing library?
It is a background job processing library for Elixir whose stated goals are reliability, consistency and observability. It provides a simple API for scheduling and performing jobs, handles a wide range of background job use cases, and is built to be fault-tolerant and easy to monitor. Its queue lives inside an existing SQL database rather than in a separate broker.
Which databases does Oban support?
Three engines ship: PostgreSQL, MySQL and SQLite3, with requirement floors of PostgreSQL 14 or newer, MySQL 8.4 or newer, or SQLite 3.37 or newer, alongside Elixir 1.15 and Erlang 24. The README says each engine supports the same core functionality but has differing levels of maturity and suitability for production, without enumerating the differences.
Does Oban keep finished jobs in the database?
Yes, and that is its stated distinguishing feature. After a job is processed the row is not deleted but retained to provide metrics, which allows inspection of historic jobs and aggregate data at the job, queue or argument level. Every queue also records runtime metrics to the database for monitoring health across nodes.
What does Oban Pro add to the free Oban library?
A licensed package of extensions, plugins and workers. It includes global concurrency and global rate limiting, queue partitioning and insert batching, execution hooks, structured and encrypted arguments at rest, chained execution, job workflows with dependencies, batch progress tracking, runtime configuration of schedules, queues and priorities with automatic scaling, and building jobs from ordinary functions without worker modules.
What are the requirements for running Oban?
Elixir 1.15 or newer, Erlang 24 or newer, and one of three databases: PostgreSQL 14 or newer, MySQL 8.4 or newer, or SQLite3 3.37.0 or newer. The repository also ships a compose file that starts database services with health checks, which is what the test suite runs against.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oban-bg-oban)Star history chart for your README
[](https://hysenlabs.com/projects/oban-bg-oban)Was this useful?