octokit.rb reports rate limiting as a 403, and its newest release predates a year of commits
Ruby toolkit for the GitHub API
At a glance
- What is it?
- Octokit.rb is a flat Ruby client for the GitHub API: positional arguments, an options hash, resource objects with dot access, and six authentication methods. The page is long and well organised, and the details worth reading are the ones where it contradicts the obvious expectation.
- Who is it for?
- The library fits a Ruby service that talks to the GitHub API and wants dot access to responses, hypermedia links and a documented exception hierarchy instead of raw HTTP. It does not fit a caller that branches on HTTP status codes without reading this page.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Ruby, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
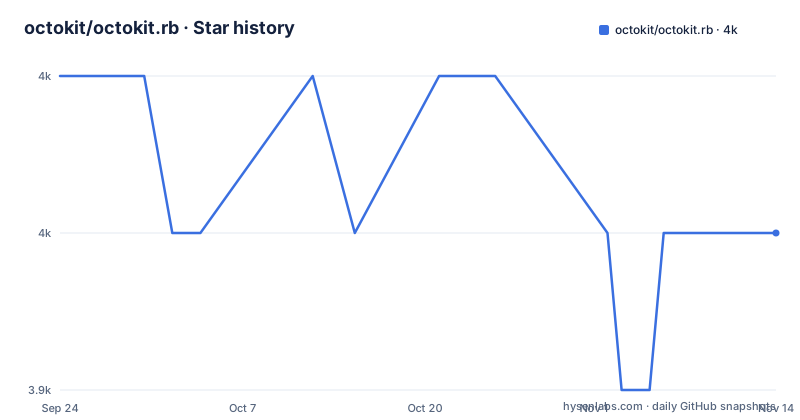
- octokit/octokit.rb3,950 ★ · -1
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| octokit/octokit.rb | 4k | 4k |
-1 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Rate limiting is reported as a forbidden response
The error section gives two mappings and they are worth reading together.
A bad request response raises one exception class. A forbidden response whose message says the rate limit was exceeded raises a different one, named after too many requests.
So the rate-limit condition arrives as a 403 and the client maps it, by message content, onto an exception named for the condition. That is the right behaviour for a user and a trap for a caller who branches on status codes: the numeric status and the semantic name disagree, and the page says nothing about how the message is matched.
Everything else inherits from the base error class, and each carries the response status, the response headers and the response body, so the underlying HTTP information is available for logging even when the exception type is the useful part.
Validation errors are the exception to that shape. Those return an array of hashes with the detail the API produced, which is the field to read when a request fails on input rather than on authentication.
Only the most recent response is reachable
There is a short section about reaching past the resource object to the raw HTTP response, and it names one method.
The client exposes the last response, and the example uses it to read an entity tag header from the call that just happened.
That is enough for caching a single resource and not enough for anything else. In a loop over a list of repositories, or in any code that issues a request and then inspects the response after further work, there is one response in hand and no index. The contents list has a caching section under advanced usage, which is where a fuller story would live, and it is not in the part of the page shown here.
So the practical rule is that any response you intend to keep has to be captured at the moment of the call. Reading it later is only safe when the next request has not happened.
URL fields are moved out of the resource into their own collection
Most methods return a resource object that gives you dot notation and bracket access for the fields the API returned. The example fetches a user, prints a name, prints the set of field names, and reads one field by bracket.
Then it reaches past the fields, into a separate collection, and reads a link.
The note underneath explains why: URL fields are culled into a separate collection for easier support of the hypermedia features later in the document.
That is a real design decision with two consequences. A field you expect to find on the object is not there if its value was a URL, and it lives under a link collection instead. And the printed set of field names in the example ends with a single gist-related entry, which is the visible consequence of that split on one real record.
The hypermedia sections are three of them, covering the agent, URI templates and what the page calls the full experience. Those are the reason the split exists, and they are also the reason the object does not look like the JSON it came from.
Two hash syntaxes and two documentation hosts in one page
The examples are not written in one style.
The first client example passes an option with the older rocket syntax, and so does the basic authentication example. The query-parameter examples use the newer symbol-key syntax. Both appear within a few screens of each other, and neither is marked as historical.
The documentation links are mixed the same way. The philosophy section links the GitHub API to an older developer documentation host, while the error section links the resource documentation to the current documentation site.
Neither is a defect and neither will stop your code. Together they date the page: a document that has been appended to over several major versions shows its seams in the places where new material meets old. Since the newest release is a two-digit major, the accumulated surface is larger than it looks.
One more seam is worth naming. The note at the top of the page is about renaming a maintenance branch called the 4-stable branch to main. That is a 4.x-era branch, and the current release line is 10.
Six authentication methods, and the easiest one is not the preferred one
The authentication section has six subsections: basic, access tokens, two-factor, a network credentials file, application authentication, and application identity for a GitHub App.
The first one is a username and a password in a single constructor call:
client = Octokit::Client.new(:login => 'defunkt', :password => 'c0d3b4ssssss!')It says using that is the easiest way to get started. The section after it says access tokens are the preferred way to authenticate on behalf of users, and gives the first of two benefits as revocability.
So the page documents a migration path and shows both ends of it in adjacent code blocks. The token example is a single access token in the same constructor, with a comment saying the older form still works if you put a personal access token where the password goes.
Six methods is a wide surface for a client, and it is the widest part of this page. Everything else in the library is a thin layer over one HTTP call, and this is where the design decisions live.
A rename note from the 4.x era sits above a 10.x release
The first thing on the page is a note saying that the 4-stable branch has recently been renamed to main, that this might affect anyone making changes to the library locally, and that a discussion post has the steps for reconfiguring a clone.
It is the first thing a reader sees, and it is about a branch from a major version that is six behind the current one. A clone made from a 4.x checkout is the only case it affects, and anyone starting fresh never sees the problem it describes.
The release history says the same thing in a different way. The three most recent releases are 10.0.0 from April 2025, 9.2.0 from October 2024 and 9.1.0 from June 2024. The last push to main is dated 2026-09-21.
So there have been seventeen months of commits since the newest major, and the page's most prominent warning is about a branch that stopped being the default four majors ago. Nothing on it says the library is between releases.
A lint todo file, a watcher, documentation options and a release guide at the root
The root of the repository is where the working arrangements are.
There is a linter configuration and a second file next to it that is the linter's own deferred-offences list, which is the mechanism for accepting a violation now and fixing it later. There is a test framework configuration, a documentation generator options file with a documentation directory beside it, a watcher configuration, and a release guide as a markdown file rather than a wiki page.
Two entries are unusual. There is a file whose name is a testing tool's abbreviation with no extension, and there is no changelog file at all. For a library with a two-digit major version and a documented upgrade guide, the release list is the changelog.
The licence file carries a markdown extension, and the homepage field is an address without a transport prefix, which means the plain-text form rather than the encrypted one. Small things, and all of them in the same category: a repository whose conventions were set over several major versions and are still visible at the top level.
Editorial conclusion
The library fits a Ruby service that talks to the GitHub API and wants dot access to responses, hypermedia links and a documented exception hierarchy instead of raw HTTP. It does not fit a caller that branches on HTTP status codes without reading this page. Check three things before you adopt it. Which status code you treat as a rate limit, because the client raises its own exception class for a forbidden response with a rate-limit message rather than for the code you would expect. Which response you want to inspect, because only the most recent one is reachable. And which version you pin, since the newest tag is from April 2025 while the branch has moved on since.
Frequently asked questions
How do I install octokit.rb?
Install the gem with gem install octokit, or add gem "octokit" to a Gemfile, and require it in your code. The client object is constructed with an access token, and API methods are called as instance methods on it.
How does octokit.rb report a GitHub API rate limit?
A forbidden response whose message says the rate limit was exceeded raises the client's too-many-requests exception class, while a bad request response raises a bad-request class. All of the exception classes inherit from the base error class and expose the response status, headers and body.
What authentication methods does octokit.rb support?
Six: username and password, access tokens, two-factor, a network credentials file, application authentication, and application identity for a GitHub App. The page calls the password method the easiest way to start and access tokens the preferred way to authenticate on behalf of users.
Can I read the HTTP response headers from octokit.rb?
Yes, for the most recent call. The client exposes the last response, and the page's example reads an entity tag header from it. There is no indexed access to earlier responses, so anything you need has to be captured at the time of the call.
What does an octokit.rb resource object give me?
Dot notation and bracket access for the fields the API returned, plus a separate collection for the URL fields, which are culled out to support the hypermedia features. Validation errors return an array of hashes with the detail the API supplied.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/octokit-octokit-rb)Star history chart for your README
[](https://hysenlabs.com/projects/octokit-octokit-rb)Was this useful?