CTranslate2: convert once, then run Transformer models on CPU or GPU
Fast inference engine for Transformer models
At a glance
- What is it?
- A C++ and Python inference runtime with a custom execution path: weights quantization, layer fusion, batch reordering, several CPU backends dispatched at runtime, and tensor parallelism for models too large for one GPU. The catch is the conversion step, since nothing loads until a checkpoint has been rewritten into the project's own format, and the published benchmark numbers are only valid for the one configuration that produced them.
- Who is it for?
- Fit if you serve Transformer models in production, care about memory as much as speed, and can accept a conversion step in your pipeline. Skip it if you need to load an unmodified checkpoint directly, or if you need a model family the support list does not name.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
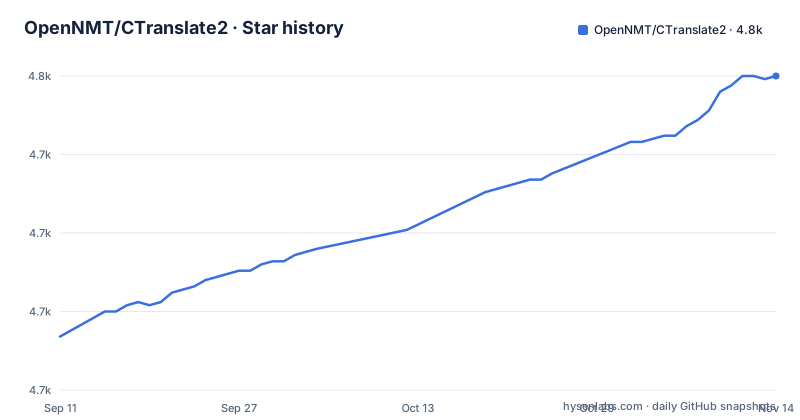
Star history
- OpenNMT/CTranslate24,750 ★ · +83
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| OpenNMT/CTranslate2 | 4.7k | 4.8k |
83 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
pip install ctranslate2, then a Translator and a Generator
Installation is one pip command:
pip install ctranslate2The Python module does two jobs: it converts models, and it runs them. A translation model and a generation model are handled by two classes, and both are driven a batch at a time:
translator = ctranslate2.Translator(translation_model_path)
translator.translate_batch(tokens)

generator = ctranslate2.Generator(generation_model_path)
generator.generate_batch(start_tokens)
`translate_batch` takes a list of token sequences, `generate_batch` takes start tokens, and the paths point at directories in the converted format rather than at original checkpoints. If you are on an AMD ROCm GPU, the pip package is not the whole story: specific Python wheels are published on the releases page instead. There is also a C++ API, and the project describes its integration surface as few dependencies and simple APIs in both languages, which is the claim to hold it against once you have wired one up.
Nothing loads until the checkpoint is converted
A compatible model has to be rewritten before CTranslate2 will touch it, and the library ships converters for the frameworks people actually arrive from: OpenNMT-py, OpenNMT-tf, Fairseq, Marian, OPUS-MT and Transformers. This is the single most consequential design decision in the project, because it means the model you download is not the model you run. A conversion step in your pipeline is a real cost: it becomes a build artifact, it needs to be re-run when the upstream checkpoint changes, and the converted directory becomes the unit you version and cache. The examples directory shows the shape of the result, with `examples/llama2`, `examples/llama3` and `examples/wngt2020` as the three named cases. The upside of that cost is the runtime described in the next sections, and the README is direct that several of those features are difficult to achieve with standard deep learning frameworks and are the motivation for the project.
Three model families, and the list is the contract
Supported models are enumerated in four groups, the fourth being experimental text-to-speech support for Drama 3, and reading them tells you immediately whether your model qualifies. Encoder-decoder models cover Transformer base and big, M2M-100, NLLB, BART, mBART, Pegasus, T5, Whisper, T5Gemma, T5Gemma2 and MADLAD-400. Decoder-only models cover GPT-2, GPT-J, GPT-NeoX, OPT, BLOOM, MPT, Llama, Mistral, Gemma, CodeGen, GPTBigCode, Falcon and Qwen2. Encoder-only models are the shortest list: BERT, DistilBERT and XLM-RoBERTa. Two things follow from that structure. Whisper sits in the encoder-decoder group, which is the entry point for speech translation and transcription workloads. And anything absent from these lists is unsupported, with no partial path described: the newest decoder-only architectures have to appear by name before you plan around them.
Five precisions, and quantization moves the BLEU score
Model serialization and computation accept reduced precision weights in five forms: 16-bit floating points, 16-bit brain floating points, 16-bit integers, 8-bit integers and AWQ quantization at 4 bits. On disk, quantization is stated to make models four times smaller with minimal accuracy loss, and the CPU benchmark lets you see what minimal means. On the OpenNMT-py WMT14 model, CTranslate2 3.6.0 scores BLEU 26.77 at 658.8 tokens per second and 849MB of memory; the int16 row is 733.0 tokens per second, 672MB and BLEU 26.82; the int8 row is 860.2 tokens per second, 529MB and BLEU 26.78. The speedups are substantial and the BLEU differences are small but not zero, so decide per model rather than per principle.
One binary carries several backends and picks at runtime
The CPU story is about dispatch. The project supports x86-64 and AArch64/ARM64 processors and integrates five backends optimized for those platforms: Intel MKL, oneDNN, OpenBLAS, Ruy and Apple Accelerate. A single binary can include more than one of them, along with several instruction set architectures such as AVX and AVX2, and the selection happens at runtime based on the CPU information. That is what makes one wheel set work across machines without a build matrix of your own, and it is also what makes the hardware relevant to your deployment: the backend chosen on an Intel server is not the one chosen on an Apple machine. On the execution side, multiple batches can be processed in parallel and asynchronously across several GPUs or CPU cores, and memory usage changes with request size while still meeting performance targets, thanks to caching allocators on both CPU and GPU. The named optimizations behind those numbers are layer fusion, padding removal, batch reordering, in-place operations and a caching mechanism.
The benchmark is one dataset, three models, one metric
The published numbers come from a deliberately narrow setup: the En to De test set newstest2014, with the metric being target tokens generated per second, aggregated over multiple runs, and the scripts in `tools/benchmark`. Three models are compared. The OpenNMT-tf WMT14 and OpenNMT-py WMT14 models are base Transformers trained on WMT14, which the README gives as 4.5M lines. The OPUS-MT model is a base Transformer trained with Marian on all OPUS data available on 2020-02-26, which is 81.9M lines. The CPU table shows OpenNMT-tf 2.31.0 with TensorFlow 2.11.0 at 209.2 tokens per second, 2653MB and BLEU 26.93, and OpenNMT-py 3.0.4 with PyTorch 1.13.1 at 275.8, 2012MB and 26.77. The README then states the caveat in bold on its own: the results are only valid for the configuration used during the benchmark, and absolute and relative performance may change with different settings. Treat the table as a demonstration of the mechanism, not as a prediction for your hardware.
Very large models need the parallelism setup first
Distributed inference is supported through tensor parallelism, which lets a very large model be split across multiple GPUs, and it is not a flag: the documentation at `docs/parallel.md` under model and tensor parallelism describes the environment that has to be set up. Anyone planning a multi-GPU deployment is expected to work from that page. The same pattern applies to accelerators in general, since ROCm support is delivered as separate wheels on the releases page rather than through the main package. A `docker/` directory and a `.dockerignore` sit alongside `cmake/`, `CMakeLists.txt`, `cli/`, `include/`, `src/`, `python/`, `tests/`, `third_party/` and `docs/`, which is the shape of a C++ project with CMake, a command-line tool and first-class Python bindings. The interactive decoding features fit in the same bucket of capability: advanced decoding can autocomplete a partial sequence and return alternatives at a specific position in it.
Compatibility is promised, experiments are bundled alongside
The project's stance is stated in one line: it is production-oriented and comes with backward compatibility guarantees, but it also includes experimental features related to model compression and inference acceleration. Both halves are true at once, and the versioning page is the document that decides which side you are on. That distinction matters for the compression features above, since quantization options are exactly the sort of thing that changes shape. The recent release line is steady: v4.8.5 on 2026-11-02, v4.8.4 on 2026-10-25 and v4.8.3 on 2026-10-13, with the last push to master on 2026-11-02, an MIT licence, and a `SECURITY.md` plus `CHANGELOG.md` in the tree. One related thing is deliberately outside the library: an OpenAI-compatible REST server is a separate project, ctranslate2-web-server, built on top of CTranslate2, so an existing OpenAI-shaped client can talk to a converted model without this repository providing the endpoint.
Editorial conclusion
Fit if you serve Transformer models in production, care about memory as much as speed, and can accept a conversion step in your pipeline. Skip it if you need to load an unmodified checkpoint directly, or if you need a model family the support list does not name. Before adopting, convert a model you care about and compare tokens per second and BLEU yourself, read the versioning policy that promises backward compatibility, and check which backend will be selected on your CPU.
Frequently asked questions
How do I install ctranslate2?
With pip, using `pip install ctranslate2`. If you have an AMD ROCm GPU, specific Python wheels are published on the repository's releases page rather than coming from the standard package.
What is CTranslate2?
A C++ and Python library for efficient inference with Transformer models. It implements a custom runtime using weights quantization, layer fusion and batch reordering to speed up inference and reduce memory usage on CPU and GPU, and compatible models must first be converted into its optimized format.
How does ctranslate2 compare to PyTorch?
On the En-De newstest2014 CPU benchmark with the OpenNMT-py WMT14 model, OpenNMT-py 3.0.4 with PyTorch 1.13.1 reaches 275.8 tokens per second, 2012MB and BLEU 26.77, while CTranslate2 3.6.0 reaches 658.8 tokens per second and 849MB with the same BLEU. The README notes those results hold only for that configuration.
How does ctranslate2 compare to transformers?
CTranslate2 includes a converter for Transformers models, and the README states that its execution is significantly faster and requires less resources than general-purpose deep learning frameworks on supported models and tasks. Its benchmark results are only valid for the configuration used.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opennmt-ctranslate2)Star history chart for your README
[](https://hysenlabs.com/projects/opennmt-ctranslate2)Was this useful?