Scala-Machine-Learning-Projects is eleven chapters and no root build
Scala Machine Learning Projects, published by Packt
At a glance
- What is it?
- Packt's Scala Machine Learning Projects repository holds the supporting code for a book, organised as Chapter01 through Chapter11, one project per folder. There is no aggregator build at the root, the version floors are all from the 2017 era, and the last commit is dated 16 July 2023.
- Who is it for?
- This repository suits a reader working through the book who wants the code that matches each chapter, or a Scala developer looking for worked examples across five machine learning frameworks. It does not suit anyone wanting a maintained library, since it has no continuous integration, no contribution guide and no commits since 16 July 2023.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 40 months ago, on July 16, 2023.
- What is it written in?
- Mainly Scala, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
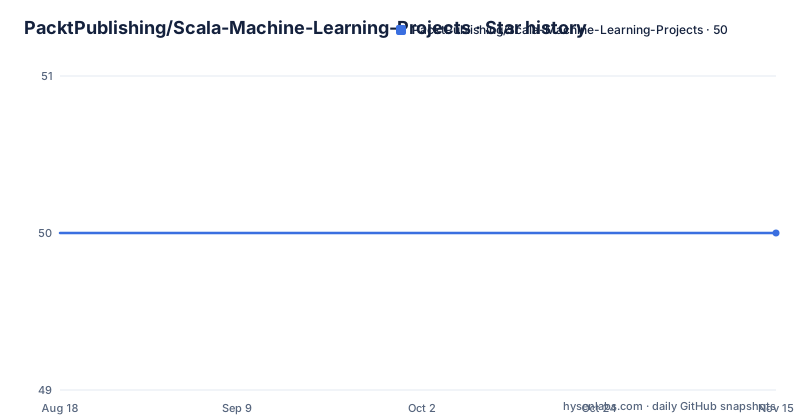
- PacktPublishing/Scala-Machine-Learning-Projects50 ★ · +0
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| PacktPublishing/Scala-Machine-Learning-Projects | 50 | 50 |
0 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Eleven folders, one project each, and no root build
The navigation rule is stated in a single sentence: all of the code is organised into folders, and each folder starts with a number followed by the application name, with Chapter02 given as the example. The top level confirms it, holding exactly eleven directories from Chapter01 through Chapter11 plus a licence file and the README. Eleven folders matches the eleven end-to-end projects the book promises, so the mapping between chapter and project is one to one. What is missing at the top level is more interesting than what is present: there is no pom.xml, no build.sbt and no aggregate module, even though the README assumes familiarity with Maven and SBT. The build configuration therefore lives inside the chapters, and the README points readers to the pom.xml files supplied there rather than to anything in the root.
Five frameworks, and they do not share a runtime
The library set named across the book is Spark ML, H2O, MDP, DeepLearning4j and MXNet, with Zeppelin listed among the tooling and Hadoop among the requirements. That list spans two different worlds. Spark ML, H2O, MDP and DeepLearning4j run on the JVM and share the Scala build tools the README assumes. MXNet is a different kind of dependency, with its own runtime and its own language bindings, and the fact that the README instructs readers to check the chapter and the supplied pom.xml files for it rather than listing a version is a sign that each project assembles its own stack. Zeppelin appears alongside them as the notebook environment for the examples rather than as a library, which is why the requirement list mixes what you compile against with what you run.
Every version floor sits in the 2017 range
The requirement list is where the age of this repository becomes concrete, and the numbers are specific: Apache Spark 2.0.0 or higher, Hadoop 2.7 or higher, Scala 2.11.x or higher, and Java with JDK and JRE at 1.7 or 1.8. On top of that, a specific IDE generation is named, Eclipse Mars or Luna, with a Maven plugin at 2.9 or higher, a Maven compiler plugin at 2.3.2 or higher and a Maven assembly plugin at 2.4.1 or higher. The examples were developed on Ubuntu 16.04 LTS 64-bit and Windows 10 64-bit. Read together, these are the toolchain numbers of a book written around Spark 2.0, and the last commit to the repository is dated 16 July 2023. Nothing in the repository has been revisited since, so the floors have not moved even though the ecosystem has.
The audience paragraph describes two different readers
There is a genuine tension inside the README's own description of who this is for, and it is worth naming rather than smoothing over. The about section says the book is for data scientists, data engineers and deep learning enthusiasts who have a good background with complex numerical computing. A few paragraphs later the instructions say it is dedicated to developers and deep learning enthusiasts who do not have much background with complex numerical computations, and that a strong understanding of Scala and its functional programming concepts is recommended. Those two sentences point in opposite directions: one assumes the numerics, the other assumes the reader lacks them and is looking for an introduction. The same paragraph lists the file as having run-together words in it, which suggests the copy was assembled quickly and not reconciled.
The single code sample is a genomic variant identifier
Exactly one piece of code appears in the README, and it is worth reading closely because it sets the register for the projects. The snippet formats a genomic interval into a string key, taking a genotype, pulling the contig name, the start and the end from the underlying variant, and interpolating them into a colon-separated identifier:
def variantId(genotype: Genotype): String = {
  val name = genotype.getVariant.getContigName
  val start = genotype.getVariant.getStart
  val end = genotype.getVariant.getEnd
  s"$name:$start:$end"
}
It is a pattern-matching exercise on a domain object rather than a machine learning algorithm, which tells you what the chapters are like: real data types, small functions, and results you can inspect. Nothing in the README shows a model being trained or a metric being computed, so the eleven projects have to be read in their folders rather than skimmed from here.
No CI, no contributing guide, and an MIT licence
What the repository does not contain matters as much as what it does. There is no GitHub directory, so no continuous integration runs the examples; there is no contributing file, so there is no stated process for reporting a broken chapter; and there are no tagged releases, so the eleven folders are the only versioned artefacts. The single licence file at the root is MIT, which is a permissive grant and unusually generous for book code, and it means the projects can be lifted into another project without a separate negotiation. The README also carries the publisher's related-products list and an offer of a DRM-free PDF for readers who bought a print or Kindle copy, both of which are part of the book's storefront page rather than the code. Read the repository as eleven self-contained examples and nothing more.
Editorial conclusion
This repository suits a reader working through the book who wants the code that matches each chapter, or a Scala developer looking for worked examples across five machine learning frameworks. It does not suit anyone wanting a maintained library, since it has no continuous integration, no contribution guide and no commits since 16 July 2023. Before you start, check three things: whether the chapter you need builds with a modern toolchain at all, given floors of Spark 2.0.0, Hadoop 2.7, Scala 2.11 and Java 8, whether the framework that chapter uses is still the one you would pick, and whether you want examples rather than a maintained dependency.
Frequently asked questions
What does the Packt Scala Machine Learning Projects repository contain?
The supporting code for the book, organised as eleven chapter folders from Chapter01 to Chapter11, one project per folder. There is no aggregator build at the root; the README points readers to the pom.xml files supplied inside the chapters rather than to a single top-level build.
What do I need to run the Scala Machine Learning Projects code?
Apache Spark 2.0.0 or higher, Hadoop 2.7 or higher, Scala 2.11.x or higher, Java JDK and JRE at 1.7 or 1.8, plus MXNet, Zeppelin, DeepLearning4j and H2O as described in each chapter. Build tooling assumed is Maven and SBT with an IDE such as IntelliJ, and the examples were developed on Ubuntu 16.04 LTS and Windows 10, both 64-bit.
Which machine learning libraries do the Scala Machine Learning Projects cover?
Five are named across the eleven projects: Spark ML, H2O, MDP, DeepLearning4j and MXNet, with Zeppelin as the notebook environment and Hadoop among the platform requirements. Versions for MXNet, Zeppelin, DeepLearning4j and H2O are not listed centrally and are left to each chapter and its pom.xml files.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/packtpublishing-scala-machine-learning-projects)Star history chart for your README
[](https://hysenlabs.com/projects/packtpublishing-scala-machine-learning-projects)Was this useful?