The Well: 16 simulation datasets, one exact dependency pin, and a deprecation kept for comparison
A 15TB Collection of Physics Simulation Datasets
At a glance
- What is it?
- The Well is a 15TB collection of numerical physics simulations packaged as a Python library with a downloader, a Hugging Face streaming path and a hydra based benchmark. The interesting parts are the uneven dataset sizes, the single pinned dependency, and what the project admits about its own baselines.
- Who is it for?
- The Well is worth a look if you are training surrogate models on physical simulations and can store terabytes locally, and it is a poor fit for a laptop, a quick tutorial, or anyone expecting state of the art numbers from the published checkpoints.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 27 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
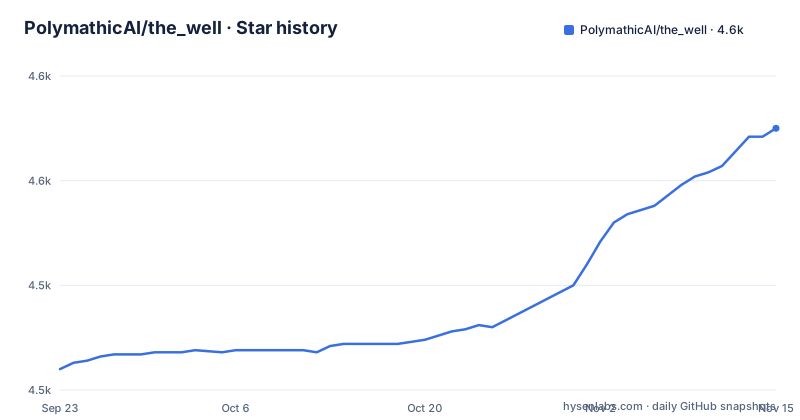
Star history
- PolymathicAI/the_well4,575 ★ · +115
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| PolymathicAI/the_well | 4.5k | 4.6k |
115 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One downloader script, 16 datasets, sizes from 6.9GB to 5.1TB
The Well gathers numerical simulations of spatiotemporal physical systems from domain scientists and numerical software developers, and the project puts the total at 15TB across 16 datasets. The domains named are biological systems, fluid dynamics, acoustic scattering, and magnetohydrodynamic simulations of extra-galactic fluids or supernova explosions. Sizes are very uneven. An individual dataset runs from 6.9GB to 5.1TB, so the largest ones are a different order of magnitude from the rest of the collection and the disk planning problem is really about them. Fetching is done with a console script that pyproject.toml declares as the-well-download, mapped to the_well.utils.download:main, taking three named arguments:
the-well-download --base-path path/to/base --dataset active_matter --split trainLeave out --dataset and --split and it pulls every dataset and every split, which the page warns could take a while.
The venv instructions activate a path the first line never creates
The installation advice starts by recommending a fresh Python environment of 3.10 or newer, with venv as the worked example. The two lines given there do not agree with each other. The first creates the environment at path/to/env, and the second asks you to source path/to/env/activate/bin.
python -m venv path/to/env
source path/to/env/activate/bin
A venv created at path/to/env puts its activation script in a bin directory inside that path, and the second line reads as though that bin directory sat inside a subdirectory named activate. Anyone typing both lines in order runs into a missing file at the second one. It is a small inconsistency next to a page that spells out CUDA wheel indexes and Slurm job scripts, but it belongs to the very first command pair a new user is told to run.
Streaming from the hub instantiates slowly and reads as a convenience
Most datasets are also hosted on Hugging Face, and the same WellDataset class reads them without a local copy by pointing well_base_path at an hf:// URL. The published example carries an inline comment marking the delay:
from the_well.data import WellDataset
from torch.utils.data import DataLoader

# The following line may take a couple of minutes to instantiate the datamodule
trainset = WellDataset(
    well_base_path="hf://datasets/polymathic-ai/",  # access from HF hub
    well_dataset_name="active_matter",
    well_split_name="train",
)
train_loader = DataLoader(trainset)
The page then advises downloading to local disk instead of streaming when training at scale, which puts the streaming path in the role of a convenience for inspection and smaller runs rather than the intended way to work through 15TB. The class takes the same three names in both examples: base path, dataset name, split name, so moving between local data and the hub changes one string.
The benchmark is hydra configs, and the paper baselines are called simple
Benchmarking surrogate models runs through hydra, which assembles the dataset, the model and the optimizer from YAML files in the benchmark configs directory. One command sets all three axes at once:
cd the_well/benchmark
python train.py experiment=fno server=local data=active_matter
Every argument names a configuration file, and server=local resolves to local.yaml, which declares only a relative path to the data. The same command can be placed inside an sbatch script for Slurm. Checkpoints load through the model classes, with the FNO example resolving a hub identifier:
from the_well.benchmark.models import FNO

model = FNO.from_pretrained("polymathic-ai/FNO-active_matter")
What the page does not do is sell accuracy. It says the models benchmarked in the original paper were designed as a simple baseline and should not be considered state-of-the-art, and asks for better architectures for PDE surrogate modeling to be built on top of them.
Five dependencies take a floor, fsspec takes a single exact release
The project file declares six runtime dependencies. Five carry a lower bound: einops>=0.8, h5py>=3.9.0, numpy>=1.20, pyyaml>=6.0 and torch>=2.1. The sixth, fsspec==2024.10.0, is pinned to one exact release, which makes it the only dependency your environment cannot drift away from, and therefore the first thing to check when a resolve fails in an environment that already has a newer fsspec. The build backend is setuptools, package discovery is limited to the_well*, and exactly one package data file ships with it, utils/registry.yaml. The version is declared dynamic rather than written into the file, the license is referenced as a file instead of an SPDX expression, and the classifiers mark the package as Development Status 5, Production/Stable, audience Science/Research, listing Python 3.10 through 3.13 and OS Independent.
A deprecated dataset stays downloadable for backwards comparisons
The usage notes carry exactly one deprecation, and it concerns data quality rather than a feature. The dataset viscoelastic_instability is deprecated because of processing errors in the data. It remains available, which the page frames as useful for backwards comparisons, and a replacement named viscoelastic_instability_v2 is said to contain the same data without the processing error. That arrangement keeps old training scripts running and keeps producing results derived from the flawed processing, and nothing inside the collection forces the move to v2.
Three install routes, one of which hands PyTorch to a CUDA index
Installation is offered three ways and they cost different amounts of attention. PyPI is the shortest:
pip install the_wellInstalling from source clones the repository, changes into the_well directory and runs pip install ., with an added flag when the accelerator matters: pip install . --extra-index-url https://download.pytorch.org/whl/cu121 resolves the wheels built for CUDA 12.1. Running the benchmarks is a third step, because the training script needs extras that the base install does not pull:
pip install the_well[benchmark]Those extras are the reason the base package stays small even though the data does not: the six runtime dependencies are a few libraries, while the payload a user actually cares about arrives later through the downloader or the hub.
One dataset collection, several identifiers, and docs built by mkdocs
The top of the page carries the identifiers for the same body of work: an arXiv link numbered 2412.00568, an OpenReview forum entry, a Hugging Face collection, and a PyPI badge whose address uses the hyphenated form the-well while the install command uses the underscored package name. The repository keeps a separate CITATION file at the top level next to LICENSE, README.md and a pre-commit config. The attribution paragraph names Polymathic AI as the lead organization, in collaboration with researchers from the Flatiron Institute, the University of Colorado Boulder, the University of Cambridge, New York University, Rutgers University, Cornell University, the University of Tokyo and Los Alamos National Laboratory. Alongside the package directory the tree holds docs with an mkdocs.yml for the site, plus tests, scripts and a datasets directory.
Editorial conclusion
The Well is worth a look if you are training surrogate models on physical simulations and can store terabytes locally, and it is a poor fit for a laptop, a quick tutorial, or anyone expecting state of the art numbers from the published checkpoints. Verify three things before committing disk: which of the 16 datasets you actually need, since they range from 6.9GB to 5.1TB, whether your environment can satisfy the single fsspec pin, and whether any of your existing pipelines still point at the deprecated viscoelastic_instability split rather than its v2 replacement.
Frequently asked questions
How much data does The Well contain?
The collection is described as 15TB in total, spread across 16 datasets covering biological systems, fluid dynamics, acoustic scattering and magnetohydrodynamic simulations. Individual datasets are not uniform in size: they range from 6.9GB to 5.1TB each, so disk planning is driven by the largest ones.
How do I install the_well and fetch a single dataset?
Install with pip install the_well, or clone the repository and run pip install . from the the_well directory. Once installed, the bundled console script takes a base path, a dataset name and a split, for example the-well-download --base-path path/to/base --dataset active_matter --split train. Omitting the dataset and split arguments downloads everything in the collection.
Can The Well datasets be streamed from Hugging Face?
Yes. Most datasets are hosted on the Hugging Face hub, and passing an hf:// path as well_base_path makes the same WellDataset class read them without a local copy. The example notes that instantiating the datamodule may take a couple of minutes, and the project advises downloading locally instead when training at scale.
Which The Well dataset has been deprecated?
viscoelastic_instability is deprecated because of processing errors in the data, and it is kept available for backwards comparisons. viscoelastic_instability_v2 contains the same data without the processing error, so existing pipelines pointing at the original name will keep running against the flawed version.
How good are the model checkpoints shipped with The Well?
The project says the models benchmarked in its original paper were built as a simple baseline and should not be considered state-of-the-art, and it asks the community to build better architectures for PDE surrogate modeling on top of those results. Checkpoints for most models are published on Hugging Face and load through the model classes.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/polymathicai-the-well)Star history chart for your README
[](https://hysenlabs.com/projects/polymathicai-the-well)Was this useful?