twitter-cli: A Cookie-Authenticated Terminal Client for Twitter/X With Its Own Ranking Filter and Ban-Avoidance Advice
A CLI for Twitter/X — feed, bookmarks, and user timeline in terminal
At a glance
- What is it?
- twitter-cli reads timelines, bookmarks, searches and profiles from Twitter/X in the terminal, and can also post, like and delete, using your browser session instead of API keys. That convenience carries account risk, and the README says so.
- Who is it for?
- twitter-cli suits developers who want scriptable Twitter/X reads with YAML or JSON output and accept that it acts as their logged-in browser session. It does not suit anyone who cannot risk an account restriction or who needs a stable, supported API.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
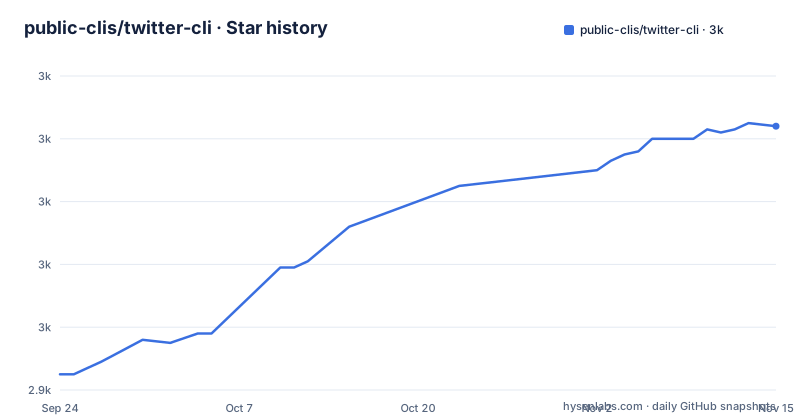
- public-clis/twitter-cli3,024 ★ · +79
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| public-clis/twitter-cli | 2.9k | 3k |
79 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It borrows your logged-in browser session instead of using API keys
The README describes a terminal-first CLI for Twitter/X that reads timelines, bookmarks and user profiles without API keys. It gets access by using cookies from your own browser session. That is why it can reach your For You and Following feeds and your bookmarks, which an unauthenticated tool cannot.
The consequence is that every command is made as you. A fetch looks like your browser asking for a timeline, and a write command posts, likes or deletes from your account. There is no separate application identity with its own rate limits and terms. If the service decides the traffic is unwelcome, it is your account that is affected, which is why the README includes a section on avoiding bans. It is an unofficial client, so its behavior can break whenever the service changes how its web interface talks to the server.
Authentication tries environment variables first, then scans five browsers
The auth priority is explicit. First come the environment variables TWITTER_AUTH_TOKEN and TWITTER_CT0. Second, and recommended, is automatic extraction of browser cookies from Arc, Chrome, Edge, Firefox or Brave. Browser extraction forwards all Twitter cookies, not just auth_token and ct0, and aligns request headers with your local runtime, which the README says is closer to normal browser traffic.
Chrome profiles are all scanned by default. To pick one, set the variable on the command line:
TWITTER_CHROME_PROFILE="Profile 2" twitter feedIf you have several browsers, set TWITTER_BROWSER to try one first:
TWITTER_BROWSER=chrome twitter feed # Supported: arc, chrome, edge, firefox, braveAfter loading cookies the CLI does a lightweight verification, and commands that need account access fail fast on clear 401 or 403 errors. The cost of the recommended path is that the tool reads cookie stores from your browsers, which is a sensitive capability to run on a shared machine.
Reads cover feeds, search, threads, Articles, Lists and user data, with output meant for scripts
The read side includes fetching the for-you and following feeds, listing bookmarks, searching by keyword with Top, Latest, Photos and Videos tabs, viewing a tweet and its replies, fetching a Twitter Article and exporting it as Markdown, reading a List timeline, and looking up a user's profile, tweets, likes, followers and following. The show command with a number opens tweet N from the last list output.
For scripting, any data can be exported as YAML or JSON, and the output contract is documented in SCHEMA.md. The README's tip for AI agents is to prefer YAML unless a strict JSON parser is required; when stdout is not a TTY, YAML is the default automatically. It also recommends limiting results with --max. In a terminal, tables truncate long tweet text unless you pass --full-text. Search accepts filters like from, lang and since, so a narrow query costs less than fetching a broad feed and filtering it locally.
Write commands add random delays of 1.5 to 4 seconds
The write side can create new tweets and replies with up to four image attachments, quote-tweet with optional images, delete your own tweets, like and unlike, retweet and unretweet, and bookmark or unbookmark, with favorite and unfavorite kept as compatibility aliases. Write commands also support explicit JSON or YAML output.
To mitigate rate limits, write operations wait a random 1.5 to 4 seconds. That delay is built in, so a script that posts or likes in a loop will be slower than it looks and cannot be sped up by this tool alone. It also means the delay is a mitigation, not a guarantee: the README presents it as reducing risk. Because deletes and posts act on your real account, test any automation against throwaway content first. There is no dry-run mode mentioned in the visible README.
The anti-detection layer exists because the tool is not an official client, and it needs upgrading
The README lists several techniques under Auth and Anti-Detection: TLS fingerprint impersonation using curl_cffi with dynamic Chrome version matching, generation of the x-client-transaction-id header, request timing jitter to avoid pattern detection, and the full cookie forwarding described earlier.
These are signs of how fragile the arrangement is. The tool has to look like a browser to be served, and what looks like a browser changes over time. The README says so in its own tip: upgrade regularly to avoid unexpected errors from outdated API handling. Its best-practices list for avoiding bans advises a proxy, low request volumes such as --max 20 instead of --max 500, not running too frequently because each startup fetches x.com to initialize the headers, using browser cookie extraction, and avoiding datacenter IPs. Take that list as a statement of risk. Using this tool may violate the service's terms, and an account restriction is a plausible outcome.
A scoring filter ranks tweets by weighted engagement, and it is off unless you pass --filter
Ranking is optional. By default there is no ranking filter; with --filter the tweets are scored and sorted using the filter section of config.yaml, read from your working directory. The default weights give bookmarks the most influence:
filter:
  mode: "topN"          # "topN" | "score" | "all"
  topN: 20
  minScore: 50
  lang: []
  excludeRetweets: false
  weights:
    likes: 1.0
    retweets: 3.0
    replies: 2.0
    bookmarks: 5.0
    views_log: 0.5
Three modes exist. topN keeps the highest topN by score, score keeps tweets at or above minScore, and all returns everything after sorting. The views term uses log10 of the larger of views and one, so very large view counts add little. The rateLimit section sets a base request delay of 2.5 seconds randomized between 0.7 and 1.5 times, three retries on a 429 response, and a hard cap of 200 fetched items. Because config.yaml is read from the working directory, running from a different folder changes behavior.
Install with uv or pipx, and treat a 0.8.6 Alpha package with no releases as a moving target
The recommended install is a uv tool, with pipx as the alternative:
# Recommended: uv tool (fast, isolated)
uv tool install twitter-cli

# Alternative: pipx
pipx install twitter-cli
Upgrades use uv tool upgrade twitter-cli, or pipx upgrade twitter-cli. For source, clone the repository, change into it and run uv sync. The project requires Python 3.10 or newer, and the dependencies include browser-cookie3, click, rich, PyYAML, curl_cffi, xclienttransaction and beautifulsoup4.
The package metadata puts the version at 0.8.6 and classifies it as Development Status 3, Alpha. The repository has no GitHub releases, and the last push was on 2026-05-07, so pin the version you tested and check for newer commits before blaming your setup when requests start failing. The root also holds SKILL.md and AGENTS.md for agent use.
Editorial conclusion
twitter-cli suits developers who want scriptable Twitter/X reads with YAML or JSON output and accept that it acts as their logged-in browser session. It does not suit anyone who cannot risk an account restriction or who needs a stable, supported API. Use a secondary account first and keep request volumes low.
Frequently asked questions
Does twitter-cli need Twitter API keys?
No. It authenticates with cookies, either from the TWITTER_AUTH_TOKEN and TWITTER_CT0 environment variables or extracted from Arc, Chrome, Edge, Firefox or Brave.
How do I install twitter-cli?
Run uv tool install twitter-cli, or pipx install twitter-cli. It requires Python 3.10 or newer, and uv tool upgrade twitter-cli updates it.
Can twitter-cli get my account banned?
The README includes a best-practices section on avoiding bans, advising a proxy, low request volumes and residential IPs. It is an unofficial client acting as your session, so the risk is real.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/public-clis-twitter-cli)Star history chart for your README
[](https://hysenlabs.com/projects/public-clis-twitter-cli)Was this useful?