The Python PEP Index Is Generated, and docutils Is Held Below 0.22
Python Enhancement Proposals
At a glance
- What is it?
- The repository behind peps.python.org is a Sphinx site with strict warning handling, a hard ceiling on docutils, and an index that nobody edits by hand. Those three facts explain most of how the site is built and reviewed.
- Who is it for?
- The peps repository is the right place to work if you are drafting a Python Enhancement Proposal, since the metadata headers, the lint suite and the per-pull-request render preview are all built for that job. It is the wrong place to look for a statement of what the language does today, because the site documents proposals and their status rather than a spec you can code against.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly reStructuredText, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
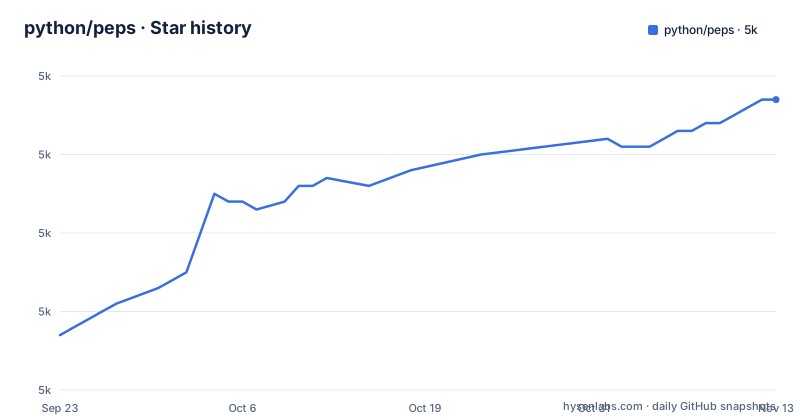
- python/peps5,037 ★ · +30
| Repository | 2026-09-23 | 2026-11-13 |
|---|---|---|
| python/peps | 5k | 5k |
30 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Nobody edits the index, the metadata headers do it
PEP 0 is the index, and it is not a file anyone maintains by listing proposals. It is generated automatically from the metadata headers carried by the other PEPs, so a proposal's own header block is what puts it on the index page. If a header is missing or malformed, the entry is wrong or absent, and the fix belongs in the proposal rather than in the index. That single design decision is why the repository treats header fields as load-bearing rather than decorative. Reading order matters too: the README points new contributors at PEP 1 for the purpose of PEPs and how to go about writing one, and only then at the index. For anything machine-readable, several data files are published at https://peps.python.org/api/, which is the route to take if you want proposal metadata without parsing HTML. The site itself is not maintained by hand either: the PEPs in the repository are published automatically to the web, so what you read online is whatever the main branch rendered.
Cite the zero-padded URL, not the redirect
There are two forms of every link, and only one of them is canonical. The canonical form is zero-padded, so a proposal is addressed as https://peps.python.org/pep-0008/ rather than https://peps.python.org/8. The short form still works because the site issues redirects, and https://peps.python.org/8 lands on the canonical address. The distinction matters when a URL ends up in a bug report, a comment in code, or a citation that someone else will maintain: the redirect is a convenience layer, and a link that depends on it is one more thing that can change under you. Use the padded form in anything you intend to keep. The same convention shows up in the build itself, where the html target renders proposal files to pep-NNNN.html and a separate dirhtml target renders an index.html inside pep-NNNN directories, which is the shape the canonical URL uses.
The build fails on warnings, so a deprecation breaks the site
The strictest thing in the repository is not a lint rule but a Sphinx flag. The Makefile sets its error handling to three options at once:
BUILDDIR     = build
SPHINXBUILD  = PATH=$(VENVDIR)/bin:$$PATH sphinx-build
BUILDER      = html
SPHINXERRORHANDLING = --fail-on-warning --keep-going --warning-file sphinx-warnings.txt
Because warnings are failures, any deprecation notice from the toolchain can stop a proposal from rendering. The --keep-going flag means the build does not stop at the first problem, it collects everything into sphinx-warnings.txt, so a single run tells you the full list of what needs fixing. That combination explains a lot of otherwise odd choices in this repository. It also explains why a typo in a cross-reference is treated with the same weight as a syntax error, which is what the README asks contributors to avoid when it warns against committing changes that cause generation to fail or produce major rendering defects relative to what you intended. Contributors are not asked to keep the prose clean for taste, but to keep the build green.
docutils is pinned below 0.22 because 0.22 broke the build
One ceiling in the requirements file carries a comment explaining itself, which makes it the most informative line in the repository:
pygments >= 2.21
Sphinx >= 8.2
docutils < 0.22
pagefind[bin] >= 1.5.0
The comment says 0.22 causes build errors and points at issue 4924, so docutils is held below that version until the incompatibility is resolved. Everything else moves forward instead: Sphinx is at 8.2 or newer, and the pygments floor of 2.21 is justified in the file by Sphinx requiring 2.17, JSON5 support arriving in 2.19 and the lazy highlight feature in 2.21. The remaining entries divide by purpose: sphinx-notfound-page at 1.0.2 or newer, pagefind with its bin extra at 1.5.0 or newer for search, pytest at 9 or newer plus pytest-cov for tests, and tomli for interpreters older than 3.11 so the releases data file parses. Note the asymmetry, one dependency frozen below a release while the rest are free to advance, and remember that a ceiling cannot be lifted by installing a newer docutils locally.
Ruff fixes what it finds and does not measure line length
The Python tooling in this repository is linted by ruff, configured in pyproject.toml:
[tool.ruff]
target-version = "py311"
fix = true
output-format = "full"
Two settings shape contributor experience. fix = true means ruff rewrites files instead of only reporting problems, so running it changes your working tree. output-format = full selects ruff's full diagnostic output. The rule selection is a named list rather than a preset: pycodestyle errors, pyflakes, isort, flake8-pytest-style, pyupgrade, pycodestyle warnings and flake8-2020, with E501, line too long, explicitly ignored. That last exclusion is a deliberate choice, and it tells you something about the codebase: long lines are tolerated here. Alongside the config sit .pre-commit-config.yaml, tox.ini, .pytest.toml, check-peps.py and a .codespell directory with a .codespellrc, so checks can run on demand, automatically at commit time, or through tox.
Every pull request carries one preview check you have to expand to find
Reviewing a rendered proposal is part of the workflow, not an extra. For each pull request a preview of the rendered PEPs is created through Read the Docs, and finding it takes three steps: click Show all checks to expand the checks section, find the line named docs/readthedocs.org:pep-previews, then click Details to its right. The detail that this check has to be expanded to find is the practical cost, since a reviewer working from the checks summary may never see it. The preview is what makes the strict warning policy workable, because a rendering change is visible before merge rather than after the automatic publish. The configuration behind it sits in .readthedocs.yaml at the repository root. One habit follows from the setup: read your own preview before requesting review, since a broken cross-reference or a malformed directive shows up there first.
Live reload uses a hardcoded port and hides warnings from four paths
Rendering locally is a three-step affair in a fresh activated virtual environment:
# Install requirements
python -m pip install -U -r requirements.txt

# Build the PEPs
make html

# Or, if you don't have 'make':
python build.py
Output lands under the build directory, and the Makefile points at a .venv with uv available for setup. The convenience targets build on that same output: htmlview opens build/index.html in your browser, search rebuilds the search index with pagefind, dirhtml produces the directory layout and then moves 404/index.html to 404.html, and linkcheck checks validity of links inside the proposals. The htmllive target is where the tradeoffs show. It runs sphinx-autobuild on port 55302 with --delay 0 and --open-browser, and it passes a re-ignore list covering .idea, venv, numerical.rst, pep-0000.rst and /topic/. Two consequences: two checkouts cannot both run the live server on that fixed port, and changes to those ignored paths do not trigger a rebuild. The target also replaces SPHINXERRORHANDLING, so the live build does not use --fail-on-warning.
Editorial conclusion
The peps repository is the right place to work if you are drafting a Python Enhancement Proposal, since the metadata headers, the lint suite and the per-pull-request render preview are all built for that job. It is the wrong place to look for a statement of what the language does today, because the site documents proposals and their status rather than a spec you can code against. Before you start, read PEP 1 for the process and check the status headers of the proposals you plan to cite, since acceptance and implementation are separate things. If you build the site locally, expect to spend time on Sphinx warnings rather than on content, because the build treats a warning as a failure.
Frequently asked questions
What are PEPs in Python?
Python Enhancement Proposals, held as reStructuredText sources in this repository and published automatically at peps.python.org. The repository README directs anyone writing one to start with PEP 1 for the purpose and the process, and notes that PEP 0, the index, is generated from the metadata headers in the other PEPs rather than maintained by hand.
What do PEPs stand for in Python?
They stand for Python Enhancement Proposals, which is also the repository description. Several machine-readable data files are published at https://peps.python.org/api/, so metadata can be consumed without parsing the rendered HTML pages.
what is python peps
The source repository for the Python Enhancement Proposals website, plus the tooling that renders it. It contains build.py, check-peps.py, a Makefile with html, htmlview, htmllive, dirhtml, search and linkcheck targets, a Sphinx requirements file, a ruff configuration in pyproject.toml, and a pre-commit suite for linting and spelling.
Is Pep 8 still used?
This repository records proposals and their headers, not adoption. PEP 8 is reachable at its canonical zero-padded address, https://peps.python.org/pep-0008/, with https://peps.python.org/8 redirecting there, and whether a given proposal is followed in practice is not something the sources or the generated index record.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/python-peps)Star history chart for your README
[](https://hysenlabs.com/projects/python-peps)Was this useful?