local-path-provisioner and the moment the data is deleted
Dynamically provisioning persistent local storage with Kubernetes
At a glance
- What is it?
- A Kubernetes provisioner that turns each node's own disk into dynamically provisioned volumes, with per-node path maps, a shared-filesystem option for multi-writer access, and a helper pod that is allowed to run on nodes under disk pressure. The persistence it offers lasts exactly as long as the claim, and the file says so in one sentence near the end.
- Who is it for?
- This provisioner fits a cluster where the nodes already have disk, where losing a node means losing its data anyway, and where running a distributed storage system would be more machinery than the problem deserves. Four things to know before you adopt it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
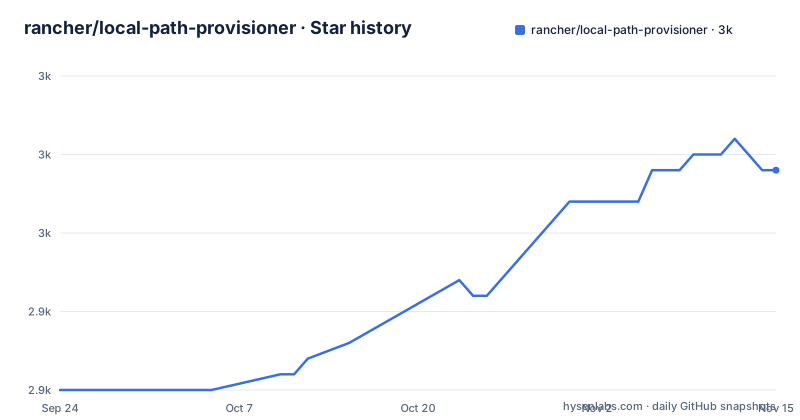
- rancher/local-path-provisioner2,954 ★ · +14
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| rancher/local-path-provisioner | 2.9k | 3k |
14 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Persistence ends when the claim is deleted, not when the pod is
The usage tour is built to prove one thing. It creates a claim and a pod, writes a file into the volume, deletes the pod, recreates the pod, and reads the file back successfully. That is the guarantee: the data outlived the workload. Then the tour ends with two deletions, the pod and the claim, and one sentence: the volume content stored on the node is cleaned up automatically, with details in the provisioner log. The example output shows the reclaim policy as Delete. So a claim is a lease on a directory rather than a record of a resource, and anyone reading only the first half of this section will come away with a different mental model than anyone reading the whole of it.
A node listed with an empty list refuses to be provisioned
Where data lives is a map from node name to a list of paths, and the rules for reading that map are short enough to hold in your head. A node that is not listed uses the paths in the default entry for unlisted nodes. A node that is listed uses the paths in its own entry. A node that is listed with an empty list gets nothing: the provisioner refuses to provision on it, which is how you exclude a node from storage without touching its other workloads. And a node listed with more than one path has the path chosen randomly at provisioning time. That last rule is the one to plan around, because the paths are not weighed against each other, so a node with a small and a large disk will place volumes by coin flip.
ReadWriteMany only appears when one filesystem is shared
By default the volumes are node-local, which is why the access modes are limited. Setting the shared filesystem path switches the provisioner onto a filesystem that is mounted on every node at the same time, and only in that case does it support all three access modes: single writer single reader, many readers single writer, and many writers. The tree carries example directories for shared filesystems and for a single-writer-pod access mode, and the visible text never names that last one, which suggests a feature documented elsewhere or not yet. For anyone planning a database on this provisioner, the practical question is not whether ReadWriteMany is supported but whether your nodes already share a filesystem.
A helper pod runs on the nodes Kubernetes wants to drain
The configuration is a ConfigMap holding four things: a JSON configuration file, a pod template, and two shell scripts named setup and teardown. The template is the interesting one, because the file says the helper pod is allowed to run on nodes experiencing disk pressure, despite the resource constraints that usually come with that state, and that when it runs there it can carry out cleanup tasks to free space in claims. So the component responsible for reclaiming space is a pod that Kubernetes would otherwise be trying to relieve of load. That is a deliberate trade and worth naming out loud: the mechanism that keeps a full node usable is also the mechanism that can delete data to do it.
Three Kubernetes versions across three files
The requirement line says Kubernetes 1.12 or newer. The module file requires the client libraries at the 0.33.2 line across the API, the machinery and the client, plus the external provisioner library at v11. The build image pins a command line client at v1.35.1 and a local cluster tool at v0.32.0, both downloaded only when the build architecture is amd64 or arm64. So the documented cluster floor, the libraries the binary is compiled against and the tool used to drive the tests all name different releases, and the test client is two minor versions ahead of the libraries. The same pattern shows up in Go: the module declares one patch release and the base image ships the next.
The install command pins a tag and every example tracks a branch
Installation offers two routes, a stable one and a development one, and each is available as a plain manifest URL or as a kustomize build piped into the cluster tool. The stable pair pins the release tag:
kubectl apply -f https://raw.githubusercontent.com/rancher/local-path-provisioner/v0.0.37/deploy/local-path-storage.yamlThe usage section that follows then reaches for raw URLs on master for the claim, the pod, and both deletions. So a reader who installs the pinned release and then copies the examples is running a tagged provisioner against branch-tracking manifests, and the kustomize forms in the usage section pin master too. Nothing in the file flags the difference, and it is the kind of mismatch that only shows up months later, when the examples have moved on and the tag has not.
Five build stages, and the shipped binary starts from nothing
The build is a chain of container stages. The base image installs the Go toolchain plus curl, git, jq, make, vim and the Docker client, then downloads three pinned tools and installs the linter by piping a remote install script into a shell. The build stage runs one script, the test stage another, and the validate stage a third before touching a sentinel file. The final images start from an empty base and copy only the built binary directory in, with the continuous-integration variants copying from the validate stage rather than the build stage, so a CI binary cannot exist unless the tests and the validation both passed. Two details follow from that empty base: the shipped binary carries no shell, which is why the end-to-end tests run inside the build image, and the version of the linter is pinned while the script that installs it comes from a branch.
A bare make needs Docker, and the end-to-end run mounts the Docker socket
Every target in the build file shells out to a container build, and the default goal is build, test and package in that order, so nothing compiles on the host. The end-to-end target is the most interesting: it runs a preflight script, builds a separate CI image, then starts a container with the host's Docker socket mounted inside it and the repository mounted at a working directory, so a test can create sibling containers through that socket. It passes the invoking user's id and group so that files the run creates can be given back afterwards, and it also passes a Drone tag variable that belongs to the continuous integration system rather than to a local target. The CI image tag falls back to a fixed word when the short commit cannot be read.
Editorial conclusion
This provisioner fits a cluster where the nodes already have disk, where losing a node means losing its data anyway, and where running a distributed storage system would be more machinery than the problem deserves. Four things to know before you adopt it. Persistence here means surviving pod deletion, not surviving claim deletion: deleting the claim deletes the directory on the node, and a node loss takes the data with it regardless. Capacity limits are not enforced, so a claim asking for a large volume will get whatever the node has. Placement across multiple paths on one node is random, so do not plan capacity around a specific path. And ReadWriteMany only works if every node mounts the same filesystem, which is a cluster-level decision this component does not make for you.
Frequently asked questions
What is the Local Path Provisioner in Kubernetes?
It gives Kubernetes nodes their local storage back: based on your configuration it creates a persistent volume on a node automatically, backed either by a host path or by a local volume. It builds on the Kubernetes local persistent volume feature but presents itself as simpler than the built-in one, since the upstream local volume provisioner cannot dynamically provision local volumes.
how to install local path provisioner
Apply the deployment manifest, for the stable line with kubectl apply -f against the raw URL for tag v0.0.37, or build the same deploy directory with kustomize and pipe it into kubectl. The provisioner installs into the local-path-storage namespace and stores data under /opt/local-path-provisioner on each node by default.
Does the Local Path Provisioner enforce storage quotas?
The README lists exactly one limitation, that there is no support for the volume capacity limit and that the limit will be ignored for now, while its own worked example displays a two gibibyte capacity on both the volume and the claim. An examples directory named for quota exists in the tree, and the text visible here does not describe it.
Which access modes does the Local Path Provisioner support?
Single writer, many readers and many writers, but many-writer access only when a shared filesystem path is configured, meaning a filesystem mounted on all nodes at the same time. Without that setting the volumes are node-local.
What happens to data when a claim is deleted?
The content stored on the node is cleaned up automatically and the provisioner log has the details. The worked example shows the reclaim policy as Delete, so the persistence this component offers is against pod deletion rather than against claim deletion.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rancher-local-path-provisioner)Star history chart for your README
[](https://hysenlabs.com/projects/rancher-local-path-provisioner)Was this useful?