Roboflow's tracker benchmark table is stored three times, and the comment says to update all of them
Trackers gives you clean, modular re-implementations of leading multi-object tracking algorithms released under the permissive Apache 2.0 license. You combine them with any detection model you already use.
At a glance
- What is it?
- trackers is a Python library of clean-room multi-object tracking implementations that plug into any detector through one detection container. Its README is unusually candid for a benchmark page: one dataset's numbers come from ground-truth boxes, the top scorer needs three heavy optional dependencies, and the results table is duplicated across three files on purpose.
- Who is it for?
- trackers is worth a look if you want tracking you can read and modify rather than one you have to accept, and the uniform update method is the reason switching algorithms is a one-line change. Three things to weigh.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
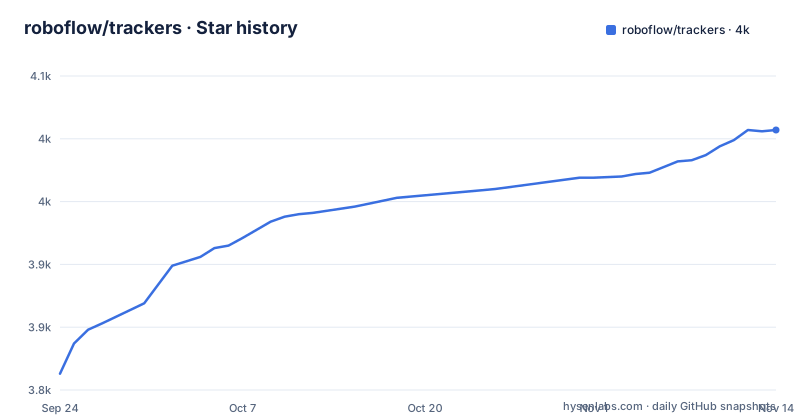
Star history
- roboflow/trackers4,007 ★ · +194
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| roboflow/trackers | 3.8k | 4k |
194 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The benchmark table is stored three times on purpose
Above the results table sits an HTML comment that reads like a maintenance note written by whoever last hit this problem. It records that the table is a copy of a results file under the documentation, restricted to one metric column across all six algorithm rows, and that the same six rows are also duplicated in the documentation's own landing page. Then it gives the procedure: update the source results file first, then mirror both copies. Three files, one table, and a stated order of operations. That is a reasonable answer to a real problem, since a published table that disagrees with its own documentation is worse than one table that is out of date, and it is also an admission that the readme cannot be regenerated from the documentation and will drift unless somebody follows the comment. The readme badge row has its own small duplication, with the same package version badge twice.
One dataset was scored against ground-truth boxes
The note under the table is the most important line in it. All scores use default parameters on the standard split, and detections come from one detector family on three of the four datasets, but on the fourth they come from oracle ground-truth boxes, with the explicit warning that absolute numbers shift with detector quality. That means the column for the football dataset is not measured the same way as the other three, and it is the column where the numbers look best for every algorithm. Reading a single score out of this table without noticing that line will lead to the wrong conclusion about which tracker to pick, which is presumably why the line is there. The project also publishes tuned numbers and methodology elsewhere for anyone who wants the comparison done properly.
Appearance and re-identification branches are left out
The paragraph above the table says each tracker is a faithful implementation of its original paper's motion and association pipeline, and that appearance or re-identification branches are not included where the papers offer them, with a pointer to each tracker's documentation page for the exact scope. That is the single most useful sentence for an adopter, because several of these algorithms are known for a second network that re-identifies objects after a long occlusion, and a library that skips it is making a deliberate trade rather than an omission. The README is also explicit that the strongest scores come from default parameters, and that one tracker is benchmarked with defaults only by design, which is a coherent reason to publish a table that is easy to reproduce. The terminal route is one command, with the source, the output file, the detector, the tracker and two display flags all named:
trackers track \
    --source video.mp4 \
    --output.video output.mp4 \
    --detection.model rfdetr-medium \
    --tracker bytetrack \
    --show.labels \
    --show.trajectories
The page notes the source can also be a webcam feed, a network stream or a directory of images, and that the command handles detection, tracking and annotated output together, so no script is needed.
The winning entry needs three dependencies you do not get
The last row is bolded because it tops all four columns, and it has a footnote explaining the catch. It adds propagated segmentation masks as a matching cue, which is where the accuracy comes from, and it needs a machine-learning framework plus two segmentation models that are optional extras rather than default dependencies. So the headline row is not comparable to the rows above it on a default install, which is a reasonable thing for a project to do provided it says so, and it does say so in the same sentence as the numbers. It is also why the column values for that row, which are between six and twenty points above the baseline, should be read as an upper bound on what the hardware-light configuration will give you.
The licence is the pitch, and a competitor is named
The second item on the list of reasons is a licence, and the wording is unusually direct for an open source project. The point is that the library is under a permissive licence with no copyleft, so it can be shipped inside closed-source products, and the contrast is a named copyleft alternative in the same space. The library's own terms match the claim: the metadata declares the same permissive licence with a matching classifier, and the readme badge for the licence file points at a path on a release branch rather than at the default branch, so the terms being linked are the ones on the stable release line. Everything else in the list is a capability claim, and the licence claim is the only one that is not about tracking at all.
The manifest caps its command line parser and explains why
The dependency list is eight entries, and seven of them use ordinary lower bounds. The eighth is different: the library that builds the command line interface is required at a floor and a ceiling, and the comment beside the line says the parser subclasses private internals of that library's yes-or-no action type, with an instruction to re-verify the cap before raising it. That is a dependency pin that documents its own expiry condition, which is rarer than it should be. The rest of the runtime list is what you would expect for a computer vision library: a numeric stack, an array library, an OpenCV build, the detection container this library speaks, a serialisation helper, an HTTP client, a terminal formatting library and a deprecation helper. The optional extra for detection pulls a named model distribution package.
The same organisation supplies the core dependency and the detector
The pitch is detector-agnostic: any model that produces boxes will do, with two families named as examples. The dependency list complicates that slightly. The detection container this library speaks natively, and the optional extra that installs model distributions, are both published by the same organisation that maintains this library, and the quick start uses a third package from the same organisation as the detector, with a note that it is not part of the base install. None of that makes the interface less open, and a third-party detector that produces the same container will work. It does mean the easiest path from the readme to a working example goes through the vendor's own packages, which is a reasonable default and a fair thing to keep in mind when the abstraction is the point.
The manifest version is behind the newest release
The package metadata says 2.6.0 and the newest release tag is 2.6.1, so a source install and an index install can differ by a patch release. The three most recent tags also tell a small story about how this project publishes. The newest is a maintenance release, the one before it added two named features in its title, and the third is a post-release of a version that was already out, with the title explaining that the package was re-released. A post-release tag is a packaging fix rather than a code change, and having one in the recent history means the published artefact and the source tree are maintained with slightly different habits, which is exactly the situation in which a version lag like this one lingers.
Editorial conclusion
trackers is worth a look if you want tracking you can read and modify rather than one you have to accept, and the uniform update method is the reason switching algorithms is a one-line change. Three things to weigh. The appearance and re-identification branches of the original papers are not implemented, so the comparison is motion-and-association only. The published scores are default-parameter numbers, and one of the four datasets was scored against ground-truth boxes rather than detections, so its column is not comparable with the others. And the highest scoring entry needs a machine-learning framework plus two segmentation models that are not installed by default.
Frequently asked questions
What does roboflow trackers do?
It provides clean-room Python implementations of six multi-object tracking algorithms behind one interface, taking detections from any model and returning tracked detections. Every tracker exposes the same update method, so switching algorithms is a one-line change.
Which tracking algorithms does roboflow trackers implement?
SORT, ByteTrack, OC-SORT, BoT-SORT, C-BIoU and McByte, each re-implemented from its original paper's motion and association pipeline, with appearance and re-identification branches left out.
Can I run roboflow trackers from the terminal?
Yes. The track subcommand takes a video, a webcam feed, a network stream or a directory of images and writes annotated output, with flags for the detection model, the tracker and what to display.
What license is roboflow trackers under?
The Apache licence version 2, and the readme makes the absence of copyleft a selling point, naming a copyleft alternative in the same space as the contrast. The package metadata declares the same licence with a matching classifier.
How do I benchmark a tracker in roboflow trackers?
The evaluate subcommand computes the CLEAR, HOTA and identity metrics against ground-truth annotations and prints a per-sequence breakdown, and the readme publishes HOTA results for four datasets at default parameters.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/roboflow-trackers)Star history chart for your README
[](https://hysenlabs.com/projects/roboflow-trackers)Was this useful?