RubixML licenses its code permissively and its documentation non-commercially
A high-level machine learning and deep learning library for the PHP language.
At a glance
- What is it?
- A PHP machine learning library covering the full lifecycle from data preparation through training and cross-validation, with a recommended fast path that compiles a Fortran and BLAS toolchain. The licence split is the detail most likely to surprise you, and the optional-extension design is the detail most likely to confuse you at runtime.
- Who is it for?
- Adopt this if your stack is PHP and you would rather not cross a language boundary to train a model, which is a real constraint in a lot of small teams. Two things to check before you commit.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 19 days ago.
- What is it written in?
- Mainly PHP, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
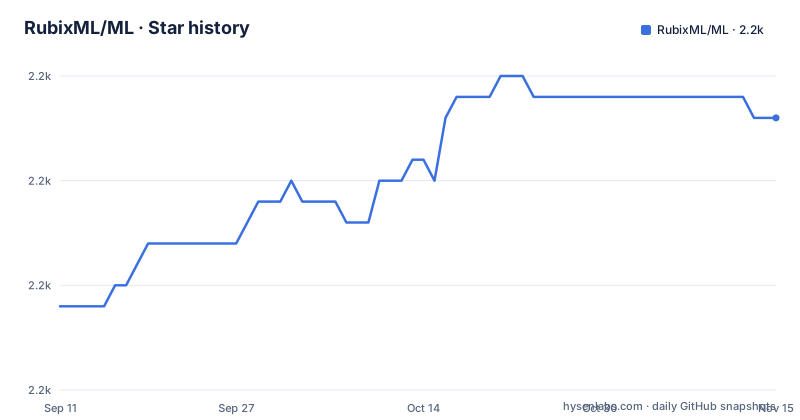
- RubixML/ML2,213 ★ · +9
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| RubixML/ML | 2.2k | 2.2k |
9 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install is one line and the fast path is a compiler toolchain
There are two install paths on the page, and the difference between them is larger than the page suggests.
The first is a single Composer require. That gets you the library on a recent PHP, with no compilation step.
The second is what the page calls optional for best performance, and it is a systems dependency list. On an Ubuntu system it installs a C compiler, make, a Fortran compiler, development headers for two linear algebra libraries, a lexer generator, and build essentials. It then uses a separate PHP extension installer to compile two recommended extensions, a tensor extension for fast matrix and vector work and a coroutine extension for multiprocessing.
So the fast path is a Fortran and BLAS toolchain plus two compiled PHP extensions. That is a real cost on a managed host where you cannot install system packages, and it is the kind of cost that is easy to discover only after you have already deployed.
The README does frame it as optional, and on a machine you control the Composer line alone is genuinely enough to get started.
The short version is one line:
composer require rubix/mlSeveral algorithms live in optional PHP extensions
The requirements list separates what you must have, what is recommended, and what is optional, and the optional column is longer than you would expect.
Among the optional items are an extension backed by an SVM library, which is how support vector machines are served. There is an image extension, a multibyte string extension, a database driver, and a separate graph visualisation program.
That last group is the interesting one. A reader sees support vector machines in a feature list and reasonably assumes the library contains them. In this design, the algorithm is only present if a particular PHP extension is installed, and the extension list does not map extensions back to algorithms.
So the failure mode is quiet. Nothing errors on install; a class is simply unavailable, or a method throws something unrelated, and the connection between the symptom and the missing extension has to be inferred from a requirements list at the top of a different page.
For a library whose selling point is breadth, more than forty algorithms, this is the gap worth closing first.
Two version lines are in flight at once
The release list is short and it shows a project in the middle of a major transition.
The three most recent releases are two release candidates on version three, twelve days apart, and one maintenance release on version two. The ordering has a wrinkle worth naming: the second release candidate and the version two maintenance release went out on the same day, with the maintenance release about twenty hours after the candidate.
So the stable line is being patched while the next major line is in candidates. That is normal practice and it means the two lines move independently for a while.
For a library someone is going to depend on, the practical question is which line to require. The maintenance release on version two has the virtue of being stable and supported now; the candidates are where new work lands and where a breakage is still likely.
Nothing on the page states a compatibility policy between them, so there is no guidance on the question the version list implicitly raises, which is whether the next major will need code changes on your side.
The examples are the canonical teaching datasets
Thirteen example projects are listed, and reading the list as a set tells you what the project is optimising for.
Most are the standard tabular teaching sets: the iris flower dataset, the Titanic survival table, a housing price table, a credit default table, a customer churn table, and a divorce prediction table. The vision examples are the equally canonical image recognition sets, one for handwritten digits and one for small object photographs. The colour clustering example is the sort of unsupervised demo that makes the difference between classification and clustering legible.
Then three that are not canonical. There is a DNA taxonomy example, a human activity recognition example, and a game outcome predictor for a specific competitive title.
Twelve of the thirteen are hosted under the project's own organisation. The thirteenth, the Titanic walkthrough, points at somebody else's account, so it is a community contribution rather than maintained example code.
The page says many come with instructions and a pre-cleaned dataset. That is the tell: these are teaching artefacts, chosen so a beginner gets to a working model in an afternoon, not templates for production. Useful, but do not mistake the list for evidence that the library handles real messy data well.
The documentation carries a non-commercial term
The licence section splits the project in two, and the split is easy to miss.
The code is licensed under MIT. The documentation is licensed separately under a Creative Commons licence carrying a non-commercial term.
That combination means you can use the library in a commercial product without owing anything, and you still cannot republish its documentation commercially. For most teams the code licence is all that matters. For anyone building internal training material, or translating the guides, or redistributing them with a product, the second licence is the one that applies.
The subtlety is that the project's own summary describes it as open source and free to use commercially, with no qualification. Read strictly, that sentence is true of the library and not of everything shipped in the repository.
None of this is unusual in open source; plenty of projects license documentation differently from code. It is worth stating plainly because the documentation is the part most teams copy from, and it is the part with the restriction.
A smaller inconsistency sits next to it: the badge row links a licence file with a documentation extension, while both the root listing and the licence section itself use the plain name.
There is a benchmark harness in the repository
The root listing contains four separate configurations for analysis and formatting, and one directory whose purpose is measurement.
The four are a code formatter, a linter, a static analyser configuration, and a lint configuration for the documentation. That is thorough for a library of this size, and having the documentation lint separately from the code suggests the docs are treated as maintained source rather than as an afterthought.
The directory is the benchmark harness, with its own configuration file alongside it.
A PHP machine learning library shipping its own benchmarking setup is unusual. Most libraries in this space, in any language, publish no benchmarks at all and let you infer performance from the issue tracker. Having a harness checked in suggests the maintainers measure rather than assert, which is the single best signal you can have about whether a performance claim is worth anything.
It also means you can run the same measurements on your own hardware before choosing it, which is worth more than any number in a readme.
The rest of the tree is conventional: the source directory, a tests directory, the Composer manifest, a docs directory with a documentation site configuration, a changelog, a contribution guide, and an instructions file for coding agents.
Editorial conclusion
Adopt this if your stack is PHP and you would rather not cross a language boundary to train a model, which is a real constraint in a lot of small teams. Two things to check before you commit. Several capabilities live in optional PHP extensions rather than in the library, so verify that the algorithms you need have the extensions they depend on, because the missing-algorithm case is otherwise hard to diagnose. And note that the permissiveness you are buying with the MIT code licence does not extend to the documentation, so plan how you will handle that separately if you redistribute training material.
Frequently asked questions
What is Rubix ML?
It is a high-level machine learning and deep learning library for PHP, covering the lifecycle from data extraction and preprocessing through training and cross-validation to production, with over forty supervised and unsupervised algorithms. The project describes itself as open source and free to use commercially.
What does Rubix ML require to run?
PHP 8.3 or newer. For the fast path it also recommends a separate tensor extension for fast matrix and vector computing and a coroutine extension for multiprocessing, both of which have to be compiled rather than downloaded.
Does Rubix ML need compiled libraries?
For best performance, yes. The documented Ubuntu line installs a C compiler, make, a Fortran compiler, development headers for two linear algebra libraries, a lexer generator and build essentials, so the numeric stack is compiled rather than shipped as pure PHP.
Why might an algorithm be missing from Rubix ML?
Several capabilities are optional PHP extensions rather than bundled code, including support vector machines, image handling, multibyte string handling, database access and graph visualisation. The requirements list notes these as optional without mapping them to the algorithms that need them.
Can I use Rubix ML commercially?
Yes for the code, which is MIT licensed. The documentation is licensed separately under a Creative Commons licence carrying a non-commercial term, so if you plan to republish or adapt the guides that second licence is the one that applies.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rubixml-ml)Star history chart for your README
[](https://hysenlabs.com/projects/rubixml-ml)Was this useful?