EasyModelAnalysis.jl answers model questions with one line each
High level functions for analyzing the output of simulations
At a glance
- What is it?
- A Julia package that turns a symbolic ODEProblem into answers about threshold times, exceedance probability, sensitivity and parameter fits. Its own demonstration spends most of its lines building the problem, which tells you what the package actually consumes.
- Who is it for?
- EasyModelAnalysis.jl fits a modeller who already has a symbolically-defined system and wants extrema, threshold times or parameter fits without writing the sampling, root-finding or optimisation by hand, and who is already using ModelingToolkit and DifferentialEquations. It does not fit someone arriving with arrays of numbers: the examples pass an ODE problem and symbolic variables, so the modelling stack is a prerequisite rather than a convenience.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Julia, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
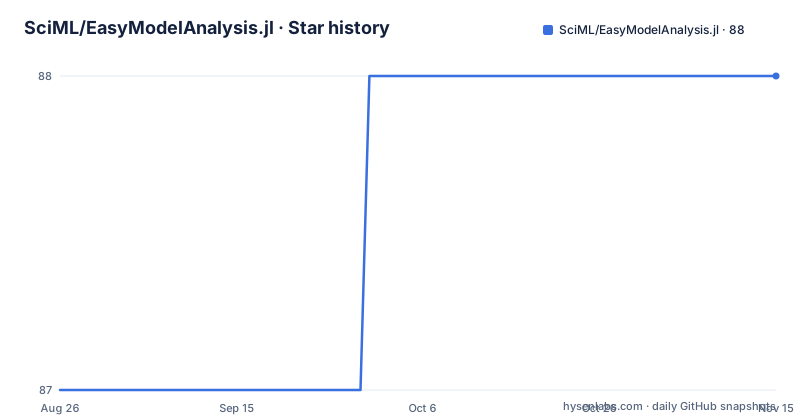
- SciML/EasyModelAnalysis.jl88 ★ · +1
| Repository | 2026-08-26 | 2026-11-15 |
|---|---|---|
| SciML/EasyModelAnalysis.jl | 87 | 88 |
1 Stars in the last 81 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four questions, and the README shows the answer to two of them
The pitch is four questions asked in plain English and answered with one line each. When is the first time the number of infected individuals reaches about 1000. What is the probability that more than 50 people will be infected, given probability distributions for the parameters rather than fixed values. Which variables is the model most sensitive to. And which parameters best fit the model to a set of data.
All four are described as simple one-liner queries over SciML-defined differential equation models. That last clause is the whole contract: the input is a model defined in the SciML ecosystem, not an array.
The gap between the pitch and the page is that only two function calls are actually shown, `phaseplot_extrema` and `plot_extrema`. Both are about extrema. Nothing on the page demonstrates the threshold-time call, the probability call, the sensitivity call or the fitting call, so the mapping from three of the four questions to a function name has to come from the documentation rather than the README.
For a package whose selling point is one-liners, that is the first thing to check: which of your questions is actually one of the two on the page.
Most of the demonstration is the modelling stack, not this package
The quick demonstration is worth reading as a whole, because the proportion matters. Of its body, EasyModelAnalysis contributes the last two lines:
using DifferentialEquations, EasyModelAnalysis, ModelingToolkit, Plots

@parameters t σ ρ β
@variables x(t) y(t) z(t)
D = Differential(t)

eqs = [D(D(x)) ~ σ * (y - x),
    D(y) ~ x * (ρ - z) - y,
    D(z) ~ x * y - β * z]

@named sys = ODESystem(eqs)
sys = structural_simplify(sys)

u0 = [D(x) => 2.0,
    x => 1.0,
    y => 0.0,
    z => 0.0]

p = [σ => 28.0,
    ρ => 10.0,
    β => 8 / 3]

tspan = (0.0, 100.0)
prob = ODEProblem(sys, u0, tspan, p, jac = true)

phaseplot_extrema(prob, x, (x, y))
plot_extrema(prob, x)
What the page is really demonstrating is compatibility with the full symbolic pipeline. The system is declared symbolically, simplified with `structural_simplify`, and initial conditions are given as a pair array in which the derivative `D(x)` is set alongside the state variables. The problem is constructed with `jac = true`, so the analysis runs against a problem built with a Jacobian.
If you already build problems this way, the two analysis lines are unremarkable. If you do not, this package is not the first piece you need.
The API shape is problem first, then symbolic variables
Both calls shown take the ODE problem as the first argument and a symbolic variable as the second. `plot_extrema(prob, x)` asks about one variable. `phaseplot_extrema(prob, x, (x, y))` passes the variable to track and then a pair of variables for the phase view, which is the pair that makes the second plot a trajectory rather than a time series.
That signature is the design decision that distinguishes this from a statistics package. Nothing converts a solution into arrays and hands them to a curve-fitting routine. The symbolic variables are resolved against the system that produced the problem, so the answer refers to `x` as the system declares it rather than to a column name you chose.
It also explains the setup cost. The example constructs `prob` from a symbolic system after a simplification pass; it does not explicitly solve the problem before calling the analysis functions. The README does not state which functions require the symbolic variables rather than plain arrays, whether any function accepts a solution directly, or what happens for a problem built without `structural_simplify`. Those are documentation questions, not design flaws.
Two documentation builds, and dev is ahead of the latest tag
The page points at two documentation URLs and the difference between them matters when you are debugging. The stable documentation at `docs.sciml.ai/EasyModelAnalysis/stable/` describes what is released. The in-development documentation at `docs.sciml.ai/EasyModelAnalysis/dev/` is explicitly the version carrying unreleased features.
So the dev docs will describe functions that the version you have installed does not have. If you follow a dev example on a stable install and get an undefined name, check which documentation build you are reading before you assume the package is broken.
The release history explains why. Three tags are published: v1.0.0 on 2024-05-13, v1.1.0 on 2024-10-10 and v1.1.2 on 2026-06-25. That is a version gap of more than a year between 1.1.0 and 1.1.2, and the last push to the default branch was on 2026-09-28, three months after the newest tag. So main carries work that no release has shipped, which is the normal state for an actively developed package and also the reason the two documentation builds exist.
Nothing on the page names a minimum Julia version; the supported range is in the `Project.toml` compat block.
Ten top-level entries, and a benchmark directory of its own
The repository is small in a way that tells you the shape of the work. Ten entries: `.github/`, `.gitignore`, `.typos.toml`, `LICENSE.md`, `Project.toml`, `README.md`, `benchmark/`, `docs/`, `src/` and `test/`.
A few details are worth noting. `benchmark/` is a top-level directory with the singular name, sitting alongside the source rather than inside it, so performance work is part of the repository's remit and not an afterthought in a script. `.typos.toml` is a spelling checker configuration, which in a package with a `trading_signal` field and a `signifier` vocabulary is a real cost to maintain, and this project has chosen to pay it. `LICENSE.md` holds the MIT licence.
What is absent is also informative. There is no changelog file at the top level and no example directory, so the demonstration in the README is the worked example the project offers. There is a Codecov badge, so coverage is measured somewhere in the CI configuration under `.github/`, but no coverage number or test count appears in the page, and there is no badge showing the supported Julia versions either.
Discussion happens on Zulip, not in the issue tracker
The badges at the top of the page are worth reading as a signal about how to get help. The first one links a Zulip stream rather than GitHub issues or Discussions. The others point at a documentation build, a Codecov dashboard, the CI workflow list, and two SciML repositories, one for package collaboration practice and one for style.
For a Julia package this is a convention rather than a peculiarity, and it has a practical consequence: asking a usage question means finding the right Zulip stream and the right channel inside it, and the answer is unlikely to be indexed by a search engine the way an issue thread would be. If you plan to depend on this package, budget for reading rather than for asking.
The two SciML repositories at the end of that badge row are the more useful of the pair for a contributor. Style guidance being a separate repository means the conventions are written down somewhere outside the package, and collaboration practice being separate means the expectations for review and scope are as well.
Where a dataframe-based analysis is the wrong shape
The alternative to a package like this is not another Julia package, it is doing the analysis yourself on the solution arrays. That works, and it is what a lot of code does, so it is worth being explicit about what you gain by not doing it.
The gain is that these queries are model-aware. Sensitivity means something only in relation to a parameter set and a system structure, and asking which variables matter most requires resolving symbolic quantities against a system rather than correlating columns. Fitting parameters to data means running an optimisation over a parameter vector that the problem constructor understands. Each of those is a piece of machinery you would assemble from the solution array and the metadata you kept alongside it.
The cost is the dependency chain shown in the demonstration. DifferentialEquations, ModelingToolkit and Plots are imported before EasyModelAnalysis does anything, and a symbolically-indexed system has to survive `structural_simplify` before the analysis is possible. For a team already inside SciML that chain is already paid for. For anyone else, the honest comparison is against the array-based code you would otherwise keep, not against a lighter dependency.
Editorial conclusion
EasyModelAnalysis.jl fits a modeller who already has a symbolically-defined system and wants extrema, threshold times or parameter fits without writing the sampling, root-finding or optimisation by hand, and who is already using ModelingToolkit and DifferentialEquations. It does not fit someone arriving with arrays of numbers: the examples pass an ODE problem and symbolic variables, so the modelling stack is a prerequisite rather than a convenience. Verify three things before you depend on it: which release you want, since v1.1.2 shipped on 2026-06-25 while main was pushed on 2026-09-28, whether the query you need is one of the two calls in the README or one you will find in the stable documentation, and what Julia versions the package declares support for, which lives in the `Project.toml` compat block rather than on the page.
Frequently asked questions
What does EasyModelAnalysis.jl actually do?
High-level functions for analyzing simulation output from SciML differential equation models: the first time a variable reaches a given value, the probability that a threshold is exceeded given distributions for the parameters, which variables the model is most sensitive to, and which parameters best fit the model to data. Each is described as a one-line query.
Which EasyModelAnalysis.jl functions does the README demonstrate?
Two. phaseplot_extrema(prob, x, (x, y)) takes the problem, a variable to track and a variable pair for the phase view, and plot_extrema(prob, x) takes the problem and one variable. Both take a solved problem and symbolic variables.
What do I need installed to use EasyModelAnalysis.jl?
The modelling stack rather than this package alone. The demonstration imports DifferentialEquations, EasyModelAnalysis, ModelingToolkit and Plots, and builds the problem from a symbolic ODESystem passed through structural_simplify, with the ODEProblem constructed using jac = true.
Which EasyModelAnalysis.jl version should I install?
Three tags are published: v1.0.0 on 2024-05-13, v1.1.0 on 2024-10-10 and v1.1.2 on 2026-06-25, and the last push to main was on 2026-09-28. The stable documentation describes the released version while the dev documentation explicitly carries unreleased features.
What licence does EasyModelAnalysis.jl use?
MIT, recorded in a LICENSE.md file at the top level of the repository alongside Project.toml, src/, test/, docs/ and benchmark/.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sciml-easymodelanalysis-jl)Star history chart for your README
[](https://hysenlabs.com/projects/sciml-easymodelanalysis-jl)Was this useful?